Monster Scraper for Job Postings and Employer Data

Monster has run as a US job board since the 1990s and now sits under BOLD alongside CareerBuilder, which means the same posting often appears on both boards at once.

Plans from €169 a month · Free project assessment · Reply within 1 business day

CSV · Excel · JSON · XML · FTP · SFTP · Amazon S3 · Google Cloud

monster.com
Monster Scraper for Job Postings and Employer Data
monster.comwhat you get
Typical fields for job boards
job_titlecompanylocationsalaryemployment_typeposted_at
Delivery

API, JSON feed or CSV, XLSX and JSON files

Schedule

One-time, monthly, weekly, daily or 3 times a day

How the Monster Scraper Runs

  1. You send

    Monster pages, filters, fields and a schedule

  2. We run the scrapers

    Built, monitored and repaired by our team

  3. You receive the data

    API, JSON feed or CSV, XLSX and JSON files

You describe the slice of Monster jobs you need: titles or keywords, locations, which country sites, and how often it should refresh. We build the crawler, run it on our infrastructure and maintain it when the markup moves. Nothing is installed on your side.

Delivery is CSV, JSON, XLSX or an API endpoint, on a schedule you set. These are scheduled crawls, not a live feed. A daily run gives you a daily snapshot, and we will state the expected lag for the cadence you pick rather than calling it real time.

Each delivery ships with a row count, a field-fill report and a note on anything the crawl could not reach in that period.

Monster answers unrecognized clients with a block page, and getting past that reliably is our work rather than yours. Anti-bot handling, proxy rotation and CAPTCHA solving come with the service, so nothing on your side has to deal with them.

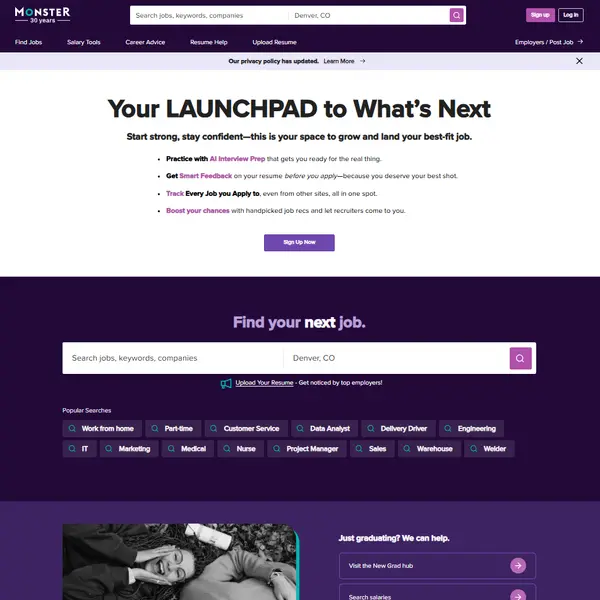
Fields We Extract From Monster Job Postings

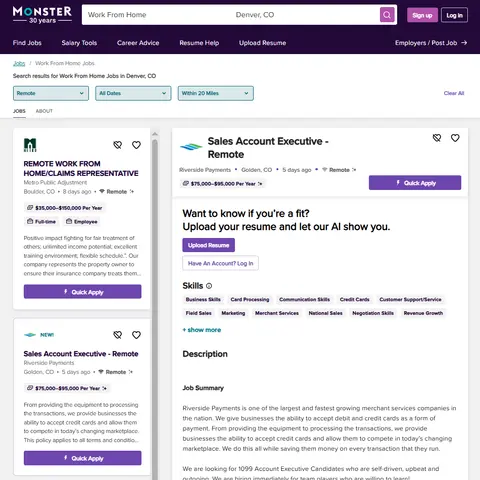
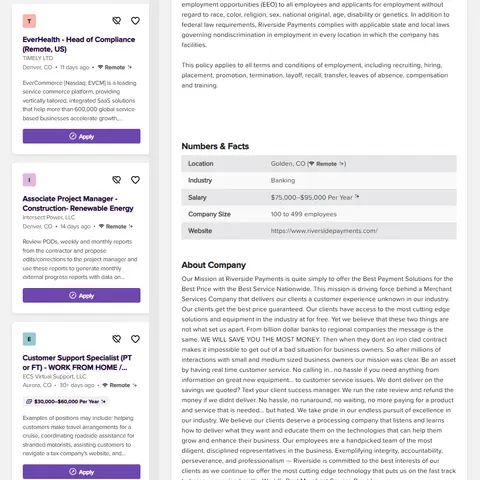
A Monster posting exposes a predictable set of public fields. We take what the page actually publishes and leave a column empty rather than guessing at it.

  • Job title as the employer wrote it, with a normalized column alongside it if you want one.
  • Company name and the employer profile URL where the posting links to one.
  • Location split into city, state and country, plus any remote or hybrid label the posting carries.
  • Employment type where the employer selected one.
  • Posted date and the posting age text as the page renders it.
  • Full job description in both plain text and the original HTML, so bullet structure and formatting survive.
  • Salary only where the posting states it. Many Monster jobs state nothing, and that field stays blank rather than being filled with an estimate.
  • Job URL and job id. Monster job pages sit under /job-openings/ with a title and location slug followed by a UUID, and we keep that UUID as the primary key.
  • Apply destination as published on the posting, so you can see whether the employer routes applicants off-site.
  • Capture timestamp and the search query or filter that surfaced the row.

What we leave out is as firm as what we collect. Output is limited to posting and employer data. Recruiter email addresses, direct phone numbers and other personal contact routes are excluded by default, not on request, and we do not build person-level records from these pages. Candidate profiles and resumes sit behind a Monster login, and we do not collect them.

Fields We Extract From Monster Job Postings
Coverage, Duplicates and What Limits the Crawl

Coverage, Duplicates and What Limits the Crawl

Country sites are separate indexes. Monster runs national sites outside the United States, and they hold their own postings rather than mirroring the US board. Asia Pacific and the Middle East are a different case: Quess Corp bought that Monster business in 2018 and rebranded it as foundit in late 2022, so foundit.in and its sister sites are no longer Monster. We scope each country explicitly so nobody assumes coverage that is not there.

Duplicates come from three directions. The same advertisement can appear on Monster and CareerBuilder through the shared posting product, one employer can run near-identical listings in nearby cities, and postings are fed in from applicant tracking systems in batches. We deduplicate on the job id first, then run a configurable second pass on employer, title and location.

Closed postings stop being addressable. A Monster listing that has expired is not a stable public page you can re-fetch, so a longitudinal record has to capture each posting while it is live. We build that as an append-only history with a first-seen and last-seen date per job id.

Narrow queries set the shape of the crawl. Deep coverage is assembled from many narrow keyword and location queries rather than walking one result set to an arbitrary depth, and every row keeps the query that surfaced it.

What Monster Is Now, and Who Owns It

Source
monster.com
Category
job boards
Delivery
API, JSON feed, CSV, XLSX
Plans
From €169 a month
Get a quote

Monster is a United States job board that has been online since the 1990s. That age matters: it is a name candidates still recognize, even where employers have moved budget elsewhere. Its ownership then changed twice in under a year. In September 2024 Monster and CareerBuilder were combined into a single business, with Apollo Global Management holding the controlling stake and Randstad a minority position. In June 2025 that combined business, CareerBuilder + Monster, filed for Chapter 11 and opened a court-supervised sale.

The auction did not go to the opening bidder. JobGet was the stalking horse, and BOLD outbid it. The sale transactions closed on July 31, 2025. BOLD took the job board business along with the rights to both the Monster and CareerBuilder brands. Monster Media Properties, which covers military.com and fastweb.com, went to Iron Corp U.S. Inc. Monster Government Solutions went to PartnerOne. BOLD confirmed completion on August 1, 2025 and said both boards would keep running as standalone brands. BOLD also operates Zety, LiveCareer, MyPerfectResume and FlexJobs.

Two things follow for anyone buying Monster data. monster.com is still live and still carries current postings, so the index is real and worth crawling. But the edge of the brand moved. military.com and fastweb.com are no longer Monster properties, and the government HR software sits with a different owner now. Our Monster scraper targets monster.com and nothing else unless you ask for more.

25Developers
500+Customers
1.5BPages extracted
15,000+Hours saved for our clients

Monster scraping plans and pricing

Airplane

€199one-time

Setup fee included

100,000
One-time
Up to 5 days
7 days

Helicopter

€169/ mo

Setup fee €499

250,000
Monthly
Up to 5 days
14 days

Glasses

€229/ mo

Setup fee €499

1,000,000
Weekly
Up to 5 days
30 days

Microscope popular

€349/ mo

Setup fee €499

2,000,000
Daily
Same day
60 days

DNA

€549/ mo

Setup fee €799

3,000,000
3 times daily
Same day
90 days

Delivery: CSV, JSON or XLSX files, our API or a JSON feed. MCP server on request.

Full plan details

Why Teams Scrape Monster

Monster is not the largest US index and we will not sell it as one. It earns its place for narrower reasons.

The employer mix skews to established firms. Staffing agencies, healthcare systems, logistics operators and long-established regional employers keep posting on Monster after they have stopped paying for newer boards. If your market map is built only from the high-traffic aggregators, those employers are underweighted in it.

Overlap with CareerBuilder is now measurable. Monster's own employer pricing page states that a posting is published to Monster, CareerBuilder and a partner network. Crawling both boards and matching on employer, title and location tells you which listings are one advertisement and which are two separate campaigns.

The ownership change is a research question in itself. Posting volume, employer mix and listing freshness on Monster in 2026 are not what they were in 2023. If you are tracking where US job advertising went after the Chapter 11 sale, Monster data is direct evidence rather than commentary.

None of this needs personal data. Every use above runs on postings and employers, which is the only thing we deliver.

Working With ScrapeIt

ScrapeIt is a managed scraping team. We build the crawlers, run them, repair them when a site changes, and hand over clean data. You maintain no code and no proxies.

We are not affiliated with Monster or BOLD and we do not claim to be. We collect only publicly available data - everything a visitor can see on Monster - and we collect it legally, never reaching anything behind a login.

FAQ

Still unsure? Write to info@scrapeit.io

Do you offer a Monster API for job data?

Yes. The ScrapeIt Monster API returns job title, company name, location, employment type, stated salary and posted date as JSON from an endpoint we host, refreshed on the schedule you set. The same data also comes as CSV or XLSX files or straight into your database.

Do you provide recruiter email addresses from Monster?

No. Output is limited to posting and employer data. Recruiter emails, direct phone numbers and other personal contact routes are excluded by default rather than on request, and we do not assemble person-level records. Under the GDPR, information identifying a named recruiter is personal data, so we keep it out of the dataset entirely.

Can you scrape Monster resumes or candidate profiles?

No. Monster's resume database and candidate profiles sit behind a login, and we never log in. We do not collect them and we do not offer them. Our Monster scraping covers public job postings only.

How current is the Monster data you deliver?

As current as the schedule you choose. We run scheduled crawls, not a live stream. Daily, weekly and monthly runs are all normal, and higher frequencies are possible for narrow slices. We state the expected lag for your cadence before the project starts. Listings that close between runs are marked with a last-seen date rather than silently dropped.

Will I get duplicate jobs between Monster and CareerBuilder?

You can, and we would rather say so up front. Both boards now sit under BOLD, and Monster's employer pricing page states that a posting is published to Monster, CareerBuilder and a partner network. If we crawl only Monster you get one row per Monster posting, keyed on the job UUID. If we crawl both, we can keep the two rows and flag the match, or collapse them into one, whichever suits your analysis.

How it works

  1. 1

    Make a request

    You share your needs, expectations, and desired timeframe. We'll suggest the best solution based on your request and budget.

  2. 2

    We configure the crawlers

    Our specialists configure the crawlers and extract a sample dataset for your review before proceeding with the full-scale extraction.

  3. 3

    Collect and deliver

    Once you approve the sample, we launch the project and start full data collection. We gather, filter, and structure the data for easy use, delivering it on time in your preferred format.

  4. 4

    Maintain and support

    Our team manages ongoing processes, monitors website changes, and supports all data extraction cycles. We can also help integrate data into your systems or create dashboards to simplify analysis.

Request a quote

Tell us which sites, which fields and how often. A couple of lines is enough to start.

  • We reply within 1 business day
  • A sample dataset before the full run
  • We sign an NDA on request
  • Delivery by API, JSON feed or files
Which sites, which fields, how often. A couple of lines is enough.

This form is protected by Google reCAPTCHA, which loads when you start filling it in. If you prefer not to use it, email us at info@scrapeit.io. Privacy & Cookie Policy

We reply within 1 business day. No obligation.

Monster data from €169/month. Free project assessment, reply within 1 business day.