
Google Maps Data: Local Businesses from 1,000 US Cities Every Weekday
A weekday feed of local businesses from Google Maps for a local-marketing company: 1,000 US cities, three keywords a day, files by 10:00 UTC.
Get the data you need to strengthen your AI. Our data scraping services for AI training are ideal for building new models or improving existing algorithms. Receive datasets from an experienced team that collects, cleans, and delivers large-scale training data every day.
Plans from €169 a month · Free project assessment · Reply within 1 business day
CSV · Excel · JSON · XML · FTP · SFTP · Amazon S3 · Google Cloud
API, JSON feed or CSV, XLSX and JSON files
ScheduleOne-time, monthly, weekly, daily or 3 times a day
Train, enhance, and scale your AI-driven solutions. With our data scraper for AI, we collect structured data from multiple sources and industries to power machine learning and artificial intelligence systems - helping you improve accuracy, performance, and innovation in your projects.
Receive large, high-quality datasets from our extractor to train AI models for image recognition, text analysis, or predictive tasks.
Use clean datasets to evaluate model performance, accuracy, and reliability.
Access updated data streams that help refine and retrain your AI for better results, giving your company a real competitive edge.
We extract data for AI projects across industries - from healthcare to finance to e-commerce - enabling domain-specific model creation and helping you stay ahead of competitors.
We provide an ongoing flow of fresh AI training datasets through our automated parser, so your models continuously learn and adapt.
Use behavioral and product data to train AI that personalizes user experiences in e-commerce, entertainment, or marketing platforms.
Use scraped customer feedback, reviews, and discussions for brand monitoring and consumer sentiment analysis provided by a trusted provider.
Receive large volumes of labeled images and video data to train models for object detection, facial recognition, or autonomous systems.
Collect audio recordings and transcripts - data for AI companies that build and optimize speech-to-text, voice command, and language identification systems.
We deliver high-quality datasets designed for AI and machine learning workflows - cleaned, validated, and structured for efficient model training. Our data pipelines support multiple data modalities and industries, helping you accelerate development and improve model accuracy.
Contact usExpertly customized web scraping services at a fraction of the cost of developing your own software.
Delivery: CSV, JSON or XLSX files, our API or a JSON feed. MCP server on request.
Full plan details
A weekday feed of local businesses from Google Maps for a local-marketing company: 1,000 US cities, three keywords a day, files by 10:00 UTC.
Full MRO catalogs from Grainger, Fastenal and Cromwell for a product content company: UNSPSC, EAN, every attribute and a taxonomy sheet.
A paid pilot for a regional airport in Scandinavia: direct charter departures from 12 Danish tour operator sites, sampled in two weeks.
Every seller shop on bol.com with its trade name, business address, KvK and VAT number, collected once: 72,961 shops in 18 days.
A one-time B2B lead file from Amazon seller profiles: 51,216 sellers with business name and address, 13,366 of them in the US and Canada.
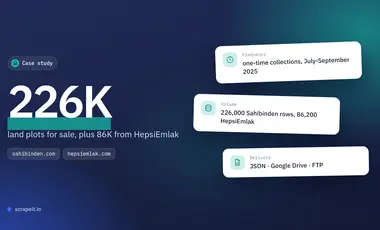
Land for sale across Turkey from Sahibinden and HepsiEmlak for a land investor: 226,000 plots in the first file and 86,200 HepsiEmlak rows.

We set up your AI data collection in just a few days - no developers or complex configurations required on your side.

Collect massive volumes of data from multiple online sources. Our system easily handles high-volume, complex, and dynamic websites.

We continuously monitor scrapers, adapt to site changes, and ensure your datasets are always delivered on time and without interruption.

Access large-scale, high-quality data without investing in expensive infrastructure or in-house maintenance.

No need to manage anything - we take care of setup, data parsing, processing, and delivery while you focus on AI development.

Our datasets are structured, complete, and reliable - ready for seamless integration into your workflows to create effective AI models.
Learn how to use web scraping to solve data problems for your organization
Where opinion text lives on the public web, what a review record contains on each kind of site, which fields a model needs besides the text, and what quietly breaks a sentiment dataset - with examples from our own projects.
Using web scraping to extract Google Maps data will help you quickly and efficiently find businesses in any industry, city, state, or region. And the extracted contact information, such as phone or email address, social networks, or links to web pages, will help to contact them.
Lead scraping is a reliable way to get the right customer contacts to market your product, saves organizations time, and helps you better understand the audience you want to attract. Contacts include emails, phone numbers, or social media profiles.
Still unsure? Write to info@scrapeit.io
Use a managed scraping service: we collect, clean and deliver training data from the sources you name, so your team works on models, not scrapers. We cover 689 websites in 16 categories; one project archived 420,000+ listings with 2.2 million+ photos, each with the saved page and a JSON file, and another delivered 226,000 property listings with 3.4 million resized images for an AI-based property search product. A one-time dataset of up to 100,000 rows costs EUR 199 and comes as CSV, JSON or Excel. Monthly plans cost from EUR 169 a month plus a one-off EUR 499 setup fee that includes the sample dataset and the first month, and add JSON Lines and delivery through our API or as a JSON feed.
We can export your AI training data in CSV, Excel, JSON, JSONLines, or XML formats. Choose the delivery method that works best for you - our API, a JSON feed, FTP, SFTP, Dropbox, Google Drive, Amazon S3, or email. An MCP server is available on request.
No limits. Our data extraction services scale to your needs - from thousands to millions of records collected from datasets, research portals, aggregators, and any other relevant sources. We deliver structured data for companies, agencies, and research teams, enabling accurate comparisons and analysis at any scale.
Our web scraper collects various public datasets for AI - including images, text, product information, financial data, and more - from online databases, publications, research papers, and web pages across the internet.
Our automation system runs the entire process. We build, test, and run scrapers in our cloud environment, monitor performance through defined endpoints, and deliver structured AI datasets on time.
Delivery time depends on the volume and complexity of your request. Most projects are completed within a few days - our team provides a clear timeline before launch.
Yes, our professional team supports you throughout the project - from setup to delivery - resolving any technical issues so you can focus on building your AI models.
We use secure proxies and parsers to extract training data reliably. With advanced data mining and automated pipelines, we ensure consistency, accuracy, and completeness across all datasets.
No setup required. Everything runs in our cloud - you just specify the data sources and parameters, and we handle the rest.
Yes. Our infrastructure supports parallel data extraction from multiple datasets, websites, and other online sources - ideal for training large-scale AI models.
Absolutely. We can sign a non-disclosure agreement to protect your research and business data throughout the project.
We support daily, weekly, or monthly updates - or a custom schedule that fits your workflow. You'll always have access to the latest, high-quality datasets for your AI development.
You share your needs, expectations, and desired timeframe. We'll suggest the best solution based on your request and budget.
Our specialists configure the crawlers and extract a sample dataset for your review before proceeding with the full-scale extraction.
Once you approve the sample, we launch the project and start full data collection. We gather, filter, and structure the data for easy use, delivering it on time in your preferred format.
Our team manages ongoing processes, monitors website changes, and supports all data extraction cycles. We can also help integrate data into your systems or create dashboards to simplify analysis.
Tell us which sites, which fields and how often. A couple of lines is enough to start.