ZipRecruiter Scraper for Job and Employer Data

ZipRecruiter sends one employer posting out to over a hundred other job sites, which is why its employer-side pages, not its posting count, are the part worth collecting.

Plans from €169/month · Free project assessment · Reply within 1 business day

ZipRecruiter Scraper
Solutions

How We Run a ZipRecruiter Project

A ZipRecruiter scraping project starts from your brief: which fields, which queries and locations, how often, and where the file lands. You review a sample extract before the full run, so the schema is agreed before any volume arrives.

Delivery is CSV, JSON, XLSX or SQL, pushed to S3 or an endpoint you name, on the schedule you set. These are scheduled crawls rather than a live feed, and the interval is written down rather than implied. We watch for layout changes, repair the parser when the site moves, and keep run history so you can see what changed between two deliveries.

The Cloudflare managed challenge on job URLs is ours to handle. Proxy rotation, CAPTCHA solving and adaptive crawling are included, and they are the reason a scheduled run keeps arriving after a one-off script has stopped working.

What a ZipRecruiter scraper can extract per posting

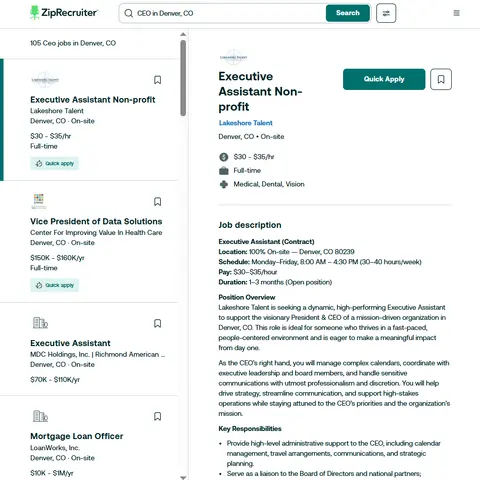
ZipRecruiter jobs are addressable at two levels. Job detail pages sit under a /c/[Company]/Job/[Job-Title]/-in-[City],[State] path, and the browsable directory pages sit under /Jobs/. From a public posting we extract:

  • Job title as published, plus the normalised title the platform files it under.
  • Company name and the link to that company's own page on the site.
  • Location as city and state, with the remote or hybrid flag where the posting sets one.
  • Employment type mapped to the platform's own vocabulary, which keeps values many boards flatten away, such as contract-to-hire, as-needed and internship.
  • Posted date and the recency the listing reported at the moment of collection.
  • Salary carried with a source flag saying whether the figure came from the employer or from ZipRecruiter's own compensation estimate, which the platform adds to postings that quote no pay.
  • Description and requirements kept as published, not summarised.
  • Apply destination recorded as a type: the platform's own apply route, or an external careers site.
  • Source URL, capture timestamp and a content hash so a later run can tell a real edit from a re-render.

The output stops there, and that limit is the point. We deliver posting and employer data. Recruiter email addresses and personal contact routes are excluded by default rather than on request, and we do not assemble person-level records about named recruiters or hiring managers. Candidate profiles and resumes sit behind a login on ZipRecruiter, and we do not collect them. The GDPR treats a named person's contact details as personal data, which is why exclusion is the default setting and not an option you have to ask for. If a description names an individual, we will redact that text before delivery on request.

What a ZipRecruiter scraper can extract per posting
Employer Pages, the Salary Directory and Anti-Bot Work

Employer Pages, the Salary Directory and Anti-Bot Work

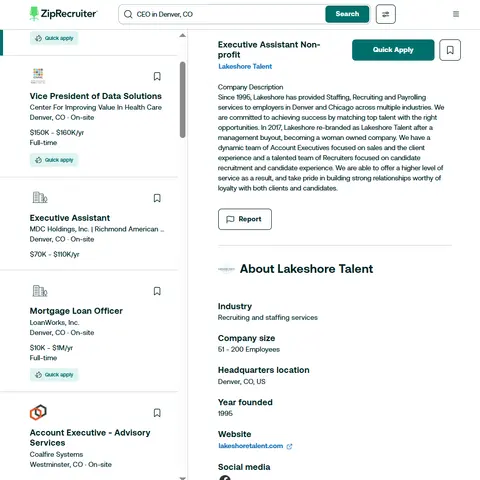
Beyond the posting, ZipRecruiter publishes an employer layer: an about page per company, that company's open jobs, a company salary page and a company reviews page. It also publishes a salary directory keyed by job title and geography. That directory is the platform's own computed figure and a separate dataset from any pay quoted inside a posting, so we keep the two in separate tables and nobody averages them by accident.

Each ZipRecruiter surface is a finite curated set, so a well-formed URL for a title or topic the site does not cover leads nowhere. Enumeration by generating slugs therefore does not work, and we resolve entities from real pages and search results before fetching anything.

Job and directory pages are guarded against automated clients, and getting through that layer is our work, not yours: request pacing, proxy rotation, CAPTCHA handling and page rendering are part of the service. We run at a modest rate and say plainly when a field stops resolving.

What ZipRecruiter Is, and What That Means for a Crawl

ZipRecruiter is a job marketplace for the United States market, launched in 2010. Its central product for employers is distribution rather than a single audience. An employer writes one posting, and ZipRecruiter forwards it onward; the company's own employer page states that a posted job is sent to over 100 job sites with one click.

That mechanic decides what the source is actually worth. A vacancy here is often the same vacancy a buyer will meet on another board under a different URL, so counting postings across sources will double count. The value sits on the employer side: which companies use ZipRecruiter as the origin of their distribution, what they publish there, how that footprint moves week to week, and the salary layer the platform builds on top of the postings.

Country routing is the operational trap. A request to the ziprecruiter.com apex from a European host is redirected to ziprecruiter.ie. The country properties are separate hosts with separate job indexes. The .com, .ca, .co.uk and .ie hostnames all answer, and each serves its own listings. A crawl launched from the wrong network collects another country's index and raises no error while it does it. We pin the exit country per project and record it alongside the data, so a US dataset is provably a US dataset.

Get a Quote
dev_w
25

Developers

customers
500+

Customers worldwide

pages
1 500 000 000+

Pages extracted

stime
15000+

Hours saved for our clients

Plans

ZipRecruiter Scraping Plans and Pricing

Airplane

€199 / one-time

setup fee - included

Data limits100,000
Frequencyone-time
Run timeup to 5 days
Data storing7 days

Helicopter

€169 / mo

setup fee €499

Data limits250,000
Frequencymonthly
Run timeup to 5 days
Data storing14 days

Glasses

€229 / mo

setup fee €499

Data limits1,000,000
Frequencyweekly
Run timeup to 5 days
Data storing30 days

DNA

€549 / mo

setup fee €799

Data limits3,000,000
Frequency3 times daily
Run timesame day
Data storing90 days

Delivery: CSV, JSON or XLSX files, our API or a JSON feed. MCP server on request.

Full plan details →

Why Scrape ZipRecruiter When the Postings Travel

The honest reason to scrape ZipRecruiter is not posting volume. Because the platform pushes one posting out across a large partner network, the raw listings largely restate what a buyer already holds from elsewhere. The signals that belong to this platform are the ones worth paying for.

Compensation teams use it to separate two numbers that look identical in a spreadsheet: pay the employer chose to publish, and pay the platform estimated for a posting that stated none. Averaging them together produces a pay curve that describes a model rather than a market, so we carry the distinction as a column, not a footnote.

Recruitment marketing and HR-tech teams work the employer surface instead. Company pages, company job lists, company salary pages and employer review pages are public, so a buyer can watch which employers are actively distributing, under which titles, at which advertised pay.

Teams selling into staffing and HR read posting activity as a demand signal at company level. It stays at company level in what we ship, and no ZipRecruiter data we deliver identifies an individual.

Our Blog

Reads Our Latest News & Blog

Learn how to use web scraping to solve data problems for your organization

How Artificial Intelligence Is Used In Web Scraping

How Artificial Intelligence Is Used In Web Scraping

Leveraging advances in technology, the AI-powered web scraper has skyrocketed in demand and is helping to expand capabilities by automating tedious daily tasks and speeding up data collection from thousands of websites several times over.

What is Web Scraping and What is it Used For?

What is Web Scraping and What is it Used For?

Web scraping is a method of obtaining web data by extracting it from pages of web resources with the help of a program, that is, in automatic mode. It is used to syntactically convert web pages into more usable forms.

Web Scraping for Machine Learning

Web Scraping for Machine Learning

If you specialize in machine learning, you need to feed large amounts of data to the algorithms. Web scraping is the easiest and the most efficient method of collecting the data from all over the Internet.

scrapeit logo

About ScrapeIt

ScrapeIt is a managed data extraction team. We build, run and maintain the crawlers, then hand over clean files or an API on a schedule you control. Job boards and HR portals have been a long-running part of our work for over five years, so we usually spot a layout change before it becomes a hole in your dataset. We reply to a brief within one business day, and support continues after the first delivery lands.

FAQ

Do you offer a ZipRecruiter API for job and salary data?

Yes. The ScrapeIt ZipRecruiter API returns job title, company name, location, employment type, posted date and salary with its source flag as JSON from an endpoint we host, refreshed on the schedule you set. Recruiter contacts stay out by default. The same data also comes as CSV or XLSX files or straight into your database.

Can you scrape ZipRecruiter recruiter emails or candidate resumes?

No. Recruiter email addresses and personal contact routes are excluded by default rather than on request, and we do not build person-level records. Candidate profiles and resumes sit behind a login and we do not collect them. What you receive is posting and employer data: title, company, location, employment type, dates, description, salary with its source flag, and the apply destination as a type rather than a personal address.

Is the salary on a ZipRecruiter job the real one the employer offered?

Sometimes. ZipRecruiter shows employer-stated pay when the posting carries it, and adds its own compensation estimate when the posting states none. The two look the same in a spreadsheet and mean completely different things. Every salary row we deliver carries a flag naming which of the two it is, and the platform's separate salary directory is delivered as its own table so it never gets averaged into advertised pay.

How do I make sure I get US jobs and not another country's site?

By controlling where the crawl runs from. A request to the ziprecruiter.com apex from a European host is redirected to ziprecruiter.ie. The country hostnames are separate properties with separate job indexes, so a job started from the wrong network quietly collects the wrong index. We pin the exit country for the project and stamp it on every record, so the country of a dataset is checkable rather than assumed.

How fast is delivery and which formats do you ship?

A sample extract for review typically lands within about 24 hours of an agreed brief, and a first full backfill usually takes three to five working days depending on scope. After that the job runs on your schedule. Formats are CSV, JSON, XLSX or SQL, delivered to S3 or an endpoint you name. We reply to a new brief within one business day.

How does it Work?

Step 1 - Make a Request

You share your needs, expectations, and desired timeframe. We’ll suggest the best solution based on your request and budget.

Step 2 - Configuring Custom Web Crawlers

Our specialists configure the crawlers and extract a sample dataset for your review before proceeding with the full-scale extraction.

Step 3 - Collect and Deliver

Once you approve the sample, we launch the project and start full data collection. We gather, filter, and structure the data for easy use, delivering it on time in your preferred format.

Step 4 - Maintain and Support

Our team manages ongoing processes, monitors website changes, and supports all data extraction cycles. We can also help integrate data into your systems or create dashboards to simplify analysis.

Request a Quote

Tell us more about you and your project information.
Which sites, which fields, how often. A couple of lines is enough.

We reply within 1 business day. No obligation.

ZipRecruiter data from €169/month. Free project assessment, reply within 1 business day.

scrapiet

Scrapeit Sp. z o.o.
10/208 Legionowa str., 15-099, Bialystok, Poland
NIP: 5423457175
REGON: 523384582