Beauty Price Monitoring on Notino and Douglas in 15+ Countries, in English
A cosmetics company got monthly prices and promotions from 40+ beauty stores in 15+ countries, translated to English and fed into its existing import.
Learn More
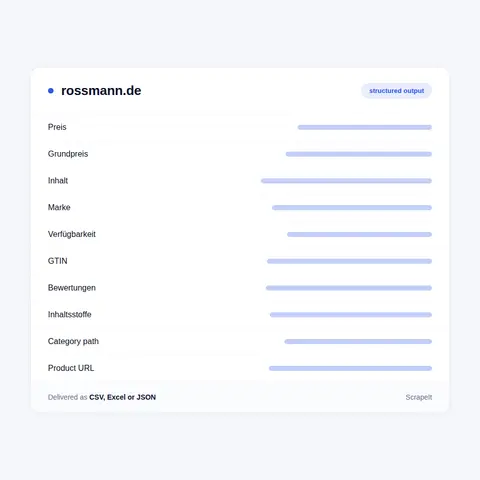
Rossmann lists the same product in several pack sizes. Without the Grundpreis those prices are not comparable, so we capture it as its own field on every row.
Plans from €169/month · Free project assessment · Reply within 1 business day
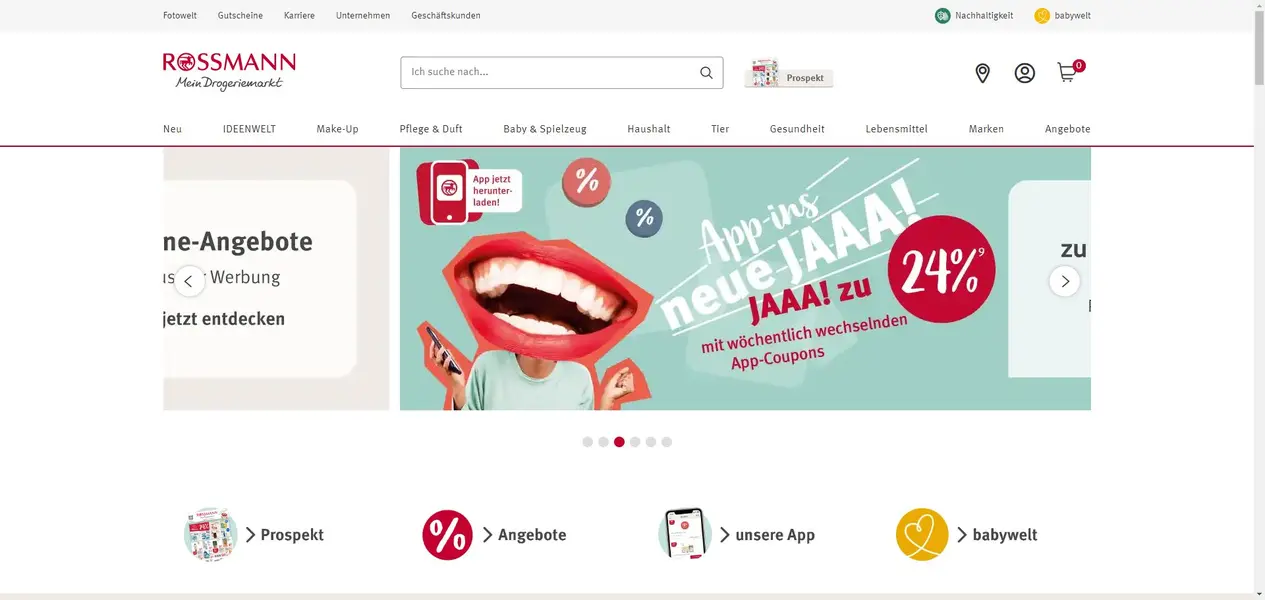
Scope is a list of categories or a list of GTINs, a schedule, and a delivery target. We walk the /c/ category tree and the published sitemaps, page through every listing, and resolve every item back to its /p/ GTIN so that affiliate and tracking parameters never create duplicate rows. Output is CSV, JSON, XLSX or an API endpoint, on the cadence you set: daily for pricing and availability, weekly or monthly for assortment. Markup changes are our problem rather than yours. When the storefront moves, we repair the extractor and the columns stay where they were, so the file you open on Monday has the same shape as last Monday's.
Every row starts with the identifier. A product URL on rossmann.de is a long descriptive slug followed by /p/ and a thirteen-digit code, and that code is a GTIN. Archived URLs show babydream articles under codes beginning 4305615 and ISANA articles under codes beginning 4068134, which is how own-brand items cluster on the company's own GS1 prefix. The code in the path is the stable join key. The slug in front of it is not, because it carries the category name and moves when merchandising moves.
A standard Rossmann data extract carries:
Collection covers public product and pricing data only. No customer data is touched.
Own brands are the second reason this is not a routine retail scrape. The company site at unternehmen.rossmann.de, stated a portfolio of 27 Marken (brands) and over 6.000 Produkte (products), and named ISANA, Alterra, domol, babydream, facelle, sunozon, enerBiO and altapharma among them. Those articles are sold nowhere else, and their GTINs are issued under Rossmann's own prefix, so no shared product code exists to join on. A matching pipeline keyed on EAN will line up the Garnier and Pantene rows and drop every own-brand row on the floor - which is precisely the part of the catalogue a competitor most wants to read.
Own-brand rows have to be matched on attributes instead: Marke, the normalised Inhalt, the product form, the category path, and the Grundpreis unit basis. That yields like against like, a 300 ml own-brand item set against a 300 ml branded one at the same base unit, rather than a code join that fails silently. We build the normalisation into the extract, so the columns arrive ready to match instead of arriving as free text. The shop also publishes a brand index at /de/Marken/c/brands, which gives the crawl a clean entry point for separating own brands from third-party brands.
Rossmann is a drugstore and not a pharmacy, and one of the listed own brands is named altapharma. We record the fields a page prints and nothing else. We do not describe, classify or infer what any article is for.
Rossmann is a German Drogeriemarkt, a drugstore chain, running a large store estate in Germany and further European markets alongside an online shop at rossmann.de. The shop carries cosmetics, hair and body care, household and cleaning goods, baby articles, food and drink, and seasonal lines that arrive and disappear on a calendar.
The storefront is a JavaScript application. Rossmann answers automated clients with a JavaScript challenge page instead of product markup. Any Rossmann scraper has to render pages the way a browser does and run at a pace the site can absorb.
Category listings sit under /c/, with codes such as olcat1_1 for Make-up and olcat1_4 for Lebensmittel, and every product resolves to a /p/ address that closes on its GTIN. Two sitemaps are published: a shop sitemap index, and a separate sitemap for the store directory under /de/filialen/. Store pages form their own crawlable tree, separate from the shop catalogue. Whether per-store stock is exposed to an anonymous client is something we confirm in scoping rather than assume.
Get a Quote
Developers

Customers worldwide

Pages extracted

Hours saved for our clients
€199 / one-time
setup fee - included
€169 / mo
setup fee €499
€229 / mo
setup fee €499
€349 / mo
setup fee €499
€549 / mo
setup fee €799
Delivery: CSV, JSON or XLSX files, our API or a JSON feed. MCP server on request.
Full plan details →The commercial reason to scrape Rossmann is comparability. Drugstore goods sell in many pack sizes, and the shelf figure on its own settles very little: a 200 ml bottle at one price and a 400 ml bottle at another are not two points on the same axis. The Grundpreis is the axis. German price indication rules require a base price per unit next to the selling price, so Rossmann publishes, for free, the single number that puts a 200 ml pack and a 400 ml pack on comparable footing - and every other German retailer publishes it for the same reason. A Rossmann price feed that carries Preis but not Grundpreis cannot answer the question buyers are actually asking.
Around that sits the ordinary work. Teams track Rossmann prices over time on a fixed basket, watch which lines move onto the campaign pages, measure assortment overlap against dm, Müller and the grocery chains, and feed a repricing or category review with numbers rather than screenshots. Brand owners use it the other way round, to see how their own articles are listed, priced and stocked, and what the own-brand item sitting beside them on the same category page costs per 100 ml.
A cosmetics company got monthly prices and promotions from 40+ beauty stores in 15+ countries, translated to English and fed into its existing import.
Learn More
A consultancy working for a fragrance brand owner got sellers, official-store flags and USD prices for 25 fragrances on about 30 marketplaces in 12 countries.
Learn More
Three Amazon US lighting categories collected in full for a lighting manufacturer, with description text and images from brand content blocks.
Learn MoreLearn how to use web scraping to solve data problems for your organization
Ten German ecommerce websites worth scraping in 2026, from OTTO and idealo to REWE and Edeka: what each site shows, which fields matter to a data buyer, what is specific to German retail data and how to combine the sites into one dataset.
If you sell online, run a marketplace, or advise e-commerce clients, you already know why eBay matters: it’s one of the few places where big retailers compete side by side with thousands of small merchants and private sellers.
E-commerce teams do not just need “some” competitor data anymore. They need a continuous stream of real prices, discounts, stock levels, reviews, and seller behavior from the platforms that actually shape their markets.
ScrapeIt is a managed web scraping agency. We are not a library and not a self-serve tool: we build the crawler, run it on your schedule, monitor it and repair it when a site changes. You receive data, not code to maintain. Work is scoped per project and a sample is delivered before sign-off, so you can check the Grundpreis parsing and the own-brand flags against the live pages yourself. We have no affiliation with Rossmann.
Yes. The ScrapeIt Rossmann API returns GTIN, Preis, Grundpreis, Inhalt, Marke and Verfügbarkeit as JSON from an endpoint we host, refreshed on the schedule you set. The same Rossmann data also comes as CSV or XLSX files or straight into your database.
Yes, and we treat it as a primary field rather than a nice-to-have. Grundpreis arrives as three columns - value, reference amount and unit - so a row on a per 100 ml basis and a row on a per litre basis can be compared without re-parsing strings downstream. Inhalt (pack size) is normalised to number and unit alongside it, which lets you check the Grundpreis against the pack and flag pages where the two disagree.
Own-brand articles carry GTINs issued under Rossmann's own prefix, so they have no matching code at any other retailer. We flag each row as own brand or third-party brand, and we normalise the attributes a code join cannot replace: Marke, Inhalt as number and unit, category path, and the Grundpreis unit basis. Your matching pipeline then has something to work with instead of a null EAN join.
A challenge document. The site answers automated clients with HTML titled Client Challenge that requires JavaScript and loads its assets from a /_fs-ch- path. So a plain text match will not produce Rossmann price data. We render pages the way a browser does and keep request rates modest. We collect only publicly available data - everything a visitor can see on Rossmann - and we collect it legally.
Daily is the usual cadence for price and availability, and it fits how the shop behaves: campaign surfaces such as the Angebote, Rabatt and Ausverkauf paths rotate, online-exclusive lines sit on their own campaign path, and seasonal ranges come and go - archived URLs show separate Adventskalender articles for the 2024 and the 2025 season. Assortment runs that walk the whole category tree usually sit on a weekly or monthly schedule. We set the frequency per category rather than running everything at one rate.
Step 1 - Make a Request
You share your needs, expectations, and desired timeframe. We’ll suggest the best solution based on your request and budget.
Step 2 - Configuring Custom Web Crawlers
Our specialists configure the crawlers and extract a sample dataset for your review before proceeding with the full-scale extraction.
Step 3 - Collect and Deliver
Once you approve the sample, we launch the project and start full data collection. We gather, filter, and structure the data for easy use, delivering it on time in your preferred format.
Step 4 - Maintain and Support
Our team manages ongoing processes, monitors website changes, and supports all data extraction cycles. We can also help integrate data into your systems or create dashboards to simplify analysis.
Rossmann data from €169/month. Free project assessment, reply within 1 business day.

Scrapeit Sp. z o.o.
10/208 Legionowa str., 15-099, Bialystok, Poland
NIP: 5423457175
REGON: 523384582


