Workable Scraper for Employer Career Pages

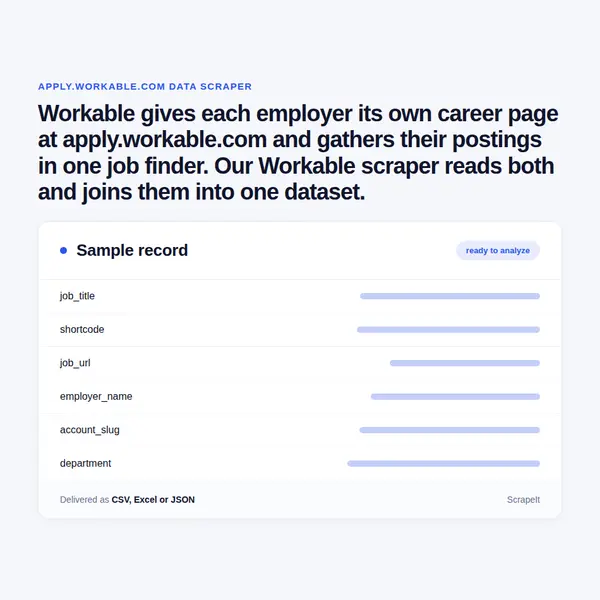
Workable gives each employer its own career page at apply.workable.com and gathers their postings in one job finder. Our Workable scraper reads both and joins them into one dataset.

Plans from €169 a month · Free project assessment · Reply within 1 business day

CSV · Excel · JSON · XML · FTP · SFTP · Amazon S3 · Google Cloud

apply.workable.com
Workable Scraper for Employer Career Pages
apply.workable.comwhat you get
Typical fields for job boards
job_titlecompanylocationsalaryemployment_typeposted_at
Delivery

API, JSON feed or CSV, XLSX and JSON files

Schedule

One-time, monthly, weekly, daily or 3 times a day

Scrape Workable Career Pages as a Managed Service

  1. You send

    Workable pages, filters, fields and a schedule

  2. We run the scrapers

    Built, monitored and repaired by our team

  3. You receive the data

    API, JSON feed or CSV, XLSX and JSON files

You send us the employers you care about - account slugs from apply.workable.com, company names, or a search on jobs.workable.com such as a job title in a set of countries - and we do the rest. We build the crawler, render the script-driven career pages, handle pacing and proxy rotation, and repair the parser when the page layout changes. Each run lists every open role per employer, opens each posting and maps it onto one schema, so a hundred career pages arrive as one table rather than a hundred formats. Runs are one-off or on the schedule you set, and field documentation comes with the first delivery.

Workable Job Listings: Fields We Extract

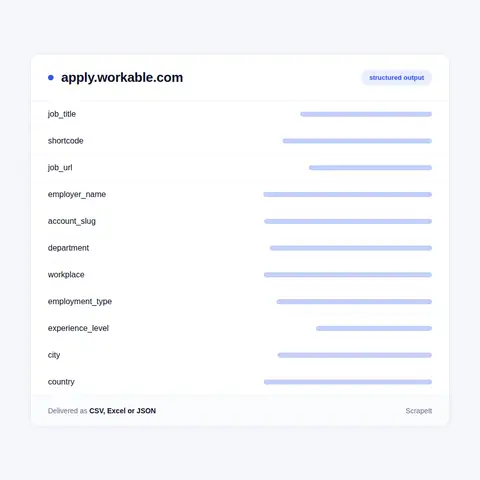
A Workable posting opens with a short header - company, location, employment type and posted date - then lists salary, workplace and department, and splits the job text into Description, Requirements and Benefits. We read all of it and return one row per posting per location:

  • Posting identityjob title, the shortcode Workable assigns to each job (a ten-character code in the URL, as in apply.workable.com/blueground/j/DF694D45CA/), posting URL and the employer's account slug.
  • Employercompany name as the career page writes it, the account slug, and the matching company page on jobs.workable.com.
  • Location and workplacecity, region and country, plus the workplace label On-site, Hybrid or Remote.
  • Classificationdepartment exactly as the employer names it (Operations, Client Experience or On Demand on one career page), employment type (Full-time, Part-time, Contract, Temporary, Other), and experience level from Internship to Executive, taken from the Experience filter of the job finder.
  • Paysalary range with currency and period when the employer publishes one, for example a yearly band on a UK marketing role.
  • Job textthe Description, Requirements and Benefits sections as separate fields, in plain text or with their HTML kept.
  • Timingposted date, taken as a calendar date from the career page or converted from job finder labels such as "Posted today", plus the first-seen and last-seen dates of our runs.

Because department names and job titles are free text set by each employer, we keep the original value and add a normalised column next to it, so a department called On Demand, which means little outside one company, can still be grouped with sales or operations roles elsewhere.

Workable Job Listings: Fields We Extract
Workable Data Beyond a Single Career Page

Workable Data Beyond a Single Career Page

One career page answers what one employer is hiring for. The value of Workable data comes from reading many of them the same way, and from reading them again.

  • The job finder at jobs.workable.comIt searches postings of many employers at once and filters by Date posted (Last 24 hours, Last week, Last month, Any time), On-site/Hybrid/Remote, Employment type and Experience. We use it to discover employers you did not know were hiring for a role, and we flag the postings it marks Featured.
  • Company pagesEach employer also has a page on the job finder listing its open roles; we use it to confirm the full list and the count.
  • Career page job listsEach career page lists its open roles with department, location, type, salary where published and posted date - the same cuts we deliver as columns.
  • Multi-location postingsOne opening offered in several cities - a remote field marketing role listed for St. Louis, Chicago, Austin and Dallas - shows as separate cards. We keep a row per location and a group key, so totals are not inflated.
  • Opening and closing over timeSome roles stay up for a year or more, others close quickly. Repeated runs record when a posting appeared, when its salary or text changed and when it was taken down - the time-to-fill signal a single snapshot cannot give.

About Workable and apply.workable.com

Source
apply.workable.com
Category
job boards
Delivery
API, JSON feed, CSV, XLSX
Plans
From €169 a month
Get a quote

Workable is recruiting and HR software sold to employers; the footer of its job finder names Workable Technology Limited. It is an applicant tracking system, not a job board in the usual sense: an employer writes a job in its Workable account and the posting goes live on that employer's career page, where candidates read it and apply.

By default a career page sits at apply.workable.com followed by the employer's slug - apply.workable.com/blueground, apply.workable.com/huggingface - and a posting sits under /j/ plus its shortcode. At additional cost an employer can serve the same page from its own domain, such as careers.yourcompany.com, so a Workable posting is not always on a Workable address. The page itself is a single template: the company's own description, its open roles with department, location and type, and a "Powered by Workable" line at the bottom.

On top of the career pages Workable runs jobs.workable.com, a public job finder that searches postings across its employers. Candidate profiles, applications and hiring pipelines live inside each employer's account and are never part of what we collect; the product is the posting and the employer.

25Developers
500+Customers
1.5BPages extracted
15,000+Hours saved for our clients

Workable scraping plans and pricing

Airplane

€199one-time

Setup fee included

100,000
One-time
Up to 5 days
7 days

Helicopter

€169/ mo

Setup fee €499

250,000
Monthly
Up to 5 days
14 days

Glasses

€229/ mo

Setup fee €499

1,000,000
Weekly
Up to 5 days
30 days

Microscope popular

€349/ mo

Setup fee €499

2,000,000
Daily
Same day
60 days

DNA

€549/ mo

Setup fee €799

3,000,000
3 times daily
Same day
90 days

Delivery: CSV, JSON or XLSX files, our API or a JSON feed. MCP server on request.

Full plan details

Why Teams Build a Workable Database of Openings

Every Workable posting has a home on its employer's career page, written in the employer's own words, with its own department names and a posted date - read together, those pages show what a chosen set of companies is hiring for.

  • Sales and account signalsA new department appearing on a career page, or a run of Hybrid roles in a new city, says a company is expanding there. Sales teams selling to growing companies watch exactly that.
  • Competitor hiringDepartment and title columns show where a competitor is investing - engineering versus revenue roles, junior versus Director level.
  • Pay benchmarkingWhere employers publish a salary range, the range, currency and period sit next to the title and city, which is enough for a benchmark by role and market.
  • Workplace mixOn-site, Hybrid and Remote labels per posting track how employers in a sector actually staff new roles.
  • Job boards and aggregatorsNiche boards fill their listings from employer career pages; a Workable database refreshed daily keeps those listings current and removes closed roles.

About ScrapeIt

ScrapeIt is a managed web scraping company: we build, run and maintain crawlers and deliver the datasets. For applicant tracking systems such as Workable the work is mostly breadth - many small career pages, each with its own department names and locations - and keeping them on one schema. We start with a free project assessment, and you can order a sample before the first scheduled run. Plans start from EUR 169 a month, or EUR 199 for a one-time extract.

FAQ

Still unsure? Write to info@scrapeit.io

Do you offer a Workable API for job postings?

Yes. The ScrapeIt Workable API returns job title, shortcode, employer, department, workplace, location and salary range as JSON from an endpoint we host, refreshed on the schedule you set. The same postings also arrive as CSV or XLSX files, a JSON feed, or a load into your own database.

Is it legal to scrape Workable?

Yes. Career pages and the job finder are open to any visitor, because employers publish them to reach candidates. We collect only publicly available data - everything a visitor can see on Workable - and we collect it legally. Recruiter names that appear inside job texts are personal data under GDPR and are removed by default.

Can you cover every employer that hires through Workable?

We cover the employers you name and can widen the list through the job finder, searching by title, country and date posted to find employers with matching openings. Career pages served from an employer's own domain are included when you give us the address. Employers with no open roles show an empty list, which we record as zero rather than skip.

How often are Workable jobs updated, and how often should you refresh?

Employers add, edit and close roles whenever they like, and on a busy search the job finder shows many cards marked "Posted today". For a job board feed we run daily; for hiring signals and pay research a weekly run is usually enough. Every run keeps first-seen and last-seen dates, so closed postings are marked rather than silently dropped.

Can you export Workable job listings with salary ranges and full job text?

Yes. Each row carries the salary range when the employer publishes one, with minimum, maximum, currency and period in separate columns, and the Description, Requirements and Benefits sections in their own fields. Exports come as CSV, Excel or JSON, or straight to Amazon S3 or Google Drive.

How it works

  1. 1

    Make a request

    You share your needs, expectations, and desired timeframe. We'll suggest the best solution based on your request and budget.

  2. 2

    We configure the crawlers

    Our specialists configure the crawlers and extract a sample dataset for your review before proceeding with the full-scale extraction.

  3. 3

    Collect and deliver

    Once you approve the sample, we launch the project and start full data collection. We gather, filter, and structure the data for easy use, delivering it on time in your preferred format.

  4. 4

    Maintain and support

    Our team manages ongoing processes, monitors website changes, and supports all data extraction cycles. We can also help integrate data into your systems or create dashboards to simplify analysis.

Request a quote

Tell us which sites, which fields and how often. A couple of lines is enough to start.

  • We reply within 1 business day
  • A sample dataset before the full run
  • We sign an NDA on request
  • Delivery by API, JSON feed or files
Which sites, which fields, how often. A couple of lines is enough.

This form is protected by Google reCAPTCHA, which loads when you start filling it in; the Google Privacy Policy and Terms of Service apply. If you prefer not to use it, email us at info@scrapeit.io. Privacy & Cookie Policy

We reply within 1 business day. No obligation.

Workable data from €169/month. Free project assessment, reply within 1 business day.