ANSA Data Collection for Italian Wire Coverage

Most Italian news starts as agency copy. Measure where ANSA's wire travels and you are measuring the Italian news agenda at its source.

Plans from €169/month · Free project assessment · Reply within 1 business day

ANSA Scraper
Solutions

Managed Italian news data, run end to end by us

ScrapeIt runs the collection as a managed service. You name the sections, regions or editions; we collect headlines and metadata with edition and regional desk as fields, link pickups across Italian outlets, and hand back CSV, JSON, Excel or a push into your warehouse.

News moves quickly, so collection runs frequently enough that the first appearance of a story is recorded, which is what makes timing analysis possible.

We collect only publicly available data - everything a visitor can see on ANSA - and we collect it legally.

ANSA fields in every export

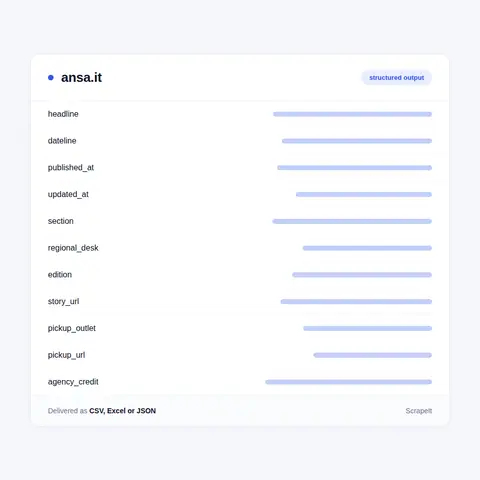
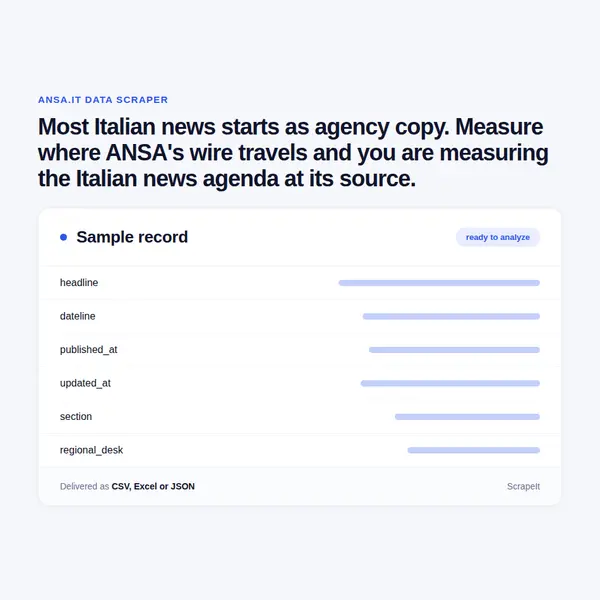
Story records carry the headline, dateline, publication and update timestamps, section, region where the desk is regional, edition - Italian or English - and the address.

Edition is a first class field. The English service is a selection, written for foreign readers, and comparing what appears in English against the full Italian output is a measurable question about how Italy is presented abroad.

Regional desk is kept rather than folded into national sections, because a large share of agency output is regional and a national-only view misses where much of the country's news actually originates.

Pickup records are a separate table: where ANSA copy appears in other Italian outlets, identified by the agency credit, collected from those outlets' public pages.

Every row carries the collection timestamp and the source type, so agency output and pickup observations are never mixed.

ANSA fields in every export
Pickup tracking, regional desks and limits

Pickup tracking, regional desks and limits

Pickup tracking is the distinctive output: which ANSA stories were taken up by which outlets, with what delay, and how far the headline travelled from the original wording. It runs on the public pages of Italian outlets and needs nothing beyond the agency credit to link copies.

Regional desk analysis maps where agency attention goes across Italy's regions and how that shifts over time, which is useful to regional authorities and to anyone tracking local risk.

Edition comparison between Italian and English output measures the international selection directly.

Limits: no collection behind any login.

Italy's national news agency, in two languages

ANSA is Italy's leading news agency. Like any wire service, most of its reach is indirect: newspapers, broadcasters and websites across the country take its copy and build on it, so an ANSA story frequently becomes many Italian stories within hours.

Its own site publishes the agency's news by section and region, and it runs an English-language service for international readers. That gives a data project two related but distinct streams: what the agency tells Italy, and what it chooses to tell the world in English.

Section and English-edition pages respond directly with substantial content. Each story carries a headline, dateline, publication and update timestamps, section and, where the desk is regional, its region.

For anyone studying the Italian media, the agency is the upstream point where most coverage can be measured first.

Get a Quote
dev_w
25

Developers

customers
500+

Customers worldwide

pages
1 500 000 000+

Pages extracted

stime
15000+

Hours saved for our clients

Plans

ANSA Scraping Plans and Pricing

Airplane

€199 / one-time

setup fee - included

Data limits100,000
Frequencyone-time
Run timeup to 5 days
Data storing7 days

Helicopter

€169 / mo

setup fee €499

Data limits250,000
Frequencymonthly
Run timeup to 5 days
Data storing14 days

Glasses

€229 / mo

setup fee €499

Data limits1,000,000
Frequencyweekly
Run timeup to 5 days
Data storing30 days

DNA

€549 / mo

setup fee €799

Data limits3,000,000
Frequency3 times daily
Run timesame day
Data storing90 days

Delivery: CSV, JSON or XLSX files, our API or a JSON feed. MCP server on request.

Full plan details →

Why the agency is the right place to measure first

Media monitoring in Italy usually starts with the big newspapers. That measures the end of the chain. A great deal of what those papers publish began as agency copy, and measuring at the agency shows the agenda before it is multiplied and reshaped.

The first product is timing. When a story first appeared on the wire, and how long it took to reach national and regional outlets, is a direct measure of how news moves through the Italian system - and of which outlets add original reporting on top.

The second is regional coverage. Agency regional desks cover places national newspapers reach only occasionally, so the regional stream is often the best structured source for local events across Italy.

The third is the English service, a curated view of Italy for international readers. What gets translated, and how quickly, says something about which Italian stories the agency expects the world to care about.

Our Blog

Reads Our Latest News & Blog

Learn how to use web scraping to solve data problems for your organization

How Artificial Intelligence Is Used In Web Scraping

How Artificial Intelligence Is Used In Web Scraping

Leveraging advances in technology, the AI-powered web scraper has skyrocketed in demand and is helping to expand capabilities by automating tedious daily tasks and speeding up data collection from thousands of websites several times over.

What is Web Scraping and What is it Used For?

What is Web Scraping and What is it Used For?

Web scraping is a method of obtaining web data by extracting it from pages of web resources with the help of a program, that is, in automatic mode. It is used to syntactically convert web pages into more usable forms.

Web Scraping for Machine Learning

Web Scraping for Machine Learning

If you specialize in machine learning, you need to feed large amounts of data to the algorithms. Web scraping is the easiest and the most efficient method of collecting the data from all over the Internet.

scrapeit logo

Who builds and keeps your agency feed

ScrapeIt is a managed extraction company, not a tool you have to learn. Our team follows sections and regional desks as the site changes, keeps editions apart, and repairs collection before a news cycle goes unrecorded.

You see a sample first, in your format, over the sections and regions you actually follow, with pickups linked so you can see how far a story travelled.

FAQ

Is it legal to scrape ANSA?

Yes. Headlines, datelines, sections, regional desks and both editions are publicly available data - everything a visitor can see on ANSA - and we collect them legally. There is no collection behind any login.

Why start with the agency rather than newspapers?

Because much Italian coverage begins as agency copy. Measuring at the agency shows the agenda before it is multiplied and reshaped, and makes it possible to see which outlets add original reporting on top.

What does the English service add?

A curated view of Italy for international readers. Comparing it with the Italian output shows which stories the agency expects the world to care about, and how quickly they are translated.

Can you cover regional news?

Yes - regional desk is a field. A large share of agency output is regional, and it is often the best structured source for local events that national newspapers reach only occasionally.

Do you offer an ANSA API for headlines and metadata?

Yes. The ScrapeIt ANSA API returns headline, dateline, publication and update timestamps, section, regional desk and edition as JSON from an endpoint we host, refreshed on the schedule you set. The same data also comes as CSV or XLSX files or straight into your database.

How does it Work?

Step 1 - Make a Request

You share your needs, expectations, and desired timeframe. We’ll suggest the best solution based on your request and budget.

Step 2 - Configuring Custom Web Crawlers

Our specialists configure the crawlers and extract a sample dataset for your review before proceeding with the full-scale extraction.

Step 3 - Collect and Deliver

Once you approve the sample, we launch the project and start full data collection. We gather, filter, and structure the data for easy use, delivering it on time in your preferred format.

Step 4 - Maintain and Support

Our team manages ongoing processes, monitors website changes, and supports all data extraction cycles. We can also help integrate data into your systems or create dashboards to simplify analysis.

Request a Quote

Tell us more about you and your project information.
Which sites, which fields, how often. A couple of lines is enough.

We reply within 1 business day. No obligation.

ANSA data from €169/month. Free project assessment, reply within 1 business day.

scrapiet

Scrapeit Sp. z o.o.
10/208 Legionowa str., 15-099, Bialystok, Poland
NIP: 5423457175
REGON: 523384582