La Vanguardia Data Across Spanish and Catalan Editions

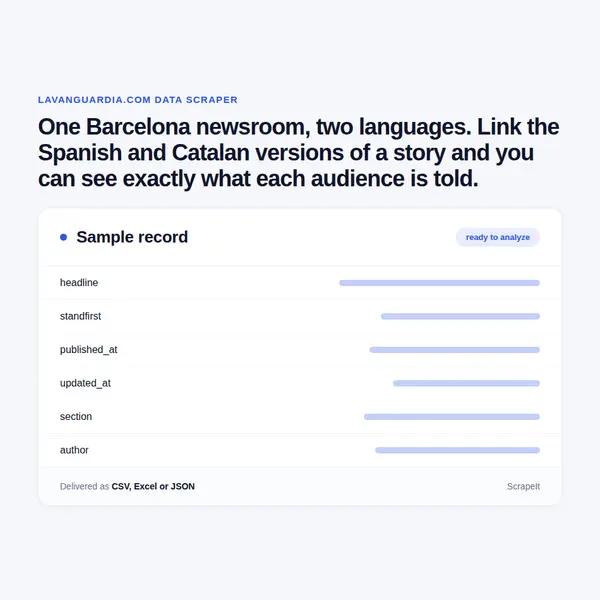
One Barcelona newsroom, two languages. Link the Spanish and Catalan versions of a story and you can see exactly what each audience is told.

La Vanguardia Scraper
Solutions

Managed Spanish and Catalan news data, run end to end by us

ScrapeIt runs the collection as a managed service. You name the sections and editions; we collect headlines and metadata with edition and geographic focus as fields, link the two language versions of each story, and hand back CSV, JSON, Excel or a push into your warehouse.

We collect frequently and keep revisions, because the lag between editions is only measurable if first appearances are recorded.

We honour the crawl rules and the AI training exclusion. The journalism is copyrighted: the dataset is for measurement rather than republication. Your counsel should see the use case before the project starts.

La Vanguardia fields in every export

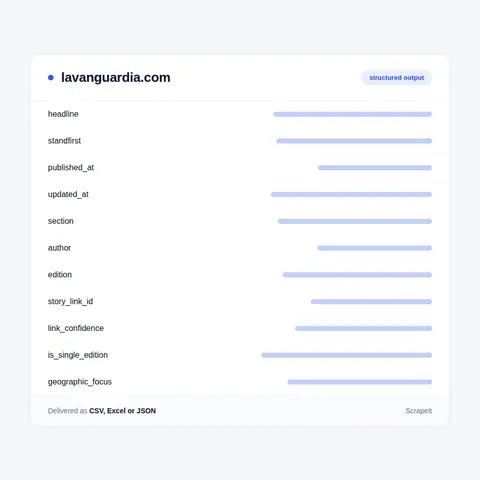
Article records carry the headline, standfirst, publication and update timestamps, section, author where bylined, edition - Spanish or Catalan - and the address.

A story link connects the Spanish and Catalan versions of the same piece where both exist. Built from the site's own structure and matching rather than guesswork, it records confidence alongside each link, and a story that appears in only one edition is recorded as such.

Geographic focus is kept as a field - Catalonia, Spain, international - because the paper's regional and national coverage serve different questions, and a combined count hides both.

Every row carries the collection timestamp and, where re-collection shows the article changed, a revision count.

La Vanguardia fields in every export
Edition parity, regional focus and limits

Edition parity, regional focus and limits

Edition parity analysis is the distinctive output: the share of stories published in both languages, by section and over time, with timing and headline differences recorded.

Regional focus tracking shows how coverage divides between Catalonia, Spain and the wider world, and how that balance shifts around events.

Framing comparison across editions needs care: headlines differ for idiom and length as well as editorial choice, so we deliver the linked pairs and leave interpretation to human reading rather than a similarity score.

Limits: headlines and metadata for analysis, not republication of the paper's journalism. Nothing behind a login or subscription, and no use of the material as AI training data, in line with the exclusion in the crawl rules.

A Barcelona daily published in two languages

La Vanguardia is one of Spain's leading newspapers, based in Barcelona, covering Catalonia, Spain and the world. It publishes in Spanish and has a Catalan edition, so the same newsroom addresses two language audiences.

That bilingual structure is what makes it interesting as data. A story published in both languages can be compared directly: whether it appears in both, how quickly, and whether the framing differs. Because a single newsroom produces both, differences reflect editorial and translation decisions rather than the differences between separate organisations.

Section pages and the Catalan edition respond directly with substantial content. The crawl rules are long and specific for general crawlers without closing the site, and the major AI training crawlers are named and excluded. We collect headlines and metadata for analysis, which is outside that exclusion, and never use the material for AI training.

For anyone studying Spanish and Catalan media, it is a rare source where the language comparison comes from one editorial team.

Get a Quote
dev_w
25

Developers

customers
500+

Customers worldwide

pages
1 500 000 000+

Pages extracted

stime
15000+

Hours saved for our clients

Plans

Airplane

€199 / one-time

setup fee - included

Data limits100,000
Frequencyone-time
Run timeup to 5 days
Data storing7 days

Helicopter

€169 / mo

setup fee €499

Data limits250,000
Frequencymonthly
Run timeup to 5 days
Data storing14 days

Glasses

€229 / mo

setup fee €499

Data limits1,000,000
Frequencyweekly
Run timeup to 5 days
Data storing30 days

DNA

€549 / mo

setup fee €799

Data limits3,000,000
Frequency3 times daily
Run timesame day
Data storing90 days

Why a bilingual newsroom is worth modelling carefully

Multilingual media analysis usually compares separate outlets in separate languages, which mixes language effects with every other difference between organisations. A single newsroom publishing in two languages removes most of that noise.

The first product is coverage parity: which stories appear in both editions, which only in one, and whether that pattern differs by section. That is a direct, measurable question about how a bilingual society is served by its press.

The second is timing. When a story appears in one language before the other, the lag is itself informative about editorial priority.

The third is regional focus. Catalonia-focused coverage and national coverage answer different questions, and keeping them apart makes both usable - particularly for anyone tracking Catalan public affairs.

And the AI training exclusion stated in the crawl rules is respected throughout: measurement and analysis, never training data.

Our Blog

Reads Our Latest News & Blog

Learn how to use web scraping to solve data problems for your organization

How Artificial Intelligence Is Used In Web Scraping

How Artificial Intelligence Is Used In Web Scraping

Leveraging advances in technology, the AI-powered web scraper has skyrocketed in demand and is helping to expand capabilities by automating tedious daily tasks and speeding up data collection from thousands of websites several times over.

What is Web Scraping and What is it Used For?

What is Web Scraping and What is it Used For?

Web scraping is a method of obtaining web data by extracting it from pages of web resources with the help of a program, that is, in automatic mode. It is used to syntactically convert web pages into more usable forms.

Web Scraping for Machine Learning

Web Scraping for Machine Learning

If you specialize in machine learning, you need to feed large amounts of data to the algorithms. Web scraping is the easiest and the most efficient method of collecting the data from all over the Internet.

scrapeit logo

Who builds and keeps your bilingual feed

ScrapeIt is a managed extraction company, not a tool you have to learn. Our team maintains the cross-edition linking as the site changes, keeps editions and regions apart, and repairs collection before an edition drops out of your data.

You see a sample first, in your format, over the sections you actually follow, with story pairs linked so you can judge the matching on real articles.

FAQ

Can you collect La Vanguardia for AI training?

No. The crawl rules name the AI training crawlers and exclude them. We collect headlines and metadata for analysis, which is outside that exclusion, and never use or pass on the material as training data.

Why link the Spanish and Catalan versions?

Because one newsroom produces both, so differences reflect editorial and translation choices rather than differences between organisations. Linked, the two editions show coverage parity and timing directly; unlinked, they are two unrelated piles of articles.

What if a story appears in only one edition?

It is recorded as single-edition rather than dropped. The stories that do not cross the language line are often the most informative part of the comparison.

Can you separate Catalan and national coverage?

Yes - geographic focus is a field. Catalonia-focused and national coverage answer different questions, and keeping them apart makes both usable, particularly for Catalan public affairs.

Can I republish the articles?

No. The journalism is copyrighted, and the dataset is headlines and metadata for measurement. Anything surfacing article text to your users needs a licence from the publisher.

How does it Work?

Step 1 - Make a Request

You share your needs, expectations, and desired timeframe. We’ll suggest the best solution based on your request and budget.

Step 2 - Configuring Custom Web Crawlers

Our specialists configure the crawlers and extract a sample dataset for your review before proceeding with the full-scale extraction.

Step 3 - Collect and Deliver

Once you approve the sample, we launch the project and start full data collection. We gather, filter, and structure the data for easy use, delivering it on time in your preferred format.

Step 4 - Maintain and Support

Our team manages ongoing processes, monitors website changes, and supports all data extraction cycles. We can also help integrate data into your systems or create dashboards to simplify analysis.

Request a Quote

Tell us more about you and your project information.
Which sites, which fields, how often. A couple of lines is enough.

We reply within 1 business day. No obligation.

scrapiet

Scrapeit Sp. z o.o.
10/208 Legionowa str., 15-099, Bialystok, Poland
NIP: 5423457175
REGON: 523384582