Bleacher Report Scraper for Articles and Coverage Volume

Counting articles about a team is easy. Knowing how many were reporting and how many were takes is the part that makes the number mean anything.

Plans from €169 a month · Free project assessment · Reply within 1 business day

CSV · Excel · JSON · XML · FTP · SFTP · Amazon S3 · Google Cloud

bleacherreport.com
Bleacher Report Scraper for Articles and Coverage Volume
bleacherreport.comwhat you get
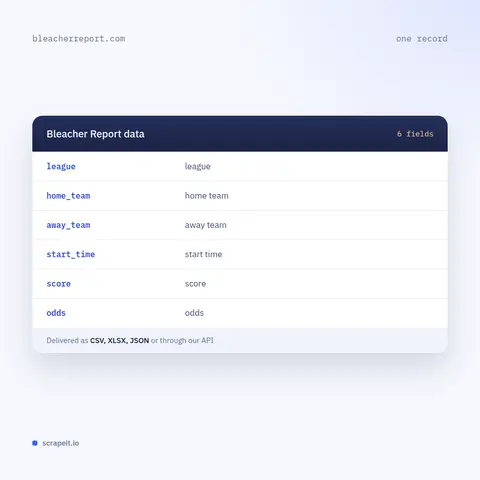
Typical fields for sports sites
leaguehome_teamaway_teamstart_timescoreodds
Delivery

API, JSON feed or CSV, XLSX and JSON files

Schedule

One-time, monthly, weekly, daily or 3 times a day

Managed sports media data, run end to end by us

  1. You send

    Bleacher Report pages, filters, fields and a schedule

  2. We run the scrapers

    Built, monitored and repaired by our team

  3. You receive the data

    API, JSON feed or CSV, XLSX and JSON files

ScrapeIt runs the collection as a managed service. You name the sports, teams or the full feed; we build the pipeline with article types classified and confidence attached, timestamps for publication and modification, and hand back CSV, JSON, Excel or a push into your warehouse.

Where coverage timing matters we collect frequently and keep revisions rather than overwriting, because an article that changed is a different article.

We collect published editorial metadata and pace requests. We collect only publicly available data - everything a visitor can see on Bleacher Report - and we collect it legally.

Bleacher Report fields in every export

Article records carry the headline, publication timestamp, author as bylined, sport, team section, article type, tags, word count and the address.

Article type is the field that makes the dataset useful rather than merely large. Classification uses structural signals - section, tags, headline pattern, presence of sourcing - and it ships with a confidence value, because it is an inference and the rows where it is uncertain are exactly the ones an analyst should look at.

Team and sport are separate fields. An article can concern a team, a league or a player, and collapsing those into one subject column makes coverage analysis ambiguous at the point where it matters.

Body text is collected where a client needs it for analysis, in the same row as the headline and the article type.

Every row carries the collection timestamp and, where available, the last modified time, since sports articles are frequently updated after publication.

Bleacher Report fields in every export
Sentiment caution, multi-outlet comparison and timelines

Sentiment caution, multi-outlet comparison and timelines

Sentiment analysis comes up on every media brief and deserves a caution rather than a sales pitch. Sports writing is full of hyperbole, irony and idiom that general purpose sentiment models read badly, and a negative score on a headline about a demolition or a thrashing usually means the model has misread a scoreline. We deliver the text and the structure and are candid that sentiment here needs domain-tuned work rather than a library call.

Multi-outlet comparison on a shared schema is the more defensible product: which publishers cover which teams, at what volume, in what mix of article types, and how that differs by market.

Timeline analysis around events - a transfer, an injury, a coaching change - shows how coverage builds and decays, and needs the publication and modification timestamps to be right.

Each of these runs on the same fields: headline, author, sport, team section, article type with its confidence value, tags, word count and the publication and modification timestamps.

High volume coverage organised by team

Source
bleacherreport.com
Category
sports sites
Delivery
API, JSON feed, CSV, XLSX
Plans
From €169 a month
Get a quote

Bleacher Report is a large American sports media site covering the major North American leagues plus football and combat sports, publishing at high volume across news, analysis and opinion.

Its structure suits data work well: content is organised by sport and by team, so a team section is a ready-made corpus of coverage about one subject. Those sections respond directly and carry a great deal of content.

What the data needs, and what a naive collection skips, is a distinction between kinds of article. This publisher mixes straight reporting, analysis, opinion and aggregation of other outlets' reporting, and a coverage volume metric that treats all four as equivalent measures something close to nothing.

Every article page shows the headline, byline, publication time, sport, team section and tags alongside the text, and each of those becomes a field in the dataset.

25Developers
500+Customers
1.5BPages extracted
15,000+Hours saved for our clients

Bleacher Report scraping plans and pricing

Airplane

€199one-time

Setup fee included

100,000
One-time
Up to 5 days
7 days

Helicopter

€169/ mo

Setup fee €499

250,000
Monthly
Up to 5 days
14 days

Glasses

€229/ mo

Setup fee €499

1,000,000
Weekly
Up to 5 days
30 days

Microscope popular

€349/ mo

Setup fee €499

2,000,000
Daily
Same day
60 days

DNA

€549/ mo

Setup fee €799

3,000,000
3 times daily
Same day
90 days

Delivery: CSV, JSON or XLSX files, our API or a JSON feed. MCP server on request.

Full plan details

Why coverage volume needs article types

Media monitoring in sport almost always starts as a counting exercise and almost always fails for the same reason: the count includes things that are not comparable.

A club that received forty mentions in a week has had a very different week depending on whether those were match reports, injury news or opinion pieces about its manager. Without article types the number moves and nobody can say why, which makes it useless for the thing it was bought for.

The second reason is the update problem. Sports articles change after publication - scores fill in, transfers are confirmed, headlines are rewritten. A dataset with only a publication timestamp silently mixes the article as published with the article as it now reads. Recording the modification time, and re-collecting where it matters, is what keeps a corpus honest.

The third is that high volume is a feature here rather than a nuisance. A publisher producing at this rate gives enough data for week-on-week movement to be meaningful rather than noise, which is rarely true of a smaller outlet.

The fourth is scope. One publisher is one voice. Share of coverage is a multi-source question, and we scope it as several publishers with a shared schema rather than presenting one outlet as the media landscape.

Who builds and keeps your media feed

ScrapeIt is a managed extraction company, not a tool you have to learn. Our team builds the pipeline, retunes the article classifier as section structures change, and repairs the collector before a coverage series develops a gap around the event you cared about.

You see a sample first, in your format, over the teams you actually track, with article types and confidence visible so you can judge the classification on real headlines rather than trust it.

FAQ

Still unsure? Write to info@scrapeit.io

Why classify articles by type?

Because a team with forty mentions had a very different week depending on whether those were match reports, injury news or opinion. Without types the count moves and nobody can say why, which makes it useless for the purpose it was bought for.

How reliable is the classification?

It is an inference and it ships with a confidence value on every row. The uncertain rows are exactly the ones worth a human look, which is why we surface the confidence rather than hiding it behind a clean-looking label.

Can you do sentiment analysis?

We can, with a caution we would rather give up front. Sports writing is full of hyperbole and idiom that general models misread - a headline about a thrashing scores negative when it describes a win. It needs domain-tuned work, not a library call, and we will say so rather than shipping a number that looks fine.

What about articles that change after publication?

We record the modification time and re-collect where it matters. Sports articles change constantly - scores fill in, headlines get rewritten - and a corpus with only a publication timestamp silently mixes the article as published with the article as it now reads.

Is it legal to scrape Bleacher Report?

Yes. Headlines, bylines, publication timestamps, sports, team sections, tags and article text are shown to every visitor. We collect only publicly available data - everything a visitor can see on Bleacher Report - and we collect it legally.

How it works

  1. 1

    Make a request

    You share your needs, expectations, and desired timeframe. We'll suggest the best solution based on your request and budget.

  2. 2

    We configure the crawlers

    Our specialists configure the crawlers and extract a sample dataset for your review before proceeding with the full-scale extraction.

  3. 3

    Collect and deliver

    Once you approve the sample, we launch the project and start full data collection. We gather, filter, and structure the data for easy use, delivering it on time in your preferred format.

  4. 4

    Maintain and support

    Our team manages ongoing processes, monitors website changes, and supports all data extraction cycles. We can also help integrate data into your systems or create dashboards to simplify analysis.

Request a quote

Tell us which sites, which fields and how often. A couple of lines is enough to start.

  • We reply within 1 business day
  • A sample dataset before the full run
  • We sign an NDA on request
  • Delivery by API, JSON feed or files
Which sites, which fields, how often. A couple of lines is enough.

This form is protected by Google reCAPTCHA, which loads when you start filling it in. If you prefer not to use it, email us at info@scrapeit.io. Privacy & Cookie Policy

We reply within 1 business day. No obligation.

Bleacher Report data from €169/month. Free project assessment, reply within 1 business day.