Pluto TV Scraper for Linear Channels and Schedules

There is no catalogue to browse here, there is a schedule that already started. Miss the hour and that slot is gone with no record of it.

Plans from €169 a month · Free project assessment · Reply within 1 business day

CSV · Excel · JSON · XML · FTP · SFTP · Amazon S3 · Google Cloud

pluto.tv
Pluto TV Scraper for Linear Channels and Schedules
pluto.tvwhat you get
Typical fields for streaming services
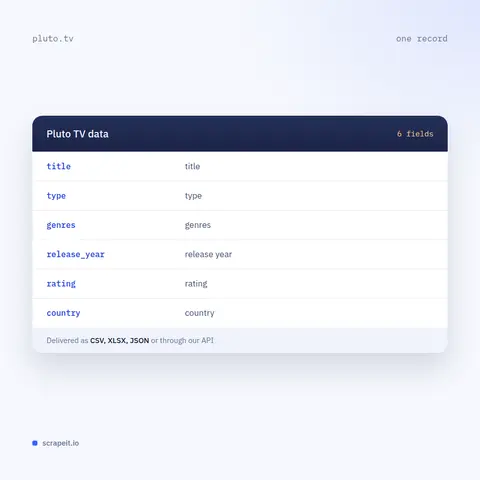
titletypegenresrelease_yearratingcountry
Delivery

API, JSON feed or CSV, XLSX and JSON files

Schedule

One-time, monthly, weekly, daily or 3 times a day

Managed schedule data, run end to end by us

  1. You send

    Pluto TV pages, filters, fields and a schedule

  2. We run the scrapers

    Built, monitored and repaired by our team

  3. You receive the data

    API, JSON feed or CSV, XLSX and JSON files

ScrapeIt runs the collection as a managed service. You name the regions and channel categories; we build the pipeline capturing schedules as they run, with timezone and region on every row and the on demand section typed separately, and hand back CSV, JSON, Excel or a push into your warehouse.

Collection has to run continuously to be worth anything here, so this is a monitored feed rather than a one-time job, and we quote it as one.

We collect published schedule metadata only - never streams, never anything behind a sign in, no viewer data - and pace requests. All of it is publicly available data - everything a visitor can see on Pluto TV - and we collect it legally.

Pluto TV fields in every export

Channel records carry the channel name, number, category or genre, language, region and the description as published.

Schedule records are keyed to the channel: programme title, series and episode identifiers where published, start time with timezone, end time, duration, genre and rating. Timezone is not optional on a service scheduling across regions - a slot time without it is a guess.

Region is a first class field because channel line-ups differ between countries. The same service name carries different channels in different markets, and merging them produces a line-up that exists nowhere.

The on demand section is typed separately, since a title in a library and a slot in a schedule share almost no fields and the distinction is the whole point of this source.

Every row carries the collection timestamp, which on schedule data is what tells you when the observation was actually made rather than when the slot was supposed to run.

Pluto TV fields in every export
Repetition analysis, daypart patterns and limits

Repetition analysis, daypart patterns and limits

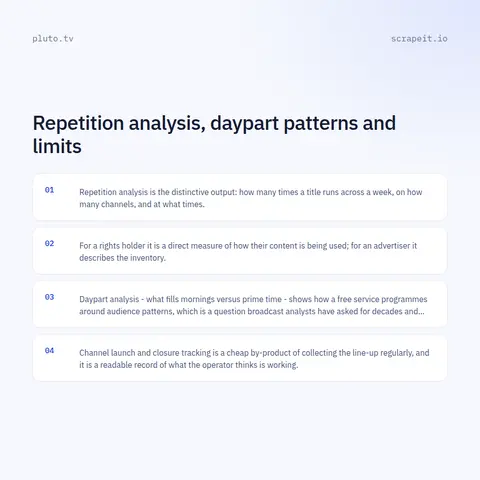
Repetition analysis is the distinctive output: how many times a title runs across a week, on how many channels, and at what times. For a rights holder it is a direct measure of how their content is being used; for an advertiser it describes the inventory.

Daypart analysis - what fills mornings versus prime time - shows how a free service programmes around audience patterns, which is a question broadcast analysts have asked for decades and rarely get to ask of streaming.

Channel launch and closure tracking is a cheap by-product of collecting the line-up regularly, and it is a readable record of what the operator thinks is working.

Limits: metadata only, never streams, nothing behind a sign in, no viewer data. And history begins when collection does, which on this source is the single most important thing to agree before quoting.

Free linear television, not a video library

Source
pluto.tv
Category
streaming services
Delivery
API, JSON feed, CSV, XLSX
Plans
From €169 a month
Get a quote

Pluto TV is a free ad-supported streaming service built around linear channels. Rather than a library a viewer browses, it runs hundreds of themed channels on schedules, much like broadcast television, alongside a smaller on demand section.

That makes it structurally different from every subscription service in this section and it changes the data problem completely. A catalogue is a list that persists; a schedule is a sequence of slots that happen and then stop existing.

The consequence is that the dataset has to be captured as it runs. What was on channel forty-two at nine in the evening last Tuesday is not published afterwards, so the schedule is a time series by construction and only exists from the moment collection begins.

Channel and live schedule pages respond directly with a large amount of content. Every visitor sees the channel name, number and category, and for each slot the programme title, start and end time, genre and rating.

25Developers
500+Customers
1.5BPages extracted
15,000+Hours saved for our clients

Pluto TV scraping plans and pricing

Airplane

€199one-time

Setup fee included

100,000
One-time
Up to 5 days
7 days

Helicopter

€169/ mo

Setup fee €499

250,000
Monthly
Up to 5 days
14 days

Glasses

€229/ mo

Setup fee €499

1,000,000
Weekly
Up to 5 days
30 days

Microscope popular

€349/ mo

Setup fee €499

2,000,000
Daily
Same day
60 days

DNA

€549/ mo

Setup fee €799

3,000,000
3 times daily
Same day
90 days

Delivery: CSV, JSON or XLSX files, our API or a JSON feed. MCP server on request.

Full plan details

Why a schedule cannot be collected retrospectively

Clients arrive asking for the Pluto TV catalogue and there is not really one, which is worth saying in the first minute rather than delivering something adjacent.

What there is instead is more interesting for the questions people usually have. Free ad-supported linear television is a growing category and almost nobody has structured data about what actually runs on it. Which content fills the hours, how often a title repeats, how much of a channel is licensed library versus originals - those are schedule questions and they are answerable only from observation.

The second point is that the schedule is perishable in a way catalogues are not. A title removed from a subscription library at least leaves the library behind; a slot that has run leaves nothing at all. There is no back catalogue to buy, and a client wanting a year of schedule history needs a year of collection.

The third is repetition, which is the defining economics of this model. Free linear channels repeat heavily, and measuring how heavily - per channel, per title, per daypart - is the analysis rights holders and advertisers actually want. It falls straight out of a properly collected schedule and is invisible from anything else.

The fourth is regional line-up differences, which are substantial and only visible if region is collected as a field from the start.

Who builds and keeps your schedule feed

ScrapeIt is a managed extraction company, not a tool you have to learn. Our team builds the pipeline, watches it as channel line-ups change, and repairs it quickly, because on schedule data an outage is a permanent hole rather than a delay.

You see a sample first, in your format, over the regions and channels you actually care about, with a real observation window so you can see repetition in the data rather than take it on description.

FAQ

Still unsure? Write to info@scrapeit.io

Can I have the Pluto TV catalogue?

There is not really one, and that is worth saying in the first minute. It is a linear service: hundreds of channels on schedules. The on demand section is smaller and typed separately. The schedule is the dataset.

Can you get last month's schedule?

No. A slot that has run leaves nothing behind - unlike a library title, which at least leaves the library. There is no back catalogue to buy, so a year of schedule history needs a year of collection.

What is repetition analysis good for?

For a rights holder it measures how their content is actually being used - how many runs, on how many channels, in which dayparts. For an advertiser it describes the inventory. It falls straight out of a properly collected schedule and is invisible from anything else.

Why does region matter?

Because channel line-ups differ substantially between countries. The same service name carries different channels in different markets, and merging them produces a line-up that exists nowhere. Region is a field from the first row.

What happens if collection stops for a day?

That day is permanently missing, which is why we treat outages here more seriously than on catalogue sources. On a schedule feed an interruption is a hole in the record rather than a delay in delivery.

How it works

  1. 1

    Make a request

    You share your needs, expectations, and desired timeframe. We'll suggest the best solution based on your request and budget.

  2. 2

    We configure the crawlers

    Our specialists configure the crawlers and extract a sample dataset for your review before proceeding with the full-scale extraction.

  3. 3

    Collect and deliver

    Once you approve the sample, we launch the project and start full data collection. We gather, filter, and structure the data for easy use, delivering it on time in your preferred format.

  4. 4

    Maintain and support

    Our team manages ongoing processes, monitors website changes, and supports all data extraction cycles. We can also help integrate data into your systems or create dashboards to simplify analysis.

Request a quote

Tell us which sites, which fields and how often. A couple of lines is enough to start.

  • We reply within 1 business day
  • A sample dataset before the full run
  • We sign an NDA on request
  • Delivery by API, JSON feed or files
Which sites, which fields, how often. A couple of lines is enough.

This form is protected by Google reCAPTCHA, which loads when you start filling it in. If you prefer not to use it, email us at info@scrapeit.io. Privacy & Cookie Policy

We reply within 1 business day. No obligation.

Pluto TV data from €169/month. Free project assessment, reply within 1 business day.