How Can Web Scraping Technology Help the Finance Industry?
Web scraping automates the extraction and aggregation of financial data, makes it easier to find stocks, and allows you to predict the market based on the information.

CoinGecko tracks about 19,700 coins across 465 chains and about 1,500 exchanges. We collect the price, supply, pool and contract fields it publishes, on the schedule you set.
Plans from €169/month · Free project assessment · Reply within 1 business day
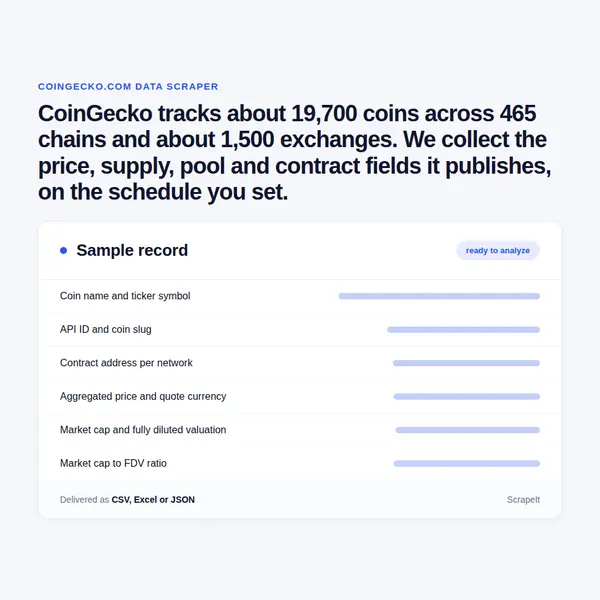
You send a coin list, or ask for the whole tracked universe, and name the tabs you need. ScrapeIt writes parsing logic against CoinGecko markup, runs it on your cadence and returns a sample before the full pass. Anti-bot handling, proxy rotation and CAPTCHA solving are part of the service - the site puts a challenge in front of automated clients, so the crawl is browser-grade by design.
Coverage is planned from the nine declared sitemaps plus the index pages, because the maps under-report: the English coin map lists about 15,700 addresses against about 19,700 coins tracked. Frequency is an agreement, not a claim of live data. Crypto moves every second, so a dataset is a series of snapshots taken at the interval you pick, and every row is stamped with the moment it was taken.
We extract CoinGecko coin pages field by field, as published, with no renaming and no invented columns.
Output is CSV, JSON, XLSX or a database drop. Every row carries the coin slug, the API ID, the chain and contract address where one exists, the quote currency and the capture timestamp, because a CoinGecko price with no capture time cannot be reconciled against anything later.
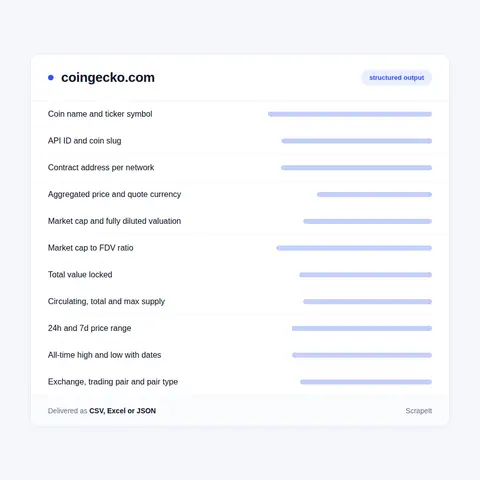
Per-pair market rows. The headline number on a coin page is a computed index, not a print from any single venue: CoinGecko builds it from the top 600 tickers by volume, removes outliers by median absolute deviation, and volume-weights what survives. That is why the markets tab is the part no single quote replaces. Each row gives the exchange, the pair, a CEX or DEX badge, the spot, perpetual or futures category, the venue price, spread, plus and minus 2 percent order book depth, 24h volume, volume share and a last-updated stamp, with anomaly and stale flags beside them.
Exchange profiles and Trust Score. A venue page publishes coin count, pair count, year established, incorporation country, maker and taker fees, accepted payment methods, exchange reserves and an API coverage grade covering tickers, order book, historical trades, OHLC and websocket. Trust Score runs 1 to 10 on a fixed weighting: liquidity 50 percent, cybersecurity 20, regulation 15, incidents 10, proof of reserves 5. Derivatives venues carry no Trust Score and rank on open interest and reported volume instead.
On-chain pools and NFT. The on-chain side indexes 228 networks with dozens of DEXes each - Ethereum alone lists 76 - and a pool row gives the pair name, pool address, reserve in USD, volume, transaction counts and the pool creation time, reachable from the same token contract address. NFT collection pages give floor price, market cap, 24h volume and 24h sales across roughly 2,100 collections, and the 969 categories are where token narratives are tracked.
CoinGecko is a crypto data aggregator, and its address plan is what turns a CoinGecko scraper into a planning job instead of a guessing game. Every asset sits at /en/coins/{slug} with a historical_data tab hanging off it and per-fiat variants such as /en/coins/chainlink/eur, /gbp and /inr. Exchanges sit at /en/exchanges/{id}, categories at /en/categories/{slug}, NFT collections at /en/nft/{slug} and corporate holdings at /en/treasuries/{slug}.
The site prints its own join key on the page. Coin and exchange pages both carry an API ID field - bitcoin, chainlink, binance - so rows from different runs and different tabs line up without matching on display names. Below it, the Info panel lists a contract address per network, which is the key that survives a rebrand and travels to block explorers, wallets and any other source you already hold.
Scale, roughly, in September 2026: about 19,700 coins, about 1,500 exchanges of which 744 are decentralized, 969 categories and 465 asset platforms carrying token contracts. Coverage is multilingual and not a simple prefix swap - there are 22 language coin sitemaps, and the exchange path segment itself is translated: intercambios in Spanish, cambi in Italian, borsalar in Turkish, pertukaran in Indonesian.
Get a Quote
Developers

Customers worldwide

Pages extracted

Hours saved for our clients
€199 / one-time
setup fee - included
€169 / mo
setup fee €499
€229 / mo
setup fee €499
€349 / mo
setup fee €499
€549 / mo
setup fee €799
Delivery: CSV, JSON or XLSX files, our API or a JSON feed. MCP server on request.
Full plan details →Breadth in one pass. Buyers scrape CoinGecko when a short watchlist is not the job: the full tracked universe in several of the 63 quote currencies, every pair on every venue, categories and NFT floors, all collected together, with every row stamped with its capture time. A coin like Bitcoin, whose markets tab runs to roughly 1,500 rows, comes back as one row per exchange and pair, with venue price, spread, depth and 24h volume.
History and joins. The historical_data tab yields date, market cap, volume and close per day, and the contract address on each network links a token to block explorers, wallets, on-chain pools and any other source you already hold. The same crawler serves a short watchlist or the whole universe, on the schedule you set.
Public data, collected legally. We collect only publicly available data - everything a visitor can see on CoinGecko - and we collect it legally.
Learn how to use web scraping to solve data problems for your organization
Web scraping automates the extraction and aggregation of financial data, makes it easier to find stocks, and allows you to predict the market based on the information.
Data and analytics are opening the door to uncovering ways to combat financial crime based on smart data. And advanced AI analytics and cognitive techniques, machine learning, and automation will improve the inefficiency of existing investigative processes.

Leveraging advances in technology, the AI-powered web scraper has skyrocketed in demand and is helping to expand capabilities by automating tedious daily tasks and speeding up data collection from thousands of websites several times over.
ScrapeIt runs the CoinGecko scraper as a managed service. We build, run and repair the crawlers; you receive files or an endpoint, with nothing to install and no infrastructure to keep alive. We publish no signals, no forecasts and no trading calls - we deliver market data, and what you conclude from it is your work. We do not collect personal information about individuals, whether wallet owners or forum posters.
Yes. The ScrapeIt CoinGecko API returns price in your quote currency, market cap, circulating supply, the contract address on each network and per-pair market rows as JSON from an endpoint we host, refreshed on the schedule you set. The same data also comes as CSV or XLSX files or straight into your database.
That is the join we build around. A coin page lists the contract address for each network the token is issued on, with its decimal place, and CoinGecko recognises 465 asset platforms in total. Chainlink alone shows 88 network entries, and about 4,100 tracked coins live on two or more chains. We deliver one row per coin and network, so a token can be matched against your own holdings, a block explorer or an on-chain pool by address rather than by name - which is the only key that survives a rebrand or a ticker collision.
Exchange profiles give coin count, pair count, year established, incorporation country, fee schedule, accepted payment methods, reserves, and the API coverage grade for tickers, order book, historical trades, OHLC and websocket, plus Trust Score with its liquidity, regulation, cybersecurity, incident and proof of reserves components. Per pair we return exchange, pair, CEX or DEX, spot, perpetual or futures, price, spread, plus and minus 2 percent depth, 24h volume, volume share and the last-updated stamp. Decentralized venues and their pools are collected the same way.
Frequency is set by agreement: minutes, hourly, several times a day or once a day. We do not sell live data, and we would be lying if we did - crypto trades every second, so what you receive is a snapshot series, with every row carrying the moment of capture. Formats are CSV, JSON, XLSX, Parquet or a direct load into your warehouse, and delivery can be an S3 drop, an SFTP push or an endpoint. Schema stays fixed between runs so nothing downstream breaks when a page layout changes.
Yes. On CoinGecko we collect coin prices, market caps, supply, contract addresses, per-pair market rows and exchange profiles. We work only on pages a signed-out visitor can reach, we do not log in, and we do not collect personal data about individuals. We collect only publicly available data - everything a visitor can see on CoinGecko - and we collect it legally.
Step 1 - Make a Request
You share your needs, expectations, and desired timeframe. We’ll suggest the best solution based on your request and budget.
Step 2 - Configuring Custom Web Crawlers
Our specialists configure the crawlers and extract a sample dataset for your review before proceeding with the full-scale extraction.
Step 3 - Collect and Deliver
Once you approve the sample, we launch the project and start full data collection. We gather, filter, and structure the data for easy use, delivering it on time in your preferred format.
Step 4 - Maintain and Support
Our team manages ongoing processes, monitors website changes, and supports all data extraction cycles. We can also help integrate data into your systems or create dashboards to simplify analysis.
CoinGecko data from €169/month. Free project assessment, reply within 1 business day.

Scrapeit Sp. z o.o.
10/208 Legionowa str., 15-099, Bialystok, Poland
NIP: 5423457175
REGON: 523384582


