Google Maps Data: Local Businesses from 1,000 US Cities Every Weekday
A weekday feed of local businesses from Google Maps for a local-marketing company: 1,000 US cities, three keywords a day, files by 10:00 UTC.
Reddit sorts public conversation into communities with their own rules and flair. We turn subreddits, posts and whole comment threads into rows with score, upvote ratio, flair and reply depth.
Plans from €169 a month · Free project assessment · Reply within 1 business day
CSV · Excel · JSON · XML · FTP · SFTP · Amazon S3 · Google Cloud
API, JSON feed or CSV, XLSX and JSON files
ScheduleOne-time, monthly, weekly, daily or 3 times a day
Reddit pages, filters, fields and a schedule
Built, monitored and repaired by our team
API, JSON feed or CSV, XLSX and JSON files
ScrapeIt runs Reddit scraping as a managed service, not as a Reddit scraping tool you install and babysit. You name the scope - subreddits, brand and product keywords, or a list of thread URLs - and we build the Reddit crawler, schedule it and fix it when Reddit changes its pages. Reddit screens automated traffic hard, so anti-bot handling, proxy rotation and CAPTCHA solving are part of the service. We collect public and restricted communities with no logins, so private, quarantined and 18+ communities stay out. Every row keeps Reddit's IDs and permalinks, so runs merge without duplicates. Delivery is CSV, JSON Lines, XLSX or Parquet to S3, SFTP or your warehouse, or through the ScrapeIt Reddit scraper API, hourly, daily, weekly or once.
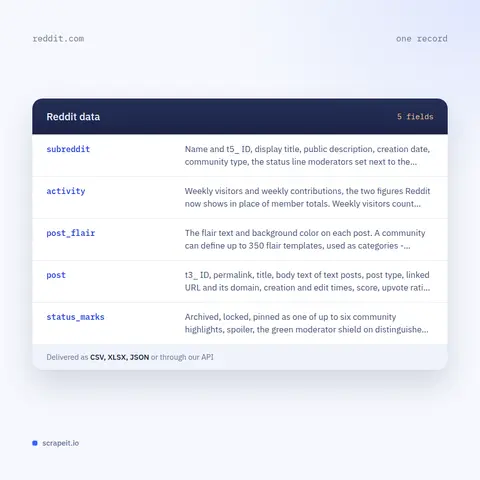
To extract Reddit data we read three levels - community, post and comment - and every row keeps Reddit's own IDs, so a comment always leads back to its post and its subreddit. Comments get their own section below; the first two levels carry these fields.
The author of a post or comment is kept as the public username, hashed or dropped, as you prefer.
A Reddit comment scraper is only as good as its thread reconstruction. Each comment row carries its t1_ ID, its parent ID - another comment or the post itself - its depth and position among siblings, score, creation time and permalink, so the comment tree can be rebuilt exactly or flattened into rows. To scrape Reddit threads completely, we open the "more replies" and "Continue this thread" branches that Reddit folds away, and we record the sort order the thread was read in.
Deleted and removed comments keep their place: "Comment deleted by user" and "Comment removed by moderator" stay as empty markers, so reply chains do not break. Reddit's own comment count still includes removed comments, so it often runs higher than the replies you can see, and we deliver both numbers. Labels add context: OP on replies by the original poster, MOD and ADMIN on moderators and staff, the automated-account label on bots such as AutoModerator, and a collapsed flag on comments Reddit folds as likely spam.
Scores move. Reddit hides vote counts during a post's first hours, and a community can hide comment scores for up to 24 hours, so we store dated snapshots rather than one value. Where a community archives old posts, threads older than six months stop taking votes and comments, and Reddit archived posts get one final pass. Reddit also machine-translates posts and comments into languages such as French, German, Spanish, Portuguese, Italian, Hindi and Thai; we keep the original text with its language code.
A Reddit scraper has to follow the way Reddit itself is built: around communities rather than people. Each subreddit, from r/buildapcsales to r/SkincareAddiction, is created and run by volunteer moderators who write its rules, set its post flair and decide what may be posted. As of June 2026 Reddit reports more than 100,000 active communities and over 130 million daily active uniques.
Communities come in four types. Public ones are open to read, restricted ones are open to read but limit who may post or comment, and private and premium-only communities stay closed to visitors. Communities labeled Mature (18+) sit behind sign-in and an age check, and quarantined ones behind an explicit opt-in.
Inside a community every post has a short base-36 ID with the t3_ prefix and an address of the form /r/community/comments/ID/title/; every comment has its own t1_ ID and a permalink under its post, and the subreddit itself has a t5_ ID. A post can be text, a link, images or a gallery, a video, a poll or a repost of another community's post, and each carries a title, a vote score, an upvote ratio and a comment count. Comments nest into reply trees of any depth. Feeds sort by Best, Hot, New, Top and Rising, with Top limited to the past hour, day, week, month, year or all time, and comment sections sort by Best, Top, New, Controversial, Old or Q&A.
Delivery: CSV, JSON or XLSX files, our API or a JSON feed. MCP server on request.
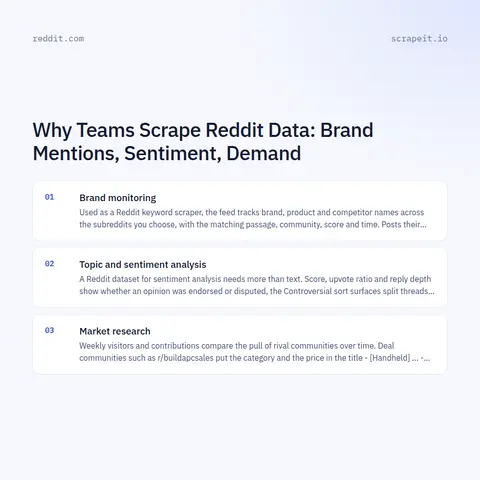
Full plan detailsReddit threads are where people ask what to buy, report what broke and argue over alternatives, in their own words and with a vote score attached. Three uses come up most.
Learn how to use web scraping to solve data problems for your organization
Where opinion text lives on the public web, what a review record contains on each kind of site, which fields a model needs besides the text, and what quietly breaks a sentiment dataset - with examples from our own projects.
Using web scraping to extract Google Maps data will help you quickly and efficiently find businesses in any industry, city, state, or region. And the extracted contact information, such as phone or email address, social networks, or links to web pages, will help to contact them.
Lead scraping is a reliable way to get the right customer contacts to market your product, saves organizations time, and helps you better understand the audience you want to attract. Contacts include emails, phone numbers, or social media profiles.

ScrapeIt is a managed web scraping agency, so instead of a Reddit web scraper to maintain you get a delivered dataset. Tell us the question - every mention of your product in 40 subreddits, a month of posts from five hobby communities with full threads, or a daily feed of new deals - and an engineer designs the collection and keeps it running. A sample comes first, so you check fields, thread depth and fill rates before committing. The price of a Reddit dataset depends on how many communities it covers, how deep the threads go and how often it refreshes.
Still unsure? Write to info@scrapeit.io
Yes. The ScrapeIt Reddit API returns the dataset we collect for you as JSON: subreddits with description, rules, flair list and weekly visitors and contributions; posts with ID, permalink, title, body, type, link, media URLs, flair, score, upvote ratio, comment count and timestamps; and comments with parent ID, depth, score and text. It updates on the schedule you set, and every delivery is also available as CSV or XLSX.
Yes. Every comment row carries its own ID, its parent's ID, its depth and its position, so the thread rebuilds exactly as Reddit shows it or loads flat into a spreadsheet. Branches folded behind "more replies" and "Continue this thread" are expanded, deleted and removed comments stay as empty placeholders, and the sort order is recorded. Images, GIFs and videos posted inside comments come through as media URLs. As a Reddit thread scraper it also takes a plain list of thread URLs, and very long threads can be taken in full or capped at a depth or comment count you choose.
Two ways, usually combined. For the subreddits you name, we read the New feed on a schedule and match titles, post text and comments against your keyword list, so mentions in those communities are caught as they appear. To find new places, we run Reddit search for each keyword across posts and comments, sorted by New or Relevance with a time filter from the past hour to all time, and add communities that keep turning up to the watch list. Each match keeps the passage, post, community, score and time.
As often as the question needs: hourly or daily for brand monitoring, weekly or once for research. Scores and comment counts keep changing after a post goes up, and Reddit hides vote counts during a post's first hours, so we re-read posts at set ages - for example after 1 hour, 24 hours and 7 days - and store each snapshot with its time. Files come as CSV, JSON Lines, XLSX or Parquet in S3, SFTP or your warehouse, or through our API.
We collect only publicly available data - everything a visitor can see on Reddit - and we collect it legally. That covers public communities with their rules and flair, posts and comment threads, with no logins and nothing from private communities. Usernames are pseudonyms, yet GDPR still treats them as personal data, so we never build user dossiers: no profile pages and no post history of any one person.
You share your needs, expectations, and desired timeframe. We'll suggest the best solution based on your request and budget.
Our specialists configure the crawlers and extract a sample dataset for your review before proceeding with the full-scale extraction.
Once you approve the sample, we launch the project and start full data collection. We gather, filter, and structure the data for easy use, delivering it on time in your preferred format.
Our team manages ongoing processes, monitors website changes, and supports all data extraction cycles. We can also help integrate data into your systems or create dashboards to simplify analysis.
Tell us which sites, which fields and how often. A couple of lines is enough to start.
Reddit data from €169/month. Free project assessment, reply within 1 business day.