Wall Street Journal Data: Headlines, Corrections and Citations

401 means authenticate. For the Journal, the authenticated route is a licence, and it gives you better data than any crawl of the website ever could.

Plans from €169 a month · Free project assessment · Reply within 1 business day

CSV · Excel · JSON · XML · FTP · SFTP · Amazon S3 · Google Cloud

wsj.com
Wall Street Journal Data: Headlines, Corrections and Citations
wsj.comwhat you get
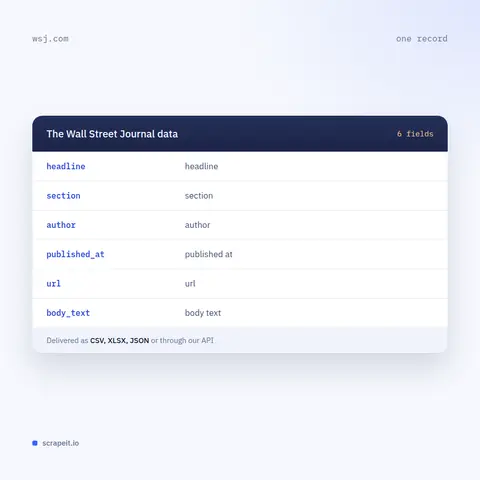
Typical fields for news sites
headlinesectionauthorpublished_aturlbody_text
Delivery

API, JSON feed or CSV, XLSX and JSON files

Schedule

One-time, monthly, weekly, daily or 3 times a day

Managed Wall Street Journal collection, run end to end by us

  1. You send

    The Wall Street Journal pages, filters, fields and a schedule

  2. We run the scrapers

    Built, monitored and repaired by our team

  3. You receive the data

    API, JSON feed or CSV, XLSX and JSON files

ScrapeIt runs the work as a managed service. You name the companies, sectors and subjects; we build the pipeline, keep corrections as records and the source type on every row, and hand back CSV, JSON, Excel or a push into your warehouse.

Before quoting we scope what is answered from the Journal's own pages and what from citations in other outlets.

We never log in and never go behind the subscription. We collect only publicly available data - everything a visitor can see on The Wall Street Journal - and we collect it legally.

What a Journal dataset carries

Article records carry the headline, standfirst, byline, section, publication and update timestamps and article identifier, as the site shows them to a visitor.

Corrections are kept as their own records rather than overwritten, because for research on financial reporting the difference between the first published version and the corrected one can be the finding.

Citation records show where other outlets cite or follow Journal reporting.

Every row carries the collection timestamp and its source type.

What a Journal dataset carries
Coverage research, correction tracking and citations

Coverage research, correction tracking and citations

Coverage research is the core use: coverage of a company, sector or theme over time, structured for analysis.

Correction tracking is a distinctive output for anyone studying financial journalism, since the gap between first publication and correction is measurable when both are kept.

Citation analysis shows which Journal stories other outlets followed, and how quickly.

We never log in and never go behind the subscription, so every row carries what the site shows a visitor.

A leading business paper behind a subscription

Source
wsj.com
Category
news sites
Delivery
API, JSON feed, CSV, XLSX
Plans
From €169 a month
Get a quote

The Wall Street Journal is one of the leading business and financial newspapers in the world, published behind a subscription by Dow Jones.

What the site shows a visitor without a subscription can be collected: headlines, standfirsts, bylines, sections, publication and update timestamps and article identifiers.

That shapes the project here: the Journal's own public record of what it reported and when, and measurement of its influence through the other outlets that cite and follow its reporting.

25Developers
500+Customers
1.5BPages extracted
15,000+Hours saved for our clients

The Wall Street Journal scraping plans and pricing

Airplane

€199one-time

Setup fee included

100,000
One-time
Up to 5 days
7 days

Helicopter

€169/ mo

Setup fee €499

250,000
Monthly
Up to 5 days
14 days

Glasses

€229/ mo

Setup fee €499

1,000,000
Weekly
Up to 5 days
30 days

Microscope popular

€349/ mo

Setup fee €499

2,000,000
Daily
Same day
60 days

DNA

€549/ mo

Setup fee €799

3,000,000
3 times daily
Same day
90 days

Delivery: CSV, JSON or XLSX files, our API or a JSON feed. MCP server on request.

Full plan details

Why teams track Journal coverage over time

For the questions people actually bring - how a company was covered over years, what was reported before a market event, how coverage of a sector changed - the public record of headlines, standfirsts, bylines, sections and timestamps is the backbone. Collected on a schedule, it shows what the Journal chose to report and when.

Corrections add a second layer. Keeping the first published version and the corrected one side by side makes the gap between them measurable, which is a finding in itself for anyone studying financial journalism.

Influence is the third question: which Journal stories other newsrooms picked up and how quickly. Citation records answer it from the outlets doing the citing.

Who builds and keeps your Journal feed

ScrapeIt is a managed extraction company, not a tool you have to learn. Our team structures the content for analysis, keeps corrections attached to the data, and maintains the pipeline as formats change.

You see a sample first, in your format, over the companies and sectors you actually track, including a citation analysis from other outlets, so you can judge the value before committing.

FAQ

Still unsure? Write to info@scrapeit.io

Can you scrape the Wall Street Journal?

Yes, what the site shows a visitor: headlines, standfirsts, bylines, sections, publication and update timestamps and article identifiers, with corrections kept as their own records. We never log in or go behind the subscription. We collect only publicly available data - everything a visitor can see on The Wall Street Journal - and we collect it legally.

Do you offer a Wall Street Journal API?

Yes. The ScrapeIt Wall Street Journal API returns headlines, standfirsts, bylines, sections, timestamps and correction records as JSON from an endpoint we host, refreshed on the schedule you set. The same data also comes as CSV or XLSX files or straight into your database.

Can you track how the Journal covered a company over time?

Yes. Headlines, standfirsts, sections and timestamps collected on a schedule show how a company, sector or theme was covered, what was reported before a market event and how that coverage changed.

Why keep corrections separately?

Because for research on financial reporting the difference between the first published version and the corrected one can be the finding. Overwriting the original with the correction destroys exactly that.

Can I measure the Journal's influence on other outlets?

Yes, through citations and follow-ups in other outlets. That shows which Journal stories other newsrooms picked up and how quickly.

How it works

  1. 1

    Make a request

    You share your needs, expectations, and desired timeframe. We'll suggest the best solution based on your request and budget.

  2. 2

    We configure the crawlers

    Our specialists configure the crawlers and extract a sample dataset for your review before proceeding with the full-scale extraction.

  3. 3

    Collect and deliver

    Once you approve the sample, we launch the project and start full data collection. We gather, filter, and structure the data for easy use, delivering it on time in your preferred format.

  4. 4

    Maintain and support

    Our team manages ongoing processes, monitors website changes, and supports all data extraction cycles. We can also help integrate data into your systems or create dashboards to simplify analysis.

Request a quote

Tell us which sites, which fields and how often. A couple of lines is enough to start.

  • We reply within 1 business day
  • A sample dataset before the full run
  • We sign an NDA on request
  • Delivery by API, JSON feed or files
Which sites, which fields, how often. A couple of lines is enough.

This form is protected by Google reCAPTCHA, which loads when you start filling it in. If you prefer not to use it, email us at info@scrapeit.io. Privacy & Cookie Policy

We reply within 1 business day. No obligation.

The Wall Street Journal data from €169/month. Free project assessment, reply within 1 business day.