CNBC Scraper for Market News Linked to Ticker Symbols

The useful question on a markets desk is never how many articles. It is which instrument was written about, when, and what the price did afterwards.

Plans from €169 a month · Free project assessment · Reply within 1 business day

CSV · Excel · JSON · XML · FTP · SFTP · Amazon S3 · Google Cloud

cnbc.com
CNBC Scraper for Market News Linked to Ticker Symbols
cnbc.comwhat you get
Typical fields for news sites
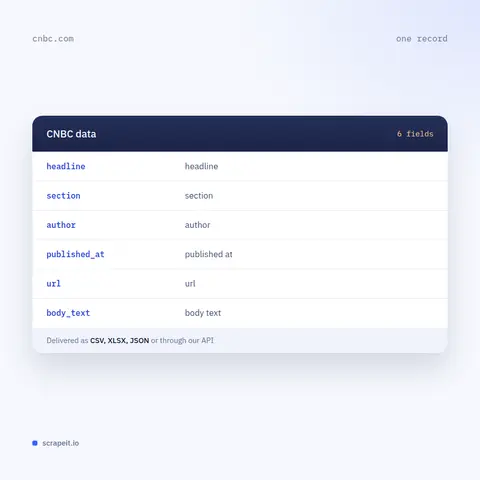
headlinesectionauthorpublished_aturlbody_text
Delivery

API, JSON feed or CSV, XLSX and JSON files

Schedule

One-time, monthly, weekly, daily or 3 times a day

Managed business news collection, run end to end by us

  1. You send

    CNBC pages, filters, fields and a schedule

  2. We run the scrapers

    Built, monitored and repaired by our team

  3. You receive the data

    API, JSON feed or CSV, XLSX and JSON files

ScrapeIt runs the collector as a managed service. You name the sections, symbols or sectors; we build the pipeline, run it on your cadence and hand back CSV, JSON, Excel or a push into your warehouse, with ticker associations as rows and timestamps precise to the minute.

Cadence is set against the trading session rather than the clock: frequent through market hours and around scheduled releases, slower overnight. That is both cheaper and more useful than a flat interval.

We pace requests and collect only publicly available data - everything a visitor can see on CNBC - and we collect it legally. It is coverage data, not market data and not investment advice.

CNBC fields in every export

The article record covers canonical URL, headline, summary, section and subsection, byline, publication timestamp, last updated timestamp, item type and the article identifier.

Ticker association is the field that makes this source worth collecting. Symbols attached to a story are delivered as rows rather than a string, each with the exchange where it resolves, so a story about three companies produces three joinable rows instead of one unusable cell.

Both timestamps are kept apart, and on a markets source the gap between them matters more than usual: a story updated repeatedly through a session is following a developing move, and that is a different event from a piece published once.

Front and section observations record what was promoted, in what order and when. On a markets front, promotion through a trading session is itself a signal about what the desk considered material.

Then the usual context: topic tags where published, publicly rendered body text and word count, outbound links, video duration where the item is a video, and the collection timestamp on every row.

CNBC fields in every export
Quote pages, earnings clusters and joining to price data

Quote pages, earnings clusters and joining to price data

Quote pages exist per symbol and respond, which makes it possible to collect the site's own view of an instrument alongside the coverage attached to it. What we do not do is present that as market data: this source is for the coverage.

Earnings clusters need deliberate handling. Volume spikes hard around reporting dates, and the mix shifts towards preview and reaction pieces. Typing content and keeping precise timestamps lets a client model those windows separately instead of letting them distort a full year trend.

Joining to price data is the standard extension and the reason most clients buy this source. Coverage rows carry the symbol and the minute; price series come from wherever the client licenses them; the join is on symbol and time. We build that join rather than handing over two datasets and a problem.

Historical backfill is practical because article URLs are stable and section pagination reaches back. It runs as a one time job separate from the ongoing feed.

A markets newsroom where stories carry tickers

Source
cnbc.com
Category
news sites
Delivery
API, JSON feed, CSV, XLSX
Plans
From €169 a month
Get a quote

CNBC is a business and markets newsroom, and its structure reflects that. Stories are attached to companies and instruments, quote pages exist per symbol and respond directly, and the section tree is organised around markets, investing, technology and economy rather than around a general news desk.

That attachment is the reason to collect this source rather than a general outlet. Elsewhere you have to infer which company a story is about from the text. Here the association is published, which turns a media dataset into something that joins cleanly to financial data.

Discovery is straightforward: a news sitemap covers recent items and responds, section fronts carry ordered selections, and quote pages exist per symbol. Article pages carry structured markup with headline, publisher and timestamps.

Volume is high and skewed by the trading day. Coverage clusters around market open, earnings releases and macro announcements, which matters for any time series: a naive daily count reads the trading calendar rather than the news.

25Developers
500+Customers
1.5BPages extracted
15,000+Hours saved for our clients

CNBC scraping plans and pricing

Airplane

€199one-time

Setup fee included

100,000
One-time
Up to 5 days
7 days

Helicopter

€169/ mo

Setup fee €499

250,000
Monthly
Up to 5 days
14 days

Glasses

€229/ mo

Setup fee €499

1,000,000
Weekly
Up to 5 days
30 days

Microscope popular

€349/ mo

Setup fee €499

2,000,000
Daily
Same day
60 days

DNA

€549/ mo

Setup fee €799

3,000,000
3 times daily
Same day
90 days

Delivery: CSV, JSON or XLSX files, our API or a JSON feed. MCP server on request.

Full plan details

Why the ticker link changes what the data can answer

Media data and market data live in different systems, and joining them is usually the hardest part of any event study. Company names are ambiguous, the same firm appears under several forms, and inferring an instrument from prose is error prone in exactly the cases that matter.

On this source the link is published. A story carries the symbols it is about, so coverage attaches to an instrument without inference. That makes the questions people actually have answerable: how much coverage preceded a move, whether attention clustered before or after an earnings release, which competitor in a sector gets written about more and when.

The second reason is timing precision. On a markets source, the minute matters. A story published two minutes before a move and one published an hour after are different facts entirely, and both timestamps plus a collection timestamp are needed to say which you are holding.

The third is the trading calendar. Coverage volume is shaped by market hours, earnings season and macro release dates, and a daily count that ignores that is measuring the calendar. Timestamped rows let a client normalise against the session rather than against the day.

The fourth caution is one we state plainly: this is published journalism, not a market signal product. It tells you what was written and when. Anything further is your model, and the responsibility for it is yours.

Who builds and keeps your market news feed

ScrapeIt is a managed extraction company, not a tool you have to learn. Our team builds the pipeline, watches it through earnings seasons and site changes, and repairs it before your series develops a hole.

You see a sample first, in your format, over the symbols or sectors you actually track, with ticker associations already resolved so you can test the join against your own price data.

FAQ

Still unsure? Write to info@scrapeit.io

Do stories really come with ticker symbols attached?

Yes, and that is the main reason to collect this source rather than a general outlet. The association is published rather than inferred from prose, so coverage attaches to an instrument without guesswork. We deliver symbols as rows, not a string, so a story about three companies produces three joinable rows.

Can this be joined to price data?

That is the standard project. Coverage rows carry the symbol and the minute; the price series comes from wherever you license it; the join is on symbol and time. We build the join rather than handing over two datasets and leaving you to reconcile them.

Do you provide market data as well?

No. We can collect what the site publishes on its quote pages, but we do not present that as market data and would not recommend using it that way. Use this source for what it is, which is coverage.

How do you handle earnings season spikes?

By typing content and keeping precise timestamps, so preview and reaction pieces around reporting dates can be modelled as their own window. Untreated, earnings season distorts a full year trend and a daily count ends up measuring the trading calendar rather than the news.

Is this a trading signal?

No, and we say so plainly. It is published journalism with timestamps and ticker associations: what was written, about which instrument, and when. Anything beyond that is your model and your responsibility.

How it works

  1. 1

    Make a request

    You share your needs, expectations, and desired timeframe. We'll suggest the best solution based on your request and budget.

  2. 2

    We configure the crawlers

    Our specialists configure the crawlers and extract a sample dataset for your review before proceeding with the full-scale extraction.

  3. 3

    Collect and deliver

    Once you approve the sample, we launch the project and start full data collection. We gather, filter, and structure the data for easy use, delivering it on time in your preferred format.

  4. 4

    Maintain and support

    Our team manages ongoing processes, monitors website changes, and supports all data extraction cycles. We can also help integrate data into your systems or create dashboards to simplify analysis.

Request a quote

Tell us which sites, which fields and how often. A couple of lines is enough to start.

  • We reply within 1 business day
  • A sample dataset before the full run
  • We sign an NDA on request
  • Delivery by API, JSON feed or files
Which sites, which fields, how often. A couple of lines is enough.

This form is protected by Google reCAPTCHA, which loads when you start filling it in. If you prefer not to use it, email us at info@scrapeit.io. Privacy & Cookie Policy

We reply within 1 business day. No obligation.

CNBC data from €169/month. Free project assessment, reply within 1 business day.