Business Insider Scraper for Editions, Paywall and Coverage

The same story runs across a dozen country editions with local rewrites. Count them all and one piece of coverage becomes twelve.

Plans from €169 a month · Free project assessment · Reply within 1 business day

CSV · Excel · JSON · XML · FTP · SFTP · Amazon S3 · Google Cloud

businessinsider.com
Business Insider Scraper for Editions, Paywall and Coverage
businessinsider.comwhat you get
Typical fields for news sites
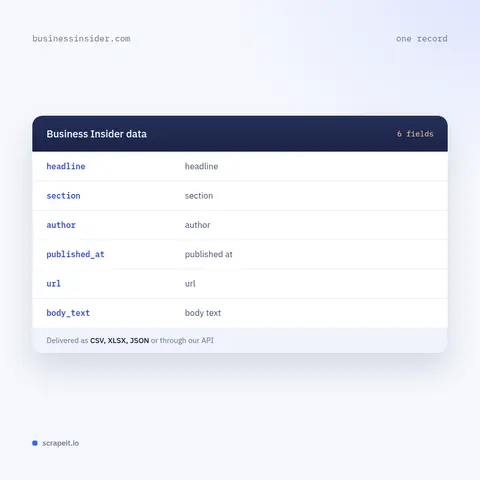
headlinesectionauthorpublished_aturlbody_text
Delivery

API, JSON feed or CSV, XLSX and JSON files

Schedule

One-time, monthly, weekly, daily or 3 times a day

Managed Business Insider collection, run end to end by us

  1. You send

    Business Insider pages, filters, fields and a schedule

  2. We run the scrapers

    Built, monitored and repaired by our team

  3. You receive the data

    API, JSON feed or CSV, XLSX and JSON files

ScrapeIt runs the collector as a managed service. You name the editions, sections and companies; we build the pipeline, group stories across editions, flag subscriber articles and hand back CSV, JSON, Excel or a push into your warehouse with edition and language on every row.

Cadence is per edition. The markets you care about run frequently; the rest run slowly or not at all. Requests are paced.

We collect what the site renders publicly and flag restricted articles rather than working around the tier. We do not use subscriber credentials. We collect only publicly available data - everything a visitor can see on Business Insider - and we collect it legally.

Business Insider fields in every export

The article record covers canonical URL, headline, standfirst, edition, language, section, byline, publication timestamp, last updated timestamp, item type and the article identifier.

Edition and language are separate fields because several editions publish in the same language for different markets, and regional analysis needs the distinction.

Story grouping across editions is delivered rather than left as an exercise. Where the same piece appears in several editions, translated or rewritten, the rows share a story identifier produced by near duplicate detection and entity overlap, so coverage can be counted once globally or once per market as the question requires.

The access flag records whether the article was subscriber restricted at collection time and how much text rendered publicly, so an opening is never mistaken for a full article.

Then the context fields: topic tags where published, word count of the publicly rendered portion, outbound links, front position from repeated observation, and the collection timestamp on every row.

Business Insider fields in every export
Market comparison, translation and the archive

Market comparison, translation and the archive

Market comparison is the natural output once editions are separated properly. Which markets carried a story, how quickly, at what length, and which ignored it. For a company operating internationally that picture is far more useful than a single global number.

Translated versions need handling rather than deduplication into oblivion. A translated piece is the same story and a different artefact: it reached a different audience and may carry a different headline emphasis. We group it with the original and keep its own text and language rather than discarding it.

Discovery on this source leans on section fronts and the published HTML sitemap index, since the conventional news sitemap path is not served. That costs a few more requests and produces prominence data as a by product.

Historical backfill is practical because URLs are stable and section pagination reaches back, and it runs as a one time job separate from the ongoing feed.

A network of editions with heavy shared coverage

Source
businessinsider.com
Category
news sites
Delivery
API, JSON feed, CSV, XLSX
Plans
From €169 a month
Get a quote

Business Insider publishes a United States edition alongside a network of international editions, several of them in other languages and run with local editorial teams. Coverage overlaps heavily: a story written for one edition frequently appears in others, sometimes translated, sometimes rewritten for a local angle.

That is the structural problem this source presents. Treating the editions as one site double counts the shared material; treating one edition as the whole publisher loses every other market. Either error is invisible from the output.

A subscriber tier sits over part of the output. On restricted articles the headline, the standfirst and an opening portion render publicly and the rest does not, which is the usual boundary and the one we work up to rather than past.

Section fronts respond directly and an HTML sitemap index is published, so discovery is practical, though the conventional news sitemap path is not served. Volume is high and skewed towards aggregation style content, which is worth typing rather than treating as reporting.

25Developers
500+Customers
1.5BPages extracted
15,000+Hours saved for our clients

Business Insider scraping plans and pricing

Airplane

€199one-time

Setup fee included

100,000
One-time
Up to 5 days
7 days

Helicopter

€169/ mo

Setup fee €499

250,000
Monthly
Up to 5 days
14 days

Glasses

€229/ mo

Setup fee €499

1,000,000
Weekly
Up to 5 days
30 days

Microscope popular

€349/ mo

Setup fee €499

2,000,000
Daily
Same day
60 days

DNA

€549/ mo

Setup fee €799

3,000,000
3 times daily
Same day
90 days

Delivery: CSV, JSON or XLSX files, our API or a JSON feed. MCP server on request.

Full plan details

Why edition grouping decides the size of every number

A company gets written about once. The piece runs in the United States edition, then in four European editions and three Asian ones, two of them translated. An ungrouped feed reports eight mentions from a major business title, and the report goes to a board.

The factor here is larger than on most networks because the editions genuinely share so much. Getting it wrong does not produce a slightly inflated number, it produces one several times too large, and it inflates unevenly depending on which stories happened to syndicate.

Grouped, the same data says one story, eight placements, in these markets, which is both accurate and more useful: the market list is what an international communications team actually wants.

The second reason is the subscriber tier. Without the access flag, opening paragraphs enter the dataset as complete articles and every length and sentiment measure built on it inherits the error silently.

The third is content type. A substantial share of output is aggregation and listicle style material rather than original reporting, and clients measuring editorial attention usually want those separable. The distinction is visible on the page and worth carrying into the data.

Who builds and keeps your Business Insider feed

ScrapeIt is a managed extraction company, not a tool you have to learn. Our team builds the pipeline, watches it as editions and templates change independently, and repairs it before a market quietly drops out of your reporting.

You see a sample first, in your format, across the editions you actually track, with story grouping applied so you can see how much of your count was one story wearing several hats.

FAQ

Still unsure? Write to info@scrapeit.io

How much does edition overlap inflate the numbers?

Several times over, and unevenly, which is worse. The editions share a great deal of coverage, so one story can appear as eight mentions, and the inflation depends on which stories happened to syndicate. Grouped, the same data says one story and eight placements with the market list attached, which is both accurate and more useful.

How do you group the same story across editions?

With near duplicate detection over the text plus entity overlap, producing a shared story identifier. Translated versions are grouped with the original rather than discarded, because a translation is the same story and a different artefact: different audience, sometimes different headline emphasis.

Can you collect subscriber articles in full?

No. We do not use subscriber credentials. We collect the headline, standfirst, byline, section, timestamps, front position and the opening text that renders publicly, with the article flagged as restricted. Without that flag, openings enter the dataset as complete articles and every measure built on it is quietly wrong.

Can aggregation content be separated from reporting?

Yes, and most clients want it separable. A substantial share of output is aggregation and listicle style material rather than original reporting, the distinction is visible on the page, and carrying it into the data lets you measure editorial attention rather than publishing volume.

Which editions can you cover?

Any of the international editions, scoped to the markets you care about rather than all of them by default. Every row carries both edition and language, because several editions publish in the same language for different markets and regional analysis needs the distinction.

How it works

  1. 1

    Make a request

    You share your needs, expectations, and desired timeframe. We'll suggest the best solution based on your request and budget.

  2. 2

    We configure the crawlers

    Our specialists configure the crawlers and extract a sample dataset for your review before proceeding with the full-scale extraction.

  3. 3

    Collect and deliver

    Once you approve the sample, we launch the project and start full data collection. We gather, filter, and structure the data for easy use, delivering it on time in your preferred format.

  4. 4

    Maintain and support

    Our team manages ongoing processes, monitors website changes, and supports all data extraction cycles. We can also help integrate data into your systems or create dashboards to simplify analysis.

Request a quote

Tell us which sites, which fields and how often. A couple of lines is enough to start.

  • We reply within 1 business day
  • A sample dataset before the full run
  • We sign an NDA on request
  • Delivery by API, JSON feed or files
Which sites, which fields, how often. A couple of lines is enough.

This form is protected by Google reCAPTCHA, which loads when you start filling it in. If you prefer not to use it, email us at info@scrapeit.io. Privacy & Cookie Policy

We reply within 1 business day. No obligation.

Business Insider data from €169/month. Free project assessment, reply within 1 business day.