JSTOR Scraper for Articles, Journal Issues, Books and Primary Sources

JSTOR keeps journal runs from volume 1 up to the moving wall, next to books, think-tank reports and primary sources. We turn its public records into rows keyed on stable IDs.

Plans from €169 a month · Free project assessment · Reply within 1 business day

CSV · Excel · JSON · XML · FTP · SFTP · Amazon S3 · Google Cloud

jstor.org
JSTOR Scraper for Articles, Journal Issues, Books and Primary Sources
jstor.orgwhat you get
Typical fields for education sites
course_titleproviderpricedurationstart_daterating
Delivery

API, JSON feed or CSV, XLSX and JSON files

Schedule

One-time, monthly, weekly, daily or 3 times a day

Managed JSTOR Scraping, From One Journal to a Whole Discipline

  1. You send

    JSTOR pages, filters, fields and a schedule

  2. We run the scrapers

    Built, monitored and repaired by our team

  3. You receive the data

    API, JSON feed or CSV, XLSX and JSON files

ScrapeIt runs JSTOR scraping as a managed service. You name the scope - journals, a subject, a publisher, a collection, a JSTOR list of journals you already keep or a set of DOIs - and we build the collector, host it and repair it when JSTOR changes its pages. JSTOR screens automated traffic with client challenges and CAPTCHA, so anti-bot handling, proxy rotation and CAPTCHA solving are part of the job. We extract JSTOR data from public pages only: no logins, no paywalls, and full texts behind a subscription stay out of scope. Rows keep JSTOR's stable IDs and DOIs and arrive as CSV, JSON, XLSX or Parquet in S3, SFTP or your warehouse, or through the ScrapeIt JSTOR API.

Scrape JSTOR Data Item by Item: Articles, Issues, Books, Chapters

Each JSTOR item page, including the one shown to a visitor without access, carries a complete bibliographic record. We collect it under JSTOR's own identifiers, so every row leads back to its stable URL.

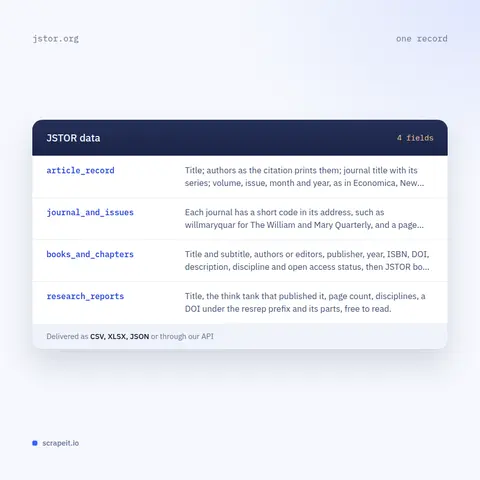
  • Article recordTitle; authors as the citation prints them; journal title with its series; volume, issue, month and year, as in Economica, New Series, Vol. 4, No. 16 (Nov., 1937); page range and page count; ISSN, DOI and stable URL; the publisher line, often a press publishing on behalf of a society; and the disciplines JSTOR assigns, such as Business and Economics. Item type tells full-length articles from JSTOR book reviews and miscellaneous items such as front matter, and an access flag marks what anyone can read. Where JSTOR shows an abstract or a summary, it comes with its label, including JSTOR's note when a summary was written by an AI system.
  • Journal and issuesEach journal has a short code in its address, such as willmaryquar for The William and Mary Quarterly, and a page that lists the publisher, coverage as years and volume numbers, the moving wall, ISSN and EISSN, subjects, the collections that include it and a title history of earlier names. Issues are grouped by decade with number, month and page range, and each has its own i-prefixed ID and table of contents, so JSTOR journal issues line up from the first number to the last one the wall releases.
  • Books and chaptersTitle and subtitle, authors or editors, publisher, year, ISBN, DOI, description, discipline and open access status, then JSTOR book chapters one by one with title, page range and chapter DOI: book j.ctv102bd16 holds parts j.ctv102bd16.1 to .12, front matter paged in roman numerals.
  • Research reportsTitle, the think tank that published it, page count, disciplines, a DOI under the resrep prefix and its parts, free to read.

The JSTOR metadata stays joinable: article to issue, issue to journal, chapter to book, and every item to its publisher and to subjects grouped under headings such as Area Studies, Law or Science & Mathematics.

Scrape JSTOR Data Item by Item: Articles, Issues, Books, Chapters
Open Content, Primary Sources and JSTOR Price Data

Open Content, Primary Sources and JSTOR Price Data

Part of JSTOR is free to everyone, and we tag it rather than mix it in. JSTOR early journal content covers articles published more than 95 years ago in the United States, or more than 143 years ago elsewhere, across hundreds of journals. JSTOR open access content adds open journals, thousands of open books, including Path to Open titles that turn open after a licensed period, tens of thousands of research reports from think tanks and close to a million Open Artstor images, while Reveal Digital adds open collections such as American Prison Newspapers. JSTOR Daily, the free magazine JSTOR publishes, ends each story with a Resources list of free-to-read scholarship. For JSTOR free content we note which open program covers each item, so a reading list can be filtered to what anyone can open.

JSTOR primary sources and images carry the fields their museums and archives supplied: title, creator, date, work type, culture, material, location, holding institution, collection, credit line and rights.

JSTOR prices are public as well. The JSTOR subscription price for one person is JPASS: $19.50 a month with 10 PDF downloads, or $199 a year with 120, in late September 2026. Institutions pay an Annual Access Fee per collection by classification, from Very small to Very large, with one-time payment options, so the JSTOR institutional subscription price becomes a table of collection, tier and fee, and a JSTOR JPASS price change shows up between two dated snapshots.

The JSTOR Database: Journal Archives, Books, Reports and Collections

Source
jstor.org
Category
education sites
Delivery
API, JSON feed, CSV, XLSX
Plans
From €169 a month
Get a quote

A JSTOR scraper works on an archive rather than a news feed. JSTOR, short for Journal Storage, was conceived in 1994 by William G. Bowen, then president of the Mellon Foundation, to digitize the back runs of academic journals; it was founded in 1995 and has been part of the nonprofit ITHAKA, based in New York, since 2009. JSTOR is not a journal but a library of journals: most titles run from volume 1, issue 1 up to the JSTOR moving wall, a delay of 0 to 10 years, usually 3 to 5, which the publisher sets and which advances every January.

In late September 2026 JSTOR's own figures put the archive at more than 12 million journal articles from over 2,800 journals in 75-plus disciplines, next to more than 150,000 scholarly ebooks in Books at JSTOR, research reports from think tanks and millions of images and primary sources. The humanities and social sciences are the core, and the Life Sciences collection adds botany, ecology and ornithology.

Every item has a JSTOR stable URL, and for an article it rests on an integer ID: jstor.org/stable/2626876 is R. H. Coase's The Nature of the Firm, and its JSTOR DOI is 10.2307/2626876. Issue IDs start with i, books with j.ctt or j.ctv, research reports with resrep, images and shared collection items with community, while a chapter adds a sequence number to its book's ID. Browsing follows the same lines - by title, with separate lists of journals, books and research reports, by subject, by publisher and by collection - and that is how JSTOR content is cut into datasets.

25Developers
500+Customers
1.5BPages extracted
15,000+Hours saved for our clients

JSTOR scraping plans and pricing

Airplane

€199one-time

Setup fee included

100,000
One-time
Up to 5 days
7 days

Helicopter

€169/ mo

Setup fee €499

250,000
Monthly
Up to 5 days
14 days

Glasses

€229/ mo

Setup fee €499

1,000,000
Weekly
Up to 5 days
30 days

Microscope popular

€349/ mo

Setup fee €499

2,000,000
Daily
Same day
60 days

DNA

€549/ mo

Setup fee €799

3,000,000
3 times daily
Same day
90 days

Delivery: CSV, JSON or XLSX files, our API or a JSON feed. MCP server on request.

Full plan details

Why Libraries, Publishers and Researchers Collect JSTOR Records

JSTOR holds the back runs of thousands of humanities and social science journals in one format, so its records answer questions no single publisher site can.

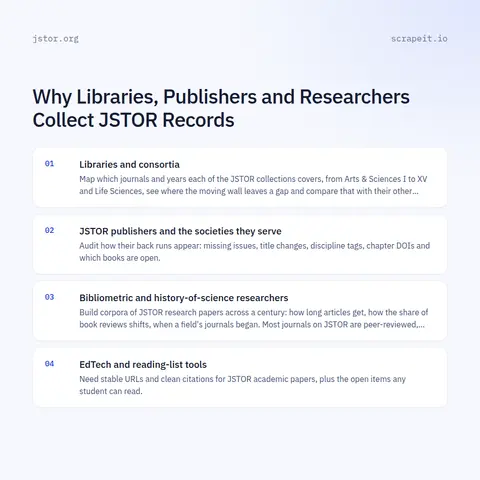
  • Libraries and consortia map which journals and years each of the JSTOR collections covers, from Arts & Sciences I to XV and Life Sciences, see where the moving wall leaves a gap and compare that with their other platforms before renewing.
  • JSTOR publishers and the societies they serve audit how their back runs appear: missing issues, title changes, discipline tags, chapter DOIs and which books are open.
  • Bibliometric and history-of-science researchers build corpora of JSTOR research papers across a century: how long articles get, how the share of book reviews shifts, when a field's journals began. Most journals on JSTOR are peer-reviewed, while primary sources, research reports and open community collections are not, and JSTOR offers no peer-review filter, so content and item type stay on every row.
  • EdTech and reading-list tools need stable URLs and clean citations for JSTOR academic papers, plus the open items any student can read.
  • Policy analysts follow JSTOR research reports by think tank, topic and date.

JSTOR works as a scholarly source because a journal passes a selection review, weighing rankings and citation data, before it joins; research reports and primary sources are marked as what they are.

Ordering a JSTOR Dataset or a Recurring Feed

ScrapeIt is a managed web scraping agency, not a self-serve tool. Tell us which JSTOR records you need and a named engineer designs the crawl, runs it and keeps it working through JSTOR's redesigns. To scrape JSTOR across a whole discipline we split the job by journal and decade and resume where a run stopped. You check a sample before committing, in your own schema, and the price follows scope and refresh rate rather than page count.

FAQ

Still unsure? Write to info@scrapeit.io

Do you offer a JSTOR API?

Yes. The ScrapeIt JSTOR API returns JSTOR records as JSON on the schedule you set: articles with authors, journal, volume, issue, date, pages, DOI, stable URL, discipline and access flag; issues with their contents; journals with coverage and moving wall; books with chapter DOIs; research reports; collection items; and price tables. Query it by stable ID, DOI, journal code or subject, and take any delivery as a JSTOR export to CSV or XLSX as well.

Can you deliver a JSTOR list of journals with coverage and moving walls?

Yes. JSTOR subjects, publisher pages and journal pages give every head title with its earlier names, publisher, ISSN and EISSN, subjects, collections, coverage in years and volumes, and the moving wall. A table of JSTOR law journals, for example, comes from the Law subject and includes the student-run law reviews of Arts & Sciences IV. Rows carry the journal code, so issues and articles join to them later, and first and last years show how far back each run reaches.

What does JSTOR show without a subscription, and what stays out?

The full bibliographic record stays visible: title, authors, journal and series, volume and issue, date, pages, publisher line, ISSN, DOI, stable URL, disciplines, item type and open access status, plus any abstract or labelled summary. The article text of most of the archive sits behind institutional access or a personal plan, and we leave it there. Open items - early journal content, open access books and research reports - are flagged, so you know what a reader can open at once.

How often can a JSTOR dataset be refreshed, and in what formats?

Journal coverage moves mainly in early January, when each moving wall advances a year and a new year of issues joins the archive, so a quarterly or yearly pass keeps journal and issue tables current. Books, open titles, research reports and shared collections grow through the year and suit a weekly or monthly pass, and prices can be checked on any day you choose. Files come as CSV, JSON, XLSX or Parquet, delivered to S3, SFTP or your warehouse.

Is it legal to scrape JSTOR?

We collect only publicly available data - everything a visitor can see on JSTOR - and we collect it legally. That covers bibliographic records, journal and issue pages, book and chapter listings, subject and collection pages, open items and published prices, with no logins and no paywalls. Author names stay inside each citation: we do not build researcher profiles or dossiers, and any personal data is handled under GDPR.

How it works

  1. 1

    Make a request

    You share your needs, expectations, and desired timeframe. We'll suggest the best solution based on your request and budget.

  2. 2

    We configure the crawlers

    Our specialists configure the crawlers and extract a sample dataset for your review before proceeding with the full-scale extraction.

  3. 3

    Collect and deliver

    Once you approve the sample, we launch the project and start full data collection. We gather, filter, and structure the data for easy use, delivering it on time in your preferred format.

  4. 4

    Maintain and support

    Our team manages ongoing processes, monitors website changes, and supports all data extraction cycles. We can also help integrate data into your systems or create dashboards to simplify analysis.

Request a quote

Tell us which sites, which fields and how often. A couple of lines is enough to start.

  • We reply within 1 business day
  • A sample dataset before the full run
  • We sign an NDA on request
  • Delivery by API, JSON feed or files
Which sites, which fields, how often. A couple of lines is enough.

This form is protected by Google reCAPTCHA, which loads when you start filling it in. If you prefer not to use it, email us at info@scrapeit.io. Privacy & Cookie Policy

We reply within 1 business day. No obligation.

JSTOR data from €169/month. Free project assessment, reply within 1 business day.