How Can Web Scraping Technology Help the Finance Industry?
Web scraping automates the extraction and aggregation of financial data, makes it easier to find stocks, and allows you to predict the market based on the information.
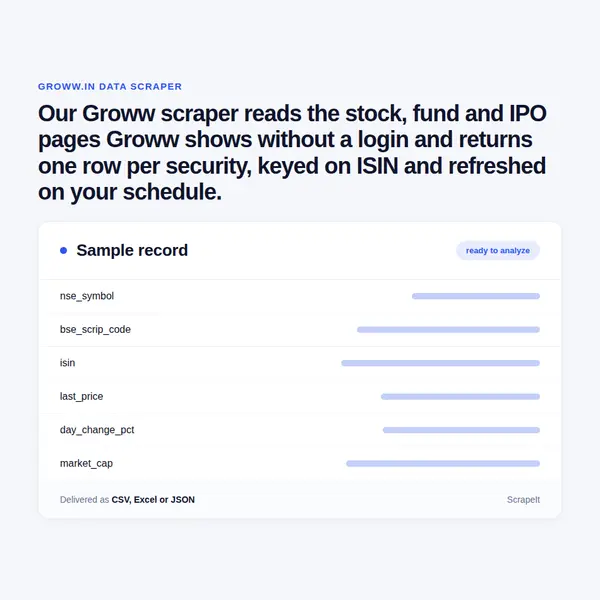
Our Groww scraper reads the stock, fund and IPO pages Groww shows without a login and returns one row per security, keyed on ISIN and refreshed on your schedule.
Plans from €169 a month · Free project assessment · Reply within 1 business day
CSV · Excel · JSON · XML · FTP · SFTP · Amazon S3 · Google Cloud
API, JSON feed or CSV, XLSX and JSON files
ScheduleOne-time, monthly, weekly, daily or 3 times a day
Groww pages, filters, fields and a schedule
Built, monitored and repaired by our team
API, JSON feed or CSV, XLSX and JSON files
You tell us what to cover - a watchlist of NSE and BSE symbols, every scheme of one fund house, a mutual fund category, the IPO calendar - and which columns matter. We build the crawler for Groww's stock, fund and IPO templates, run it on the schedule you set and repair it when a page layout changes. Pacing, proxy rotation and rendering are part of the service, not something you arrange.
Groww prints amounts in Indian digit grouping with a crore suffix, with commas after every second digit in the lakh and crore positions. We convert every figure to a plain number, keep the unit in its own column and deliver CSV, Excel or JSON files, a load into your database or our API, with field documentation. Plans start from EUR 169 a month, or EUR 199 for a one-time extract.
Groww keeps one page per security, and the identifiers behind each page are what make repeated runs line up: an ISIN and a BSE scrip code for every stock, an ISIN and a scheme code for every fund plan. We key rows on those codes rather than on names, because Groww serves an old fund address under the scheme's current name.
Fund pages also name the managers and print their education and career. Those are personal details, so they stay out of the dataset by default.
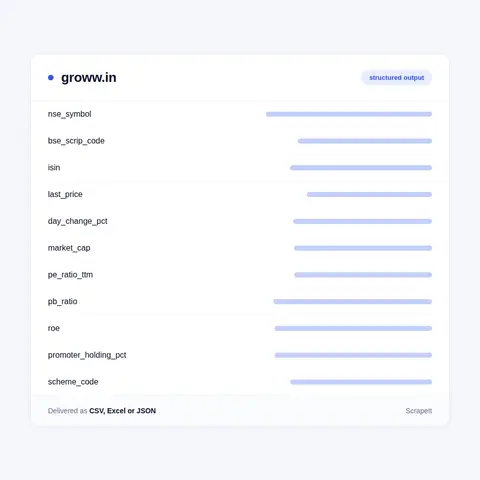
A stock or fund page is the smallest unit. Most projects start from a list page on Groww and fan out from there:
Groww shows the current figure and a few fixed windows. Repeated runs build the price history: a daily pass stores close, NAV, AUM and expense ratio by date, so a NAV series or an exit load change becomes a table you own.
Groww is an Indian investing app based in Bengaluru. Its website doubles as a reference library: listed stocks, mutual fund schemes, ETFs, indices and IPOs each have an open page, and none of the figures on them needs an account. Orders, portfolios and trading screens sit behind the login; the pages we work with do not.
The address tells you the page type: /stocks/ for listed companies, /mutual-funds/ for scheme plans, then /etfs/, /indices/, /ipo/ and /commodities/ for MCX futures and options. Stock pages are tabbed into Overview, Technicals, News, Events and F&O. Fund pages are built around direct plans, with a return calculator, the holdings table, the returns and rankings grid and a fund management block. Groww also runs its own fund house, Groww Mutual Fund, whose schemes sit in the same catalogue as every other AMC's.
Everything is priced in rupees for the Indian market: NSE and BSE listings, Indian fund houses, MCX contracts and gold rates by state. Prices move through the trading day, each NAV carries the date it was struck, and holdings and the shareholding pattern change when a new period is published.
Delivery: CSV, JSON or XLSX files, our API or a JSON feed. MCP server on request.
Full plan detailsGroww puts fields an analyst would otherwise gather from several places onto one page per security, in one layout for every company and scheme. That makes it a practical source for:
We deliver the data, not recommendations: what you conclude from it is yours.
Learn how to use web scraping to solve data problems for your organization
Web scraping automates the extraction and aggregation of financial data, makes it easier to find stocks, and allows you to predict the market based on the information.
Data and analytics are opening the door to uncovering ways to combat financial crime based on smart data. And advanced AI analytics and cognitive techniques, machine learning, and automation will improve the inefficiency of existing investigative processes.
Data scraping is the wide term that includes documents, scans and old screens; web scraping is the part that works on websites. We compare sources, daily work, output and cost drivers, give a briefing checklist and walk through two of our projects.

ScrapeIt is a managed web scraping service. We build, run and maintain crawlers for finance sites such as Groww, where one page mixes live prices, periodic disclosures and dated corporate events, and we hand over the result as files or through our API. Every dataset comes with field documentation, a free project assessment comes first, and a sample on your own symbols or schemes can be ordered before a schedule starts.
Still unsure? Write to info@scrapeit.io
Yes. The ScrapeIt Groww API returns symbol, ISIN, last price, market cap, NAV, expense ratio and holdings as JSON from an endpoint we host, refreshed on the schedule you set. The same data also comes as CSV or XLSX files, a JSON feed or a load into your database.
Yes. Stock, fund, ETF and IPO pages on Groww are open to any visitor without an account. We collect only publicly available data - everything a visitor can see on Groww - and we collect it legally. Fund manager names and other personal details are left out by default, under GDPR.
As often as the fields change and you need them. Prices and volume move during market hours, a NAV carries the date it was struck, and shareholding and quarterly results change once a period is published. A daily run after the close suits prices and NAVs; weekly suits fundamentals and holdings.
Groww's fund page shows the current NAV with its date and returns over fixed periods. We build the history ourselves: each scheduled run stores NAV, AUM and expense ratio against the scheme code, so the series grows from the first run. The three, five and ten year returns travel with every row as a cross-check.
Yes. From the IPO dashboard and each IPO page we collect Mainboard and SME issues with open, close, allotment and listing dates, price band, lot size, overall subscription, issue price and listing price. Upcoming issues marked To be announced are tracked until their dates appear, so each IPO is followed from announcement to listing.
You share your needs, expectations, and desired timeframe. We'll suggest the best solution based on your request and budget.
Our specialists configure the crawlers and extract a sample dataset for your review before proceeding with the full-scale extraction.
Once you approve the sample, we launch the project and start full data collection. We gather, filter, and structure the data for easy use, delivering it on time in your preferred format.
Our team manages ongoing processes, monitors website changes, and supports all data extraction cycles. We can also help integrate data into your systems or create dashboards to simplify analysis.
Tell us which sites, which fields and how often. A couple of lines is enough to start.
Groww data from €169/month. Free project assessment, reply within 1 business day.