BBC iPlayer Scraper for Titles and Availability Windows

Most of this catalogue is leaving. A title without the date it expires is half a record, and the half that is missing is the half that moves.

Plans from €169 a month · Free project assessment · Reply within 1 business day

CSV · Excel · JSON · XML · FTP · SFTP · Amazon S3 · Google Cloud

bbc.co.uk
BBC iPlayer Scraper for Titles and Availability Windows
bbc.co.ukwhat you get
Typical fields for streaming services
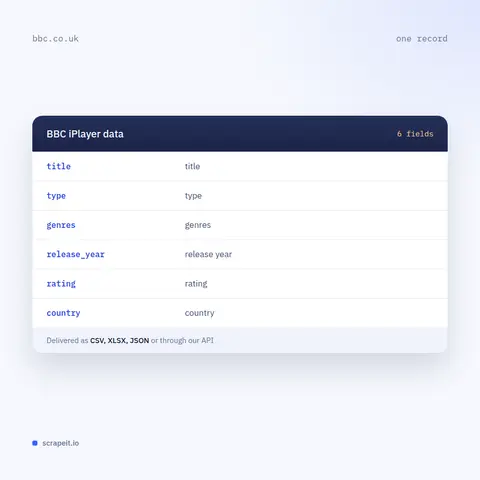
titletypegenresrelease_yearratingcountry
Delivery

API, JSON feed or CSV, XLSX and JSON files

Schedule

One-time, monthly, weekly, daily or 3 times a day

Managed catalogue metadata, run end to end by us

  1. You send

    BBC iPlayer pages, filters, fields and a schedule

  2. We run the scrapers

    Built, monitored and repaired by our team

  3. You receive the data

    API, JSON feed or CSV, XLSX and JSON files

ScrapeIt runs the collection as a managed service. You name the channels, genres or the full index; we build the pipeline, resolve relative availability windows to absolute dates, keep series structure intact, and hand back CSV, JSON, Excel or a push into your warehouse.

Cadence matters more here than almost anywhere in this category, because the value is in the change record. Daily or weekly collection with arrivals and departures as their own records is what we recommend and quote.

We collect published metadata only - never streams, never anything behind a sign in - and pace requests. Everything we collect is publicly available - what any visitor can see on BBC iPlayer - and we collect it legally.

BBC iPlayer fields in every export

The programme record covers the title, series and episode identifiers, episode title, synopsis at both short and long lengths where published, category, first broadcast date, duration and the originating channel.

Availability is the centre of the record, not a footnote: the date a programme became available, the date it expires, and the window in days. Where the page states a relative window we resolve it to an absolute date at collection time, because a row saying twenty-eight days left is meaningless the moment it is stored.

Series structure is preserved as a hierarchy. A series with four episodes is not four unrelated rows, and flattening it loses the ability to ask questions about ordering, gaps and completeness.

Signposting attributes - audio description, subtitles, sign language - are collected where published, since accessibility coverage is a genuine research question about public service broadcasting and the data supports it.

Every row carries the collection timestamp, which is what makes an expiry date interpretable at all.

BBC iPlayer fields in every export
Departure alerts, accessibility coverage and limits

Departure alerts, accessibility coverage and limits

Departure alerting is the most operationally useful output: a feed of what is leaving in the next week or month, which for anyone tracking rights or planning coverage is directly actionable and is simply a query over collected expiry dates.

Arrival tracking is the mirror image and shows what a broadcaster is putting on demand after transmission, at what speed, and with what window.

Accessibility coverage analysis is a research use the data supports well. Which proportion of the catalogue carries subtitles, audio description or signing, and how that differs by genre and channel, is answerable once the attributes are collected as fields rather than left in page furniture.

The limit to state clearly is that this is metadata and never content. We collect titles, descriptions, categories and availability. We do not touch streams, and we do not go near anything requiring a sign in. The service is geo-restricted for playback and that restriction is theirs to enforce, not ours to work around.

A catalogue defined by how long things stay

Source
bbc.co.uk
Category
streaming services
Delivery
API, JSON feed, CSV, XLSX
Plans
From €169 a month
Get a quote

BBC iPlayer is the on demand service of the UK public broadcaster, carrying programmes from the BBC's television channels plus originals and archive.

The feature that shapes every project here is impermanence. Most programmes are available for a fixed window - commonly thirty days after broadcast, sometimes a year, sometimes indefinitely - and the remaining time is published on the page. A catalogue snapshot without those dates records what exists today and tells you nothing about what will exist next month, which is usually the question.

Discovery is straightforward. An alphabetical index responds directly and carries substantial content, and every title in it leads to a programme page with its episodes and availability.

Access to play anything is limited to the UK and funded by the licence fee, but the programme metadata - titles, synopses, categories, episode structure and availability - is published openly and is what these projects collect.

25Developers
500+Customers
1.5BPages extracted
15,000+Hours saved for our clients

BBC iPlayer scraping plans and pricing

Airplane

€199one-time

Setup fee included

100,000
One-time
Up to 5 days
7 days

Helicopter

€169/ mo

Setup fee €499

250,000
Monthly
Up to 5 days
14 days

Glasses

€229/ mo

Setup fee €499

1,000,000
Weekly
Up to 5 days
30 days

Microscope popular

€349/ mo

Setup fee €499

2,000,000
Daily
Same day
60 days

DNA

€549/ mo

Setup fee €799

3,000,000
3 times daily
Same day
90 days

Delivery: CSV, JSON or XLSX files, our API or a JSON feed. MCP server on request.

Full plan details

Why expiry dates are the whole point

A one-off snapshot of this catalogue is the least useful thing you can buy from it, and it is what most briefs ask for first.

The catalogue turns over continuously. Programmes arrive after broadcast and leave when their window closes, so the interesting facts are arrivals and departures rather than the standing list. Those only exist if the expiry dates were captured and kept, and they cannot be reconstructed afterwards from a service that has already removed the title.

The second reason is that windows themselves are a signal. A programme given a year is being treated differently from one given thirty days, and the pattern across genres and channels says something about rights and about editorial priority that is not published anywhere directly.

The third is archive depth. Some material stays indefinitely and some is rotated, and for anyone studying what a public broadcaster keeps accessible, the distinction between the permanent catalogue and the rolling one is the finding.

The fourth is comparison. Tracked over time alongside other services, iPlayer answers questions about where a title is available and for how long, which is a rights question that single service data cannot address.

Who builds and keeps your iPlayer feed

ScrapeIt is a managed extraction company, not a tool you have to learn. Our team builds the pipeline, watches it as programme templates change, and repairs it before a gap opens in a change record that cannot be backfilled.

You see a sample first, in your format, over the genres you actually track, with expiry dates resolved and series structure preserved so you can judge the hard part on real programmes.

FAQ

Still unsure? Write to info@scrapeit.io

Why do you insist on expiry dates?

Because most of this catalogue is temporary and the useful facts are arrivals and departures rather than the standing list. A relative window like twenty-eight days left is meaningless once stored, so we resolve it to an absolute date at collection time.

Can you tell me what left the service last year?

Only from the point collection started. A programme whose window has closed leaves no trace on the site, so departure history exists if somebody was observing and not otherwise. We say that at scoping rather than implying the past can be recovered.

Do you collect the programmes themselves?

No. Metadata only: titles, synopses, categories, episode structure and availability. We do not touch streams and we do not go near anything requiring a sign in. Playback is geo-restricted and that restriction is theirs to enforce, not ours to work around.

Is series and episode structure preserved?

Yes, as a hierarchy rather than a flat list. A series with four episodes is not four unrelated rows, and flattening it removes any ability to ask about ordering, gaps or completeness.

Can you collect accessibility attributes?

Yes, where published - subtitles, audio description and signing come through as their own fields. Coverage by genre and channel is a genuine research question about public service broadcasting and the data supports it once the attributes are fields rather than page furniture.

How it works

  1. 1

    Make a request

    You share your needs, expectations, and desired timeframe. We'll suggest the best solution based on your request and budget.

  2. 2

    We configure the crawlers

    Our specialists configure the crawlers and extract a sample dataset for your review before proceeding with the full-scale extraction.

  3. 3

    Collect and deliver

    Once you approve the sample, we launch the project and start full data collection. We gather, filter, and structure the data for easy use, delivering it on time in your preferred format.

  4. 4

    Maintain and support

    Our team manages ongoing processes, monitors website changes, and supports all data extraction cycles. We can also help integrate data into your systems or create dashboards to simplify analysis.

Request a quote

Tell us which sites, which fields and how often. A couple of lines is enough to start.

  • We reply within 1 business day
  • A sample dataset before the full run
  • We sign an NDA on request
  • Delivery by API, JSON feed or files
Which sites, which fields, how often. A couple of lines is enough.

This form is protected by Google reCAPTCHA, which loads when you start filling it in. If you prefer not to use it, email us at info@scrapeit.io. Privacy & Cookie Policy

We reply within 1 business day. No obligation.

BBC iPlayer data from €169/month. Free project assessment, reply within 1 business day.