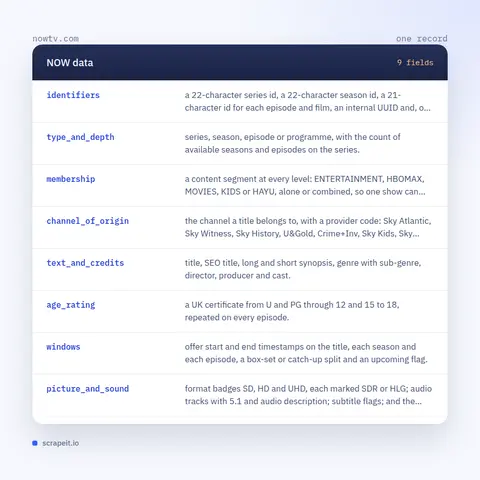
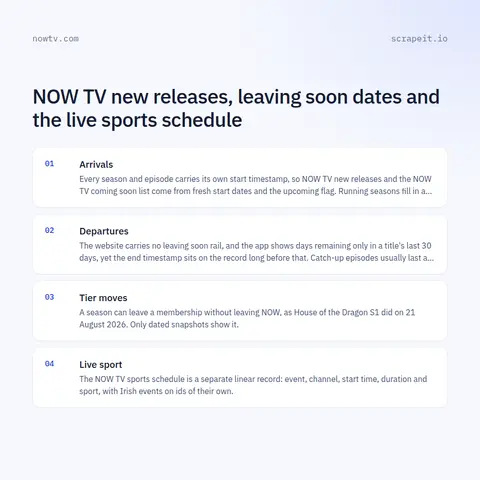
A NOW scraping project is scoped by storefront and membership rather than by page count: the HBO Max shelf in the UK and Ireland, say, or Sky Cinema with its end dates, or the Italian Entertainment pass. We build the NOW scraper on the sitemaps, which Sky already cuts by membership, pull the record behind each title and season, pair British and Irish rows on their shared ids and match Italian titles by name, year and cast. You get CSV, JSON or XLSX files or an API feed, in a schema agreed up front.
Anti-bot handling, proxy rotation and CAPTCHA solving are ours to run. The limits are fixed as well: public catalogue pages only, no sign-in, nothing from the player, the streams or the DRM, and nothing about members - no accounts, watchlists or viewing history.