IMDb Scraper for Titles, Ratings, Credits and Charts

IMDb shows the same film under a different title, certificate and release date depending on the visitor's country. Our IMDb scraper pins every row to the tt id and the original title.

Plans from €169 a month · Free project assessment · Reply within 1 business day

CSV · Excel · JSON · XML · FTP · SFTP · Amazon S3 · Google Cloud

imdb.com
IMDb Scraper for Titles, Ratings, Credits and Charts
imdb.comwhat you get
Typical fields for streaming services
titletypegenresrelease_yearratingcountry
Delivery

API, JSON feed or CSV, XLSX and JSON files

Schedule

One-time, monthly, weekly, daily or 3 times a day

IMDb Scraping as a Managed Service

  1. You send

    IMDb pages, filters, fields and a schedule

  2. We run the scrapers

    Built, monitored and repaired by our team

  3. You receive the data

    API, JSON feed or CSV, XLSX and JSON files

You send the scope - a list of tt ids, a genre and year range from Advanced title search, the Top 250, a studio's slate, every episode of a set of TV series - and we return the table. We build the crawler, run it once or on your schedule, and repair it when IMDb changes its page layout.

IMDb turns away plain automated requests and loads parts of each page with scripts, so rendering, pacing, proxy rotation and CAPTCHA handling are part of the service. Because titles, certificates and release dates follow the visitor's country, we fix the country each run is read from and write it into every row. We never sign in: IMDbPro sections and anything else behind an account stay outside the dataset.

What Our IMDb Data Scraper Collects

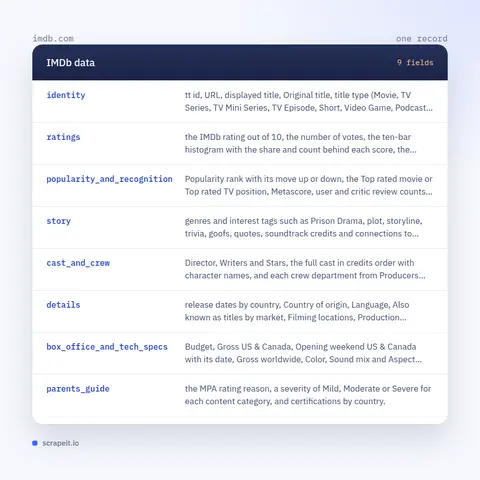
Every title lives at /title/ plus an IMDb id that starts with tt, every person at /name/ plus an id that starts with nm, and neither key changes with the language the page is shown in. A row per title carries:

  • Identitytt id, URL, displayed title, Original title, title type (Movie, TV Series, TV Mini Series, TV Episode, Short, Video Game, Podcast Series), year or year span, certificate and runtime.
  • Ratingsthe IMDb rating out of 10, the number of votes, the ten-bar histogram with the share and count behind each score, the unweighted mean and the countries with the most ratings.
  • Popularity and recognitionPopularity rank with its move up or down, the Top rated movie or Top rated TV position, Metascore, user and critic review counts, the awards line and how many users added the title to a Watchlist.
  • Storygenres and interest tags such as Prison Drama, plot, storyline, trivia, goofs, quotes, soundtrack credits and connections to other titles.
  • Cast and crewDirector, Writers and Stars, the full cast in credits order with character names, and each crew department from Producers and Cinematographer to Stunts and Visual Effects, every person with an nm id.
  • Detailsrelease dates by country, Country of origin, Language, Also known as titles by market, Filming locations, Production companies, distributors and Official sites.
  • Box office and tech specsBudget, Gross US & Canada, Opening weekend US & Canada with its date, Gross worldwide, Color, Sound mix and Aspect ratio.
  • Parents guidethe MPA rating reason, a severity of Mild, Moderate or Severe for each content category, and certifications by country.
  • Images and videoposter and photo addresses, photo and video counts, trailer titles and lengths.

Series add an episode table: season, episode number, air date, title, plot, rating and votes for each episode, with seasons kept as their own column. Name pages return professions, Known for titles and the credit list by role - the public record of published work. Family and other private details on name pages are left out by default.

What Our IMDb Data Scraper Collects
IMDb Movie Scraper: Charts, Episodes and History

IMDb Movie Scraper: Charts, Episodes and History

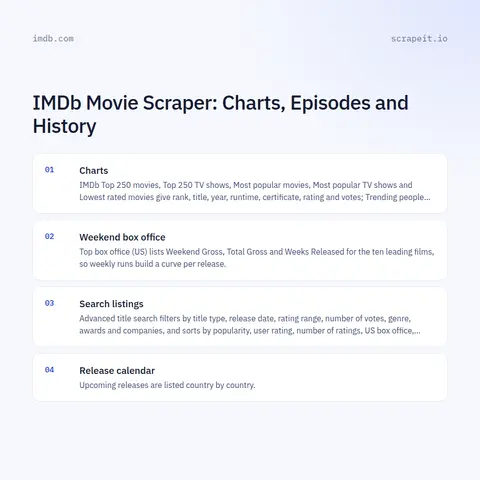
A title page is a snapshot. The picture comes from the lists around it and from reading them again.

  • ChartsIMDb Top 250 movies, Top 250 TV shows, Most popular movies, Most popular TV shows and Lowest rated movies give rank, title, year, runtime, certificate, rating and votes; Trending people ranks names instead of titles. Web scraping the IMDb Top 250 once gives a list; reading it every day gives the entries, the exits and each rank move.
  • Weekend box officeTop box office (US) lists Weekend Gross, Total Gross and Weeks Released for the ten leading films, so weekly runs build a curve per release.
  • Search listingsAdvanced title search filters by title type, release date, rating range, number of votes, genre, awards and companies, and sorts by popularity, user rating, number of ratings, US box office, runtime or release date. It is how we cut the database into complete slices.
  • Release calendarUpcoming releases are listed country by country.
  • HistoryRating, vote count and Popularity rank keep moving, fastest on new releases. Scheduled runs keyed on the tt id turn them into a time series that IMDb itself does not display.
  • ReviewsA visitor sees the review counts and a short set of featured reviews - headline, score, date and text; the rest of the archive opens only to signed-in members. We collect the featured set and leave reviewer nicknames out by default.

About IMDb and How Its Pages Are Organised

Source
imdb.com
Category
streaming services
Delivery
API, JSON feed, CSV, XLSX
Plans
From €169 a month
Get a quote

IMDb is an Amazon company that presents itself as the leading source of information on movies, TV shows and celebrities. Beside the public site it runs IMDbPro for industry professionals and Box Office Mojo, which is credited under its box office chart.

For a data buyer the structure matters more than the size. Everything hangs on two id families: tt for titles and nm for people. A title is not only a film - TV series, mini series, single episodes, shorts, video games, music videos and podcasts are titles too, each with its own tt id, and an episode points back to its series. Every title fans out into sub-pages with stable addresses: full credits, ratings, release info, company credits, awards, parents guide, trivia. One film is a dozen pages, not one.

IMDb also adapts the page to the visitor. A visitor in Poland finds The Shawshank Redemption headed Skazani na Shawshank with the original title underneath, the Polish certificate beside the year and the Polish release date under Details. A run has to be anchored to one country, or a single column ends up mixing several.

25Developers
500+Customers
1.5BPages extracted
15,000+Hours saved for our clients

IMDb scraping plans and pricing

Airplane

€199one-time

Setup fee included

100,000
One-time
Up to 5 days
7 days

Helicopter

€169/ mo

Setup fee €499

250,000
Monthly
Up to 5 days
14 days

Glasses

€229/ mo

Setup fee €499

1,000,000
Weekly
Up to 5 days
30 days

Microscope popular

€349/ mo

Setup fee €499

2,000,000
Daily
Same day
60 days

DNA

€549/ mo

Setup fee €799

3,000,000
3 times daily
Same day
90 days

Delivery: CSV, JSON or XLSX files, our API or a JSON feed. MCP server on request.

Full plan details

Why Scrape IMDb Ratings, Credits and Charts

Teams that ask how to scrape IMDb want different columns for different jobs.

  • Content acquisitionStreaming and broadcast buyers rank catalogues by rating, vote count and Popularity to see what an audience already values before bidding for it.
  • Metadata enrichmentA catalogue matched on tt id gains genres, runtime, certificates, Also known as titles and cast in one join.
  • Release trackingPopularity rank and votes around a premiere, next to Weekend Gross and Weeks Released, show how a title opens and how fast it fades.
  • Talent and company researchCredits by department connect people to titles and titles to production companies and distributors - the graph behind casting research and co-production mapping.
  • Recommendation modelsGenres, interest tags, the rating histogram and per-episode ratings across seasons are training features for recommenders and for research on audience taste.
  • LocalisationTitles and release dates by market show where a film has come out and under which name.

Can you scrape IMDb at catalogue scale? Yes: we split the catalogue into search slices by title type, year and genre and merge the results on the tt id.

About ScrapeIt

ScrapeIt is a managed web scraping agency: clients describe the data they need, we build and run the crawlers and deliver the dataset. Entertainment databases are their own kind of work - many small linked pages per title, values that depend on the visitor's country, and counters that drift every day.

The project assessment is free, a sample can be ordered before you commit, and field documentation comes with the delivery. Personal data is handled under GDPR, and we do not sell dossiers on people.

FAQ

Still unsure? Write to info@scrapeit.io

Do you offer an IMDb API for title and rating data?

Yes. The ScrapeIt IMDb API returns tt id, original title, year, IMDb rating, number of votes, genres and principal cast as JSON from an endpoint we host, refreshed on the schedule you set. The same rows also arrive as CSV or XLSX files, a JSON feed or a load into your database.

Is it legal to scrape IMDb?

Yes. Title pages, ratings, credits, charts and box office figures are open to any visitor without an account. We collect only publicly available data - everything a visitor can see on IMDb - and we collect it legally. Sections behind a sign-in, IMDbPro included, are not part of the dataset.

What does your IMDb reviews scraper return?

For each title: the user review count, the critic review count, the Metascore and the rating histogram, plus the featured reviews shown to visitors with headline, score, date and text. The full review archive opens only after sign-in, and we never sign in, so it is not included. Reviewer nicknames are personal data and are left out by default.

Can you track the IMDb Top 250 and the other charts over time?

Yes. We read the Top 250, the Most popular charts and Top box office on the schedule you set and store rank, rating and votes with the date of the run. The box office chart is published per weekend, so one run a week captures it; the other charts can be read daily. The result is a history of entries, exits and rank changes per tt id.

Do titles and release dates come in one language or per country?

Either. IMDb shows a localised title, certificate and release date according to the visitor's country, with the Original title beside it. We fix the country of each run, keep the original title in its own column, and can add the full Also known as and release date lists by market from the release info page.

How it works

  1. 1

    Make a request

    You share your needs, expectations, and desired timeframe. We'll suggest the best solution based on your request and budget.

  2. 2

    We configure the crawlers

    Our specialists configure the crawlers and extract a sample dataset for your review before proceeding with the full-scale extraction.

  3. 3

    Collect and deliver

    Once you approve the sample, we launch the project and start full data collection. We gather, filter, and structure the data for easy use, delivering it on time in your preferred format.

  4. 4

    Maintain and support

    Our team manages ongoing processes, monitors website changes, and supports all data extraction cycles. We can also help integrate data into your systems or create dashboards to simplify analysis.

Request a quote

Tell us which sites, which fields and how often. A couple of lines is enough to start.

  • We reply within 1 business day
  • A sample dataset before the full run
  • We sign an NDA on request
  • Delivery by API, JSON feed or files
Which sites, which fields, how often. A couple of lines is enough.

This form is protected by Google reCAPTCHA, which loads when you start filling it in; the Google Privacy Policy and Terms of Service apply. If you prefer not to use it, email us at info@scrapeit.io. Privacy & Cookie Policy

We reply within 1 business day. No obligation.

IMDb data from €169/month. Free project assessment, reply within 1 business day.