RTL+ Scraper for Video, Audio and Podcast Catalogs

A subscription that also sells music and audiobooks is not one catalogue. Four media types in one table means four sets of fields mostly empty.

Plans from €169 a month · Free project assessment · Reply within 1 business day

CSV · Excel · JSON · XML · FTP · SFTP · Amazon S3 · Google Cloud

rtlplus.com
RTL+ Scraper for Video, Audio and Podcast Catalogs
rtlplus.comwhat you get
Typical fields for streaming services
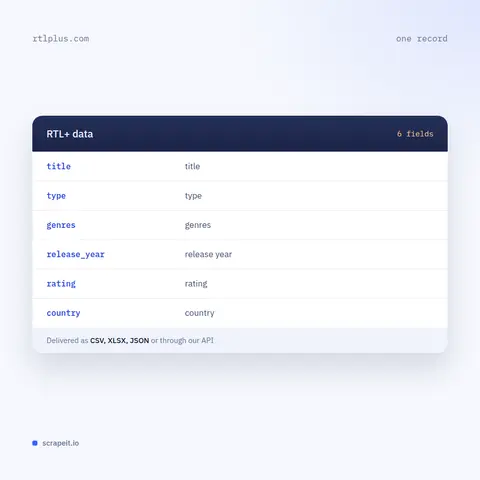
titletypegenresrelease_yearratingcountry
Delivery

API, JSON feed or CSV, XLSX and JSON files

Schedule

One-time, monthly, weekly, daily or 3 times a day

Managed German catalogue data, run end to end by us

  1. You send

    RTL+ pages, filters, fields and a schedule

  2. We run the scrapers

    Built, monitored and repaired by our team

  3. You receive the data

    API, JSON feed or CSV, XLSX and JSON files

ScrapeIt runs the collection as a managed service. You name the media types, sections or the full catalogue; we build a schema per media type, carry offer tier on every row, separate catch-up from the permanent library, and hand back CSV, JSON, Excel or a push into your warehouse.

Where bundle changes or catalogue turnover matter we run repeat collection and keep every observation, since a tier change leaves no record of itself.

We collect published metadata only - never streams, never anything behind a sign in, no viewer or listener data - and pace requests. That is publicly available data only - everything a visitor can see on RTL+ - and we collect it legally.

RTL+ fields in every export

Media type is the first field on every row and it determines which of the others are populated, because pretending otherwise produces a schema nobody can query.

Video records carry the title, original title, content type, genre, release year, duration, maturity rating, synopsis, series and episode identifiers, originating channel and any availability window.

Audio records are typed to their kind: tracks with artist, album and duration; audiobooks with author, narrator, publisher and total running time; podcast episodes with show, episode number and publication date.

Offer type is carried where the service distinguishes free, included and premium tiers, since the bundle has several levels and a title's tier is part of what it is.

Every row carries the collection timestamp and the section it came from, so a figure can be traced back and a media type can be audited rather than trusted.

RTL+ fields in every export
Bundle structure, local production and limits

Bundle structure, local production and limits

Bundle structure analysis is the distinctive output: how much of each media type sits in each tier, and how that has changed. For anyone studying how broadcasters compete against pure play subscription services, the shape of the bundle is the strategy, and it is visible in the catalogue.

Local production share by genre answers how much is German commissioning versus imported, which matters for quota research and for anyone tracking European content investment.

Catch-up turnover, kept separate from the permanent library, shows what goes on demand after transmission and for how long.

Cross service comparison usually follows, and it is where the media typing pays off: the video catalogue compares against video services, the audiobook catalogue against audiobook services, and neither comparison is possible from a merged table.

Limits are as everywhere here. Metadata only, never content or streams, nothing behind a sign in, no listener or viewer data.

One subscription, four kinds of catalogue

Source
rtlplus.com
Category
streaming services
Delivery
API, JSON feed, CSV, XLSX
Plans
From €169 a month
Get a quote

RTL+ is the streaming service of RTL Deutschland, the country's largest commercial broadcaster. It began as video on demand and became a bundle: series and films, live channels, music, audiobooks and podcasts under a single subscription.

For a data project that bundling is the defining fact. A series episode, a music track, an audiobook and a podcast episode have different identifying fields, different duration semantics and different rights. A track has an artist and an album; an audiobook has an author, a narrator and a publisher; a podcast episode has a show, a number and a publication date; an episode has a series and a season. One table for all four is mostly empty cells.

The video catalogue itself carries the familiar broadcaster mix: originals, licensed material and catch-up from the RTL channels, with the catch-up portion carrying availability windows while the rest does not.

Catalogue sections respond directly with substantial content - titles, genres, release years, durations, maturity ratings and synopses, and on the audio side artists, authors, narrators and shows - all visible to any visitor.

25Developers
500+Customers
1.5BPages extracted
15,000+Hours saved for our clients

RTL+ scraping plans and pricing

Airplane

€199one-time

Setup fee included

100,000
One-time
Up to 5 days
7 days

Helicopter

€169/ mo

Setup fee €499

250,000
Monthly
Up to 5 days
14 days

Glasses

€229/ mo

Setup fee €499

1,000,000
Weekly
Up to 5 days
30 days

Microscope popular

€349/ mo

Setup fee €499

2,000,000
Daily
Same day
60 days

DNA

€549/ mo

Setup fee €799

3,000,000
3 times daily
Same day
90 days

Delivery: CSV, JSON or XLSX files, our API or a JSON feed. MCP server on request.

Full plan details

Why a bundle has to be unbundled in the data

The instinct is to treat this as a video service that happens to include extras, and it produces a dataset that is wrong about the majority of what the service sells.

The audio side is not an accessory. Audiobooks and podcasts are a substantial part of the offering, with their own catalogue, their own rights and their own competitive set, and they are compared against audiobook services rather than against streaming video. A dataset that flattens them into a video schema cannot support that comparison at all.

The second reason is that duration means different things. Two hours of film, two hours of audiobook and two hours of podcast are not comparable quantities, and an aggregate that sums them is arithmetic without meaning.

The third is the catch-up layer, familiar from any broadcaster service: part of the video catalogue is temporary and part is permanent, and counting them together hides the turnover.

The fourth is that this is the largest commercial broadcaster in a big European market, which makes it one of the better single windows onto German commercial content - local production, genre mix and how a broadcaster structures a bundle against subscription competitors.

Who builds and keeps your RTL+ feed

ScrapeIt is a managed extraction company, not a tool you have to learn. Our team builds the pipeline, watches it as the bundle gains and loses media types, and repairs it before a tier record develops a gap.

You see a sample first, in your format, over the media types you actually track, typed separately so you can judge on real titles whether the structure fits what you plan to ask.

FAQ

Still unsure? Write to info@scrapeit.io

Can I just have the video catalogue?

Yes, and it is a common scope. We will still type it properly and tell you what the audio side contains, because a comparison against subscription competitors usually turns out to need the bundle shape rather than just the video list.

Why type audiobooks and podcasts separately?

Because their identifying fields differ - author, narrator and publisher for one, show, episode number and publication date for the other - and because they compete against audiobook and podcast services rather than against streaming video. A video schema cannot support that comparison.

Can you total the catalogue by hours?

Per media type, yes. Across them, we would rather not: two hours of film, audiobook and podcast are not comparable quantities and the sum is arithmetic without meaning. We deliver the components so you can aggregate deliberately.

Does the catch-up material expire?

Part of the video catalogue does, and we record its window where published while keeping it separate from the permanent library. Counted together they inflate catalogue size and hide the turnover.

Do you collect anything about subscribers?

No. Metadata only, nothing behind a sign in, no viewer or listener data of any kind. The catalogue analysis these projects need contains none of it.

How it works

  1. 1

    Make a request

    You share your needs, expectations, and desired timeframe. We'll suggest the best solution based on your request and budget.

  2. 2

    We configure the crawlers

    Our specialists configure the crawlers and extract a sample dataset for your review before proceeding with the full-scale extraction.

  3. 3

    Collect and deliver

    Once you approve the sample, we launch the project and start full data collection. We gather, filter, and structure the data for easy use, delivering it on time in your preferred format.

  4. 4

    Maintain and support

    Our team manages ongoing processes, monitors website changes, and supports all data extraction cycles. We can also help integrate data into your systems or create dashboards to simplify analysis.

Request a quote

Tell us which sites, which fields and how often. A couple of lines is enough to start.

  • We reply within 1 business day
  • A sample dataset before the full run
  • We sign an NDA on request
  • Delivery by API, JSON feed or files
Which sites, which fields, how often. A couple of lines is enough.

This form is protected by Google reCAPTCHA, which loads when you start filling it in. If you prefer not to use it, email us at info@scrapeit.io. Privacy & Cookie Policy

We reply within 1 business day. No obligation.

RTL+ data from €169/month. Free project assessment, reply within 1 business day.