RTVE Play Scraper for Spanish Broadcast Archive Data

Most streaming archives go back a few years. A public broadcaster's goes back decades, and that depth is the only thing a commercial service cannot buy.

Plans from €169 a month · Free project assessment · Reply within 1 business day

CSV · Excel · JSON · XML · FTP · SFTP · Amazon S3 · Google Cloud

rtve.es
RTVE Play Scraper for Spanish Broadcast Archive Data
rtve.eswhat you get
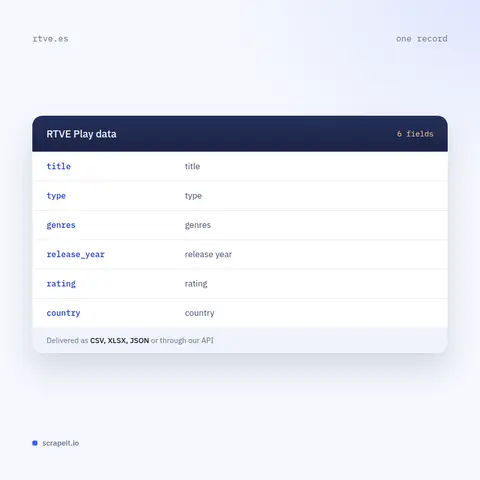
Typical fields for streaming services
titletypegenresrelease_yearratingcountry
Delivery

API, JSON feed or CSV, XLSX and JSON files

Schedule

One-time, monthly, weekly, daily or 3 times a day

Managed archive metadata, run end to end by us

  1. You send

    RTVE Play pages, filters, fields and a schedule

  2. We run the scrapers

    Built, monitored and repaired by our team

  3. You receive the data

    API, JSON feed or CSV, XLSX and JSON files

ScrapeIt runs the collection as a managed service. You name the periods, genres or programme types; we build the pipeline with broadcast date precision recorded, content types separated and sparse older entries kept rather than filtered, and hand back CSV, JSON, Excel or a push into your warehouse.

Where availability drift matters we run repeat collection and keep every observation, because material that became unavailable leaves no note saying so.

We collect published metadata only - never streams, never anything behind a sign in - and pace requests. Only publicly available data goes into the dataset - everything a visitor can see on RTVE Play - and we collect it legally.

RTVE Play fields in every export

Programme records carry the title, content type, genre, description, original broadcast date where published, duration, season and episode structure, channel and language.

Original broadcast date is the field that makes the archive usable. A catalogue entry without it is a title floating free of the period it belongs to, and for archive research the period is the question. Where the site publishes both a broadcast date and a publication date we keep them apart.

Content type distinguishes series, news, documentary and radio material, because they have different structures and mixing them produces aggregates that describe none of them.

Language is recorded where published, since Spain has co-official languages and the broadcaster produces in more than one.

Every row carries the collection timestamp and the source address.

RTVE Play fields in every export
Archive research, availability drift and structure

Archive research, availability drift and structure

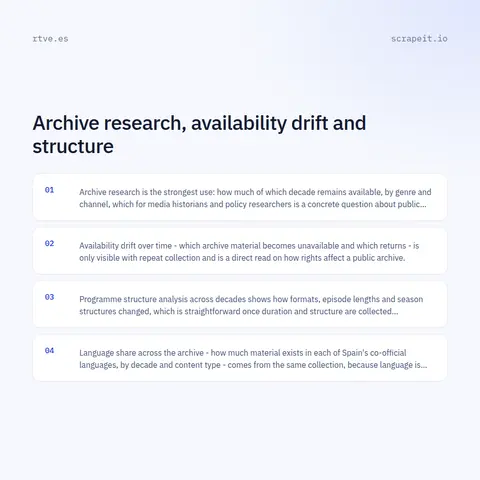
Archive research is the strongest use: how much of which decade remains available, by genre and channel, which for media historians and policy researchers is a concrete question about public memory that this catalogue can answer.

Availability drift over time - which archive material becomes unavailable and which returns - is only visible with repeat collection and is a direct read on how rights affect a public archive.

Programme structure analysis across decades shows how formats, episode lengths and season structures changed, which is straightforward once duration and structure are collected consistently.

Language share across the archive - how much material exists in each of Spain's co-official languages, by decade and content type - comes from the same collection, because language is recorded where published.

A public archive that happens to stream

Source
rtve.es
Category
streaming services
Delivery
API, JSON feed, CSV, XLSX
Plans
From €169 a month
Get a quote

RTVE Play is the on demand service of Spain's public broadcaster, carrying current programming, news, documentaries, drama and a substantial archive of past broadcast material.

The archive is what distinguishes it. Commercial services carry what they licensed recently; a public broadcaster carries what it made, and in this case that runs back decades. For research into Spanish media, television history or public service broadcasting, that depth is the asset and there is no commercial substitute for it.

The catalogue also spans several content types that behave differently: series with episode structure, news programmes tied to dates, documentaries, and radio material from the same organisation.

Catalogue sections respond directly with substantial content. Programme pages show any visitor the title, content type, genre, description, duration and channel, the season and episode structure, and the original broadcast date where published.

25Developers
500+Customers
1.5BPages extracted
15,000+Hours saved for our clients

RTVE Play scraping plans and pricing

Airplane

€199one-time

Setup fee included

100,000
One-time
Up to 5 days
7 days

Helicopter

€169/ mo

Setup fee €499

250,000
Monthly
Up to 5 days
14 days

Glasses

€229/ mo

Setup fee €499

1,000,000
Weekly
Up to 5 days
30 days

Microscope popular

€349/ mo

Setup fee €499

2,000,000
Daily
Same day
60 days

DNA

€549/ mo

Setup fee €799

3,000,000
3 times daily
Same day
90 days

Delivery: CSV, JSON or XLSX files, our API or a JSON feed. MCP server on request.

Full plan details

Why archive depth needs different handling

A pipeline built for a commercial streaming catalogue will work here and will waste most of what the source offers.

Commercial catalogue logic assumes a few thousand recent titles with consistent metadata. An archive spanning decades has inconsistent metadata by nature: older material was catalogued under different conventions, broadcast dates are recorded with varying precision, and some entries carry rich description while others carry a title and a year. Treating that unevenness as dirty data and cleaning it away destroys the information that the entry is old.

The better approach is to record precision explicitly - an exact broadcast date and a year-only date are different facts and should be distinguishable - and to keep the sparse entries rather than filtering them out for failing a completeness check.

The second reason is that archive material changes availability. Rights on older programming lapse and return, so what is streamable this year may not be next, and repeat collection turns that into a record of what a public broadcaster can actually keep available.

The third is that this is one national broadcaster. It is excellent for Spain and says nothing about the wider Spanish-language world, where the production centres are elsewhere.

Who builds and keeps your archive feed

ScrapeIt is a managed extraction company, not a tool you have to learn. Our team builds the pipeline, handles the metadata unevenness that decades of cataloguing conventions produce, and repairs the collector before an availability record develops a gap.

You see a sample first, in your format, over the periods you actually research, with date precision recorded so you can see on real entries what a cleaned-up pipeline would have thrown away.

FAQ

Still unsure? Write to info@scrapeit.io

Why keep entries with sparse metadata?

Because sparseness is information: older material was catalogued under different conventions, and an entry with only a title and a year is telling you it is old. Filtering it for failing a completeness check removes exactly the part of the archive that research is about.

How do you handle imprecise broadcast dates?

By recording the precision explicitly. An exact date and a year-only date are different facts, and a dataset that stores both as a date silently invents precision that was never there.

Does the archive stay available?

Not entirely. Rights on older programming lapse and return, so availability drifts. Repeat collection turns that into a record of what a public broadcaster can actually keep accessible, which is itself a research finding.

Does this cover Spanish-language media generally?

No. It is one national broadcaster and it is excellent for Spain. The wider Spanish-language production world sits elsewhere, and we scope briefs on that basis rather than letting one archive stand in for a language.

Is it legal to scrape RTVE Play?

Yes. Programme titles, content types, genres, descriptions, original broadcast dates and durations are shown to any visitor on RTVE Play, and those are the fields we collect. We collect only publicly available data - everything a visitor can see on RTVE Play - and we collect it legally.

How it works

  1. 1

    Make a request

    You share your needs, expectations, and desired timeframe. We'll suggest the best solution based on your request and budget.

  2. 2

    We configure the crawlers

    Our specialists configure the crawlers and extract a sample dataset for your review before proceeding with the full-scale extraction.

  3. 3

    Collect and deliver

    Once you approve the sample, we launch the project and start full data collection. We gather, filter, and structure the data for easy use, delivering it on time in your preferred format.

  4. 4

    Maintain and support

    Our team manages ongoing processes, monitors website changes, and supports all data extraction cycles. We can also help integrate data into your systems or create dashboards to simplify analysis.

Request a quote

Tell us which sites, which fields and how often. A couple of lines is enough to start.

  • We reply within 1 business day
  • A sample dataset before the full run
  • We sign an NDA on request
  • Delivery by API, JSON feed or files
Which sites, which fields, how often. A couple of lines is enough.

This form is protected by Google reCAPTCHA, which loads when you start filling it in. If you prefer not to use it, email us at info@scrapeit.io. Privacy & Cookie Policy

We reply within 1 business day. No obligation.

RTVE Play data from €169/month. Free project assessment, reply within 1 business day.