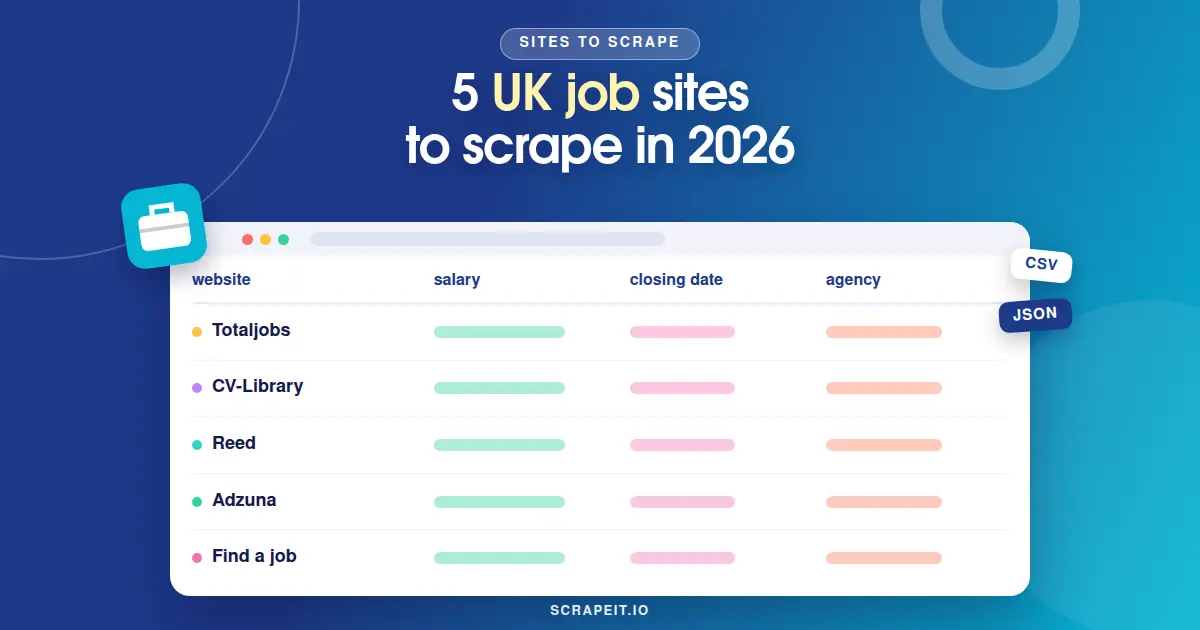
UK job sites look alike to a jobseeker: a title, a town, a salary line. To a data buyer they are five different datasets: three commercial boards with their own identifiers and badges, a search engine that gathers ads from other sites and adds its own salary estimates, and the government's free vacancy service with a slice of its own.
Below: what each site shows, what only it adds and what it is best for; the fields that need a decision before the first run; how to merge boards without counting a vacancy twice; and what our projects taught us. For other countries, see all job boards we scrape and our job data scraping service.
Who this list of UK job boards is for
It is for teams that buy job ads as data: labour-market analysts, HR tech products and aggregators, staffing firms prospecting employers, pay benchmarking teams and investors who read hiring as a company signal. Few briefs need all five sites: start with one commercial board, add Find a job for public sector work and apprenticeships, and Adzuna for vacancy counts per town.
UK salary data and the other fields that need a decision first
All five sites publish in English and price in pounds sterling; Find a job also switches to Cymraeg. Five fields need a rule before the first load:
- Salary as printed. Per annum, per day or per hour; a range, a from figure, a pro rata amount beside a full-time equivalent, a pay-scale grade or a word such as Negotiable. Keep the line and add minimum, maximum and period, so a day rate never enters an annual average.
- Advertiser type. When a recruitment agency places the ad, the advertiser is not the employer. To separate agency ads from direct employers, keep each commercial board's own split: the Direct Employer or Agency label on Totaljobs, the separate employer and agency lists of CV-Library's directory, and Reed's Posted by filter.
- Location. A postcode area in brackets, a postcode district, a full postcode or a distance in miles from the searched place. Plan geography on the postcode district.
- Dates. Ages such as Posted yesterday become dates only if the collection time is stored. Find a job prints a closing date, and Adzuna the date an ad runs until.
- Identifiers. Every site numbers its own ads. The advertiser's own reference, a field on CV-Library and sometimes typed into a Find a job summary, is the closest thing to a shared key.
5 UK job sites worth scraping, site by site
The order follows how much of a typical UK brief a site answers on its own: commercial boards first, then the aggregator, then the public service. It is not a ranking of the sites' quality.
1. Totaljobs: pay lines and a salary panel per search
Totaljobs, operated by The Stepstone Group UK Limited, covers every sector, from warehouse shifts paid by the hour to day-rate contracts in the City. An ad address ends in a nine-digit job id and the company link carries its own cmpId, so ads and advertisers join cleanly. A row holds the title, the NEW, FEATURED or PREMIUM card label, the advertiser with its sector and live job count, its Direct Employer or Agency type, the town with the postcode area in brackets, as in East London (E1), contract type and work model, the Published age turned into a date, and the salary line as typed. What sets Totaljobs apart is the panel at the foot of a title-and-place search: the average salary per year for that role in that town with its range, the number of matching jobs and how many of them are temporary or part-time. Best for: pay benchmarking, agency share by sector, contractor day rates. See the Totaljobs scraper page.
2. CV-Library: two identifiers on every ad
CV-Library is an independent UK job board that describes itself as the largest independent job site. Its distinctive field is the details box at the foot of each ad, which prints CV-Library's Job ID beside the advertiser's own Job Reference: with both, an edited ad or a repost of the same vacancy can be traced. The Posted by line names whoever placed the ad, on agency ads the agency, and the Employer A-Z lists direct employers and recruitment agencies apart, each company page with its live job count, business address and website - an advertiser table ready to join. Locations come as a postcode district and area, such as SW2, Ferndale. A vacancy posted in several towns shows one card marked Also in other locations, with a copy and Job ID for each town behind it. Rows also carry the salary band with its period, Contract Length, and Easy Apply and Featured badges. Best for: deduplicated ingestion and advertiser tables. See the CV-Library scraper page.
3. Reed: skills, badges and training courses among the jobs
Reed.co.uk was the first recruitment website launched by a UK recruitment agency. A result card reads like a record: the posted date and advertiser in one line, the salary per annum or per day, the town, the contract type with hours, as in Contract, full-time, and the work model. Badges mark ads as Promoted, Featured, New, Easy Apply or Ending soon, and the ad page adds a breadcrumb from sector to job title and a list of skills. Results filter by whether an agency or an employer posted the ad, and can hide jobs without salary displayed. One detail matters for counts: Reed places training course ads among the jobs, with Training Course where the salary would be, so they are flagged before vacancies are counted. Reed Courses, its training marketplace, can be collected as a dataset of its own. Best for: skills demand per title and how employers position vacancies. See the Reed scraper page.
4. Adzuna: aggregated ads and Jobsworth estimates
Adzuna is a job search engine rather than a job board: it gathers ads from employers, agencies and other job sites into one index. Each ad has a numeric ad id and carries the title, category, contract type and hours, the company, a location down to postcode and coordinates, and badges such as NEW, CLOSING SOON and REMOTE. Where the employer printed a salary, Adzuna shows it; where not, it shows its own Jobsworth estimate, which belongs in a separate column flagged as an estimate. Some ads carry the logo of the job site they arrived from. Search pages are data in their own right: a headline count, an average salary for the query and vacancy counts on every filter, by district, category and employer. Because ads arrive from elsewhere, an Adzuna row may repeat an ad you hold from its original board, and one agency ad can sit twice in a single search under two ids. Best for: vacancy counts by town and sector, salary gaps filled with labelled estimates. See the Adzuna scraper page.
5. Find a job: the DWP service, with closing dates
Find a job is the vacancy service of the Department for Work and Pensions (DWP) for England, Scotland and Wales, and employers post on it free of charge. NHS trusts, academy trusts, charities and staffing agencies advertise beside private firms, such as training providers, insurers and facilities companies. Each ad is a labelled list: the Company line, naming the hiring organisation or the staffing agency advertising for it, the Disability Confident badge, a Salary line from hourly rates to pro rata amounts and NJC pay-scale grades, Hours, Job type with Apprenticeship as a type of its own, Working pattern, Posting date and Closing date. The service moved into Work Hub on jobs.service.gov.uk, and job ids changed from short numbers to long hexadecimal strings, so lists built on the old site do not join the new one on the id. And a default search leaves the Remote box unticked, so remote vacancies have to be asked for. Best for: local labour market reports and public sector pay bands. See the Find a job scraper page.
Get Data for your Business
We extract the data you need from any website to satisfy all your business requirements with 100% accuracy.
- Free Sample Data Sets
- Regular Data Delivery
- Legal and GDPR compliance
Get a Quote
How to scrape UK job boards into one dataset
One vacancy can sit on several of these sites, and inside one site it can appear as several ads: an agency relisting a role with identical title, postcode and pay, a CV-Library vacancy with a copy per town, a Find a job ad back under a new job id. Count rows and demand is overstated. Three rules:
- One schema, source kept. Source, the site's job id, the advertiser's reference, title, advertiser and its type, location as printed with postcode district, salary text with minimum, maximum and period, printed or estimated pay, contract type, hours, posting and closing dates, first seen and last seen.
- Match, do not delete. To remove duplicate job ads across boards, rows are matched on advertiser, title, postcode district and pay, plus the advertiser's reference where both rows carry it. Matched rows share a vacancy key and every source row stays, so you can count ads or distinct vacancies.
- Keep the grains apart. Training course ads, salary estimates and search-page counts never enter the same total as posted vacancies.
What our projects taught us about employer and listing data
Neither project was about a job board, but the problems carry over.
One employer, many searches
A US property-technology startup wanted a copy of a public employer directory readable only through a search form with a captcha on every new query. The search matched three letters at the start of any word in a name, so one employer turned up under many queries: 1,376,889 rows came down to 988,996 unique employers once rows with the same name and employer ID were merged. So the client could check any record, we also delivered the full set before duplicate removal, with the search and page behind each row. Keyword and town searches on a job board overlap the same way, so we merge on the site's job id. Case: 988,996 employer records behind a captcha.
A board's own labels as a business signal
An investment firm watched Hemnet, the Swedish property portal, as a business: every listing goes out with a paid package, Bas, Plus or Premium, and the share of new listings on the dearer packages is a read on what the portal earns. Twice a month it received every new listing with its package, region, asking price and publication date; it also ordered samples of job-opening data from the careers pages of two companies. The NEW, FEATURED and PREMIUM labels on Totaljobs and the Featured badges on CV-Library and Reed can be counted the same way. When the client removed repeated addresses, the files shrank by 20-30%, so we added a check that keeps one row per listing before export. Case: Hemnet listing package mix for an investment firm.
How ScrapeIt collects UK job data
ScrapeIt is a managed service: we build, run and repair the crawlers. You name the sites, the scope, the fields and the refresh interval; anti-bot handling - pacing, proxy rotation, CAPTCHA handling and rendering - is part of the service. Indeed runs a UK site as well, covered on our Indeed scraper page.
A project starts with a free project assessment, and a sample can be ordered before the full run. Field documentation comes with the dataset; runs are one-off or on the schedule you set. Plans start from EUR 169 a month, or EUR 199 for a one-time extract. Formats are CSV, Excel (XLSX), JSON, JSONLines and XML, delivered through our API (an endpoint we host), a JSON feed, FTP, SFTP, Amazon S3, Google Cloud Storage, Dropbox, Google Drive, e-mail or a load into your database; an MCP server is available on request. See all UK sites we scrape and, for homes, the UK property websites to scrape in 2026.
FAQ
What are the best UK job sites to scrape?
For direct postings with salary lines and advertiser types, start with Totaljobs, CV-Library and Reed. Add Adzuna for vacancy counts and salary statistics by town, and Find a job for public sector and apprenticeship vacancies with closing dates.
Is it legal to scrape UK job sites?
We collect only publicly available data - everything a visitor can see on the site - and we collect it legally. Recruiters' names, phone numbers and e-mail addresses inside ads are personal data: we handle personal data under GDPR and leave such fields out by default.
Can I get UK job data through an API?
Yes, through ours. An endpoint we host returns the collected ads as JSON, with parsed salary figures beside the printed line, refreshed on the schedule you set.
How often should UK job data be refreshed?
Daily when the value is in new ads and closing dates: fresh ads show as posted today or yesterday, and a weekly run misses short-lived vacancies. Weekly is enough for salary panels, employer tables and trend counts.
Do you collect candidate CVs or recruiter contacts?
No candidate data: CV databases and candidate profiles are never part of a project. Recruiters' contact details are left out by default and delivered only when a project needs them and the ad shows them openly.