CV-Library Scraper for UK Job Ads and Advertiser Data

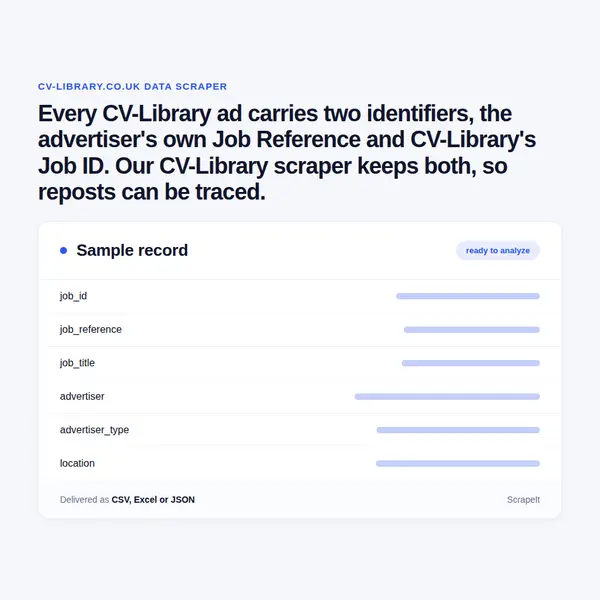
Every CV-Library ad carries two identifiers, the advertiser's own Job Reference and CV-Library's Job ID. Our CV-Library scraper keeps both, so reposts can be traced.

Plans from €169/month · Free project assessment · Reply within 1 business day

CV-Library Scraper
Solutions

CV-Library scraping as a done-for-you service

Tell us which part of CV-Library you need - an industry such as IT or Warehouse, towns with a radius in miles, a list of employers or agencies, or every live ad - and the cadence. We write the crawler, run it and fix it when CV-Library redesigns its two-pane results view. Rendering, proxy rotation, pacing and CAPTCHA handling come with the service.

You receive one row per ad with CV-Library's own labels intact and parsed columns beside them: the salary band split into figures and period, Posted yesterday turned into a date, the distance stripped from the location. Field documentation ships with the first file, and a sample can be ordered before any plan.

What the CV-Library data scraper extracts

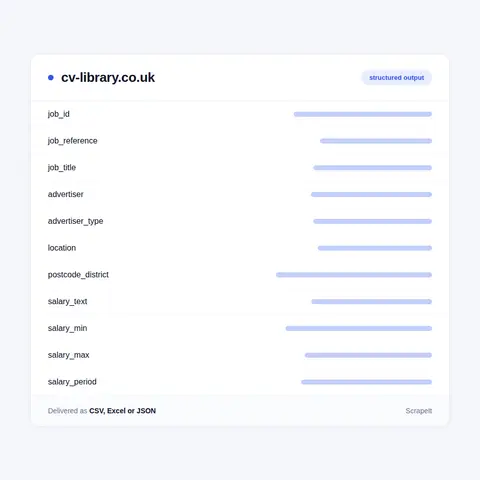
A CV-Library ad address is /job/ plus the Job ID and a slug, and the details box at the foot of the ad repeats that ID beside the advertiser's Job Reference. The fields below come from the result card, the ad page and that box:

  • Identifiers - Job ID, Job Reference, ad URL and title. The ID is CV-Library's, the reference is the advertiser's own code, and keeping both makes edits and reposts traceable.
  • Advertiser - the company in the Posted by line, its company page, and whether the directory lists it among direct employers or recruitment agencies.
  • Location - postcode district and area such as SW2, Ferndale, the distance in miles from the searched place, and the Also in other locations marker on ads posted in several towns.
  • Salary - the band as printed with its period, per annum, per day or per hour, parsed into minimum, maximum and unit.
  • Job type and length - Permanent, Contract, Temporary or Part Time, and the Contract Length field of the details box.
  • Dates - the posted time, from just now and yesterday to a calendar date on older ads.
  • Badges - Easy Apply on ads with a quick application, and Featured on ads placed at the top of a results page.
  • Category - the breadcrumb path from industry to sub-sector to country and town, for example IT, Data Analysis, England, London.
  • Description - the full ad text, and the snippet company pages show under each ad.

The details box also lists a contact name and telephone that CV-Library shows only after login or registration. Those belong to individual recruiters, so they stay out of the dataset by default.

What the CV-Library data scraper extracts
CV-Library dataset: searches, employer pages and history

CV-Library dataset: searches, employer pages and history

CV-Library builds search pages from a keyword and a place - data analyst jobs in London, warehouse jobs in Manchester - and lets a visitor set a radius from one mile to several hundred, a posted-within window, salary bands by year, day or hour, job type, industry and a remote-only switch. Results sort by relevance, most recent, salary either way or distance, with a choice of page sizes. We slice large categories by industry, region and posting window and merge on Job ID.

The Employer A-Z is a business directory split into employers and recruitment agencies, browsable by letter, industry and county. Each company page shows its count of live jobs, a business address, a website and an About us section, followed by the current ads - an advertiser table ready to join.

Run on a schedule, the same scope becomes a time series: new ads per day, how long ads stay live, which agencies repost, how salary bands move for one title. Search pages also carry an FAQ block on pay and skills for the title and town, which can be captured alongside.

About CV-Library

CV-Library is an independent UK job board led by its founder and CEO, Lee Biggins. It describes itself as one of the UK's first job boards and as the largest independent job site, and its listings cover every industry from cleaning and warehouse work to IT, engineering and the NHS.

Advertisers are a mix of direct employers and recruitment agencies, and the site keeps the two apart: its directory has separate searches for each, and a direct employer's company page says so in its breadcrumb. In the results, the Posted by line names whoever placed the ad, which on agency ads is the agency rather than the hiring company.

CV-Library also owns a network of specialist sector and location job sites that send candidates to the ads on its main board. We collect from cv-library.co.uk, where every ad has its full page and details box. The jobseeker side adds a salary guide, a salary tax calculator and career advice, and a search box that accepts a job reference as well as a keyword.

Despite the name, the dataset is the job side only. The CV database that recruiters pay to search is candidate data and is never part of what we collect or deliver.

Get a Quote
dev_w
25

Developers

customers
500+

Customers worldwide

pages
1 500 000 000+

Pages extracted

stime
15000+

Hours saved for our clients

Plans

CV-Library Scraping Plans and Pricing

Airplane

€199 / one-time

setup fee - included

Data limits100,000
Frequencyone-time
Run timeup to 5 days
Data storing7 days

Helicopter

€169 / mo

setup fee €499

Data limits250,000
Frequencymonthly
Run timeup to 5 days
Data storing14 days

Glasses

€229 / mo

setup fee €499

Data limits1,000,000
Frequencyweekly
Run timeup to 5 days
Data storing30 days

DNA

€549 / mo

setup fee €799

Data limits3,000,000
Frequency3 times daily
Run timesame day
Data storing90 days

Delivery: CSV, JSON or XLSX files, our API or a JSON feed. MCP server on request.

Full plan details →

Why scrape CV-Library

When clients scrape CV-Library salaries, the period matters as much as the figure: a band can be per annum, per day or per hour, and CV-Library's own filter offers bands for each. Read that way, the board supports several kinds of analysis.

  • Salary benchmarking - bands by title, town and job type, compared with the salary guide or your own pay data.
  • Agency activity - which recruitment agencies post in which industries and counties, and how many live jobs each holds.
  • Local demand - postcode districts and distances count ads within reach of a site you plan to open or a town where you hire.
  • Contract and temporary work - day and hourly rates on Contract and Temporary ads, tracked weekly per industry.
  • Application friction - the share of Easy Apply ads per industry shows where applying is quick.
  • Deduplicated ingestion - Job ID and Job Reference together let a job aggregator or an HR analytics product take CV-Library ads without double counting.

Our Blog

Reads Our Latest News & Blog

Learn how to use web scraping to solve data problems for your organization

How Artificial Intelligence Is Used In Web Scraping

How Artificial Intelligence Is Used In Web Scraping

Leveraging advances in technology, the AI-powered web scraper has skyrocketed in demand and is helping to expand capabilities by automating tedious daily tasks and speeding up data collection from thousands of websites several times over.

What is Web Scraping and What is it Used For?

What is Web Scraping and What is it Used For?

Web scraping is a method of obtaining web data by extracting it from pages of web resources with the help of a program, that is, in automatic mode. It is used to syntactically convert web pages into more usable forms.

Web Scraping for Machine Learning

Web Scraping for Machine Learning

If you specialize in machine learning, you need to feed large amounts of data to the algorithms. Web scraping is the easiest and the most efficient method of collecting the data from all over the Internet.

scrapeit logo

About ScrapeIt

ScrapeIt is a managed scraping service: our team builds the crawlers, keeps them running and answers for the data they return. For a UK board like CV-Library that means salary bands in three periods, repeated ads from agencies and locations given as postcode districts. We deliver Excel, CSV, JSONLines or a load into your database, daily or weekly, with recruiters' names left out and anything personal handled under GDPR. An MCP server is available on request.

FAQ

Do you provide a CV-Library API for vacancies and salary bands?

Yes. The ScrapeIt CV-Library API returns Job ID, Job Reference, title, advertiser, salary band and job type for each ad as JSON from an endpoint we host, refreshed on the schedule you set. Prefer files? The same rows come as Excel or CSV by e-mail, SFTP or Google Drive, or as a JSON feed.

Is it legal to scrape CV-Library?

Yes. Result cards, ad pages with their details box, company pages and the Employer A-Z are open to any visitor. We collect only publicly available data - everything a visitor can see on CV-Library - and we collect it legally. Contact names and phone numbers that appear only after login stay out.

Do you collect candidate CVs from CV-Library?

No. We collect job ads and advertiser pages only. The CV database is candidate data that recruiters buy access to, and it is never part of a ScrapeIt project, whatever the brand name suggests.

How do you scrape CV-Library ads posted in several locations?

When an advertiser posts one vacancy in many towns, the results show one card marked Also in other locations, and behind it every town has its own copy with its own Job ID. We keep each copy as a row and add a group key from title, advertiser and salary band, so the vacancy can be counted once or per town.

How often should a CV-Library feed refresh?

Cards say Posted just now, today or yesterday on fresh ads, and the posted filter starts at the last 24 hours, so a daily run catches new ads on the day they appear. Ads leave the board when filled or expired, which a daily run also records; weekly is enough for salary studies.

How does it Work?

Step 1 - Make a Request

You share your needs, expectations, and desired timeframe. We’ll suggest the best solution based on your request and budget.

Step 2 - Configuring Custom Web Crawlers

Our specialists configure the crawlers and extract a sample dataset for your review before proceeding with the full-scale extraction.

Step 3 - Collect and Deliver

Once you approve the sample, we launch the project and start full data collection. We gather, filter, and structure the data for easy use, delivering it on time in your preferred format.

Step 4 - Maintain and Support

Our team manages ongoing processes, monitors website changes, and supports all data extraction cycles. We can also help integrate data into your systems or create dashboards to simplify analysis.

Request a Quote

Tell us more about you and your project information.
Which sites, which fields, how often. A couple of lines is enough.

This form is protected by Google reCAPTCHA, which loads when you start filling it in. If you prefer not to use it, email us at info@scrapeit.io. Privacy & Cookie Policy

We reply within 1 business day. No obligation.

CV-Library data from €169/month. Free project assessment, reply within 1 business day.

scrapiet

Scrapeit Sp. z o.o.
10/208 Legionowa str., 15-099, Bialystok, Poland
NIP: 5423457175
REGON: 523384582