Greenhouse Scraper for Employer Job Boards

Each Greenhouse board belongs to one employer and lives at its own address. Our Greenhouse scraper joins many of them into one table of open roles, departments and pay.

Plans from €169 a month · Free project assessment · Reply within 1 business day

CSV · Excel · JSON · XML · FTP · SFTP · Amazon S3 · Google Cloud

job-boards.greenhouse.io
Greenhouse Scraper for Employer Job Boards
job-boards.greenhouse.iowhat you get
Typical fields for job boards
job_titlecompanylocationsalaryemployment_typeposted_at
Delivery

API, JSON feed or CSV, XLSX and JSON files

Schedule

One-time, monthly, weekly, daily or 3 times a day

Greenhouse Job Scraping as a Managed Service

  1. You send

    Greenhouse pages, filters, fields and a schedule

  2. We run the scrapers

    Built, monitored and repaired by our team

  3. You receive the data

    API, JSON feed or CSV, XLSX and JSON files

You send the employers you care about - company names, career site links or Greenhouse board addresses - and we locate each board, whether it sits on job-boards.greenhouse.io, on an older boards.greenhouse.io link, on job-boards.eu.greenhouse.io or inside the company's own career site. We build the crawlers, run them once or on your schedule and repair them when a board changes its layout or moves. Anti-bot handling, pacing and rendering are part of the service.

Every row keeps the board token and the numeric job id, so a role stays traceable across runs even when its title is edited. Field documentation comes with the first delivery, the project starts with a free assessment, and a sample can be ordered first. Plans start from EUR 169 a month, or EUR 199 for a one-time extract.

Fields We Extract From Greenhouse Boards and Jobs

A Greenhouse board has two layers, and we read both. The board page lists open roles under department headings with a search box and filters; the job page holds the posting itself, the pay block and the application form. The fields:

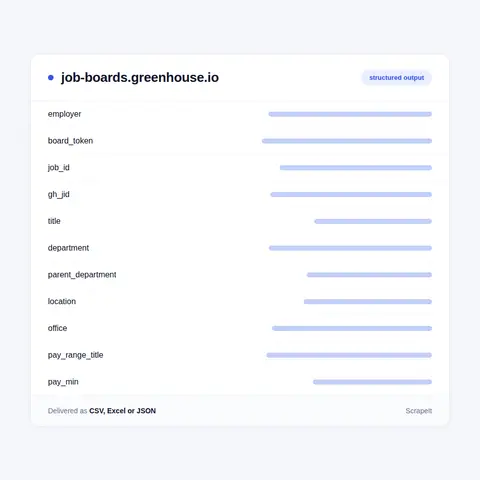
  • Boardemployer name, the board token taken from the address, the header line such as Current openings at Discord, the company introduction some employers add above the list, the logo and the counter of open jobs.
  • Job identitynumeric job id, job URL, the gh_jid value when the board is embedded in a career site, the title and the New tag Greenhouse shows on recent postings.
  • Departmentthe department and, on boards that nest them, its parent, so AI Engineering rolls up to Engineering and Customer Support to CIO.
  • Locationthe location line exactly as the employer writes it, including multi-country remote lines like Remote, Canada; Remote, United States, plus the office a role is filed under where the board shows offices.
  • Pay rangesevery pay block with the heading the employer gave it (United States Salary Range, Base Salary), minimum, maximum and currency; jobs with several blocks keep them apart.
  • Posting textthe introduction, the role description and the closing section on benefits and equal opportunity, as HTML and as plain text.
  • Datesthe publication date and the last update of each posting.
  • Application questionsthe labels of required and optional questions, such as visa sponsorship, country of residence or earlier work for the company, accepted resume file types, and whether a voluntary self-identification section is attached.

Only the questions an employer asks are collected, never anything a candidate submits. Names of recruiters, hiring managers or founders that turn up in posting text or a board introduction are personal data and are removed by default.

Fields We Extract From Greenhouse Boards and Jobs
Building a Greenhouse Dataset Across Many Employers

Building a Greenhouse Dataset Across Many Employers

One Greenhouse board is one employer, so the value sits in the set. We assemble the list of boards with you - from a target account list, a sector or a region - and run them together into one Greenhouse dataset with the employer as a column.

Inside each board we walk every numbered results page and both filters the board offers: Department and, where the employer switches it on, Office. The board's own count of open jobs is stored beside the rows we collected, which shows at a glance whether a run is complete.

History comes from repetition. A daily or weekly run keyed on the job id records when a posting first appeared, when its title, location or pay range changed and when it left the board - the closest public sign of a filled or withdrawn role. Over months that turns into hiring velocity per department and office, and a record of how pay ranges for the same role move. Boards hosted on other applicant tracking systems can join the same table with the same columns.

How Greenhouse Job Boards Are Organised

Source
job-boards.greenhouse.io
Category
job boards
Delivery
API, JSON feed, CSV, XLSX
Plans
From €169 a month
Get a quote

Greenhouse is an applicant tracking system: employers run hiring in it and publish their openings on a public job board it hosts. The board is the part a candidate sees, and the part we collect. Each employer gets a token in the address - job-boards.greenhouse.io/gitlab, job-boards.greenhouse.io/discord - and each job a numeric id under /jobs/.

One board can surface in several places. Older links on boards.greenhouse.io still open it, some boards sit on job-boards.eu.greenhouse.io, and many larger companies send visitors to their own career site, where the Greenhouse job list is embedded and job links carry a gh_jid parameter. The board interface follows the visitor's browser language, while postings stay in the language the employer wrote them in.

Each employer configures its own board: whether departments nest, whether an Office filter appears, whether the New tag and the job counter show, and what goes into the pay block. Software, fintech, gaming and education companies all hire this way, so two boards rarely look alike even though the structure underneath is shared, and an extractor has to read each one as its owner set it up.

25Developers
500+Customers
1.5BPages extracted
15,000+Hours saved for our clients

Greenhouse scraping plans and pricing

Airplane

€199one-time

Setup fee included

100,000
One-time
Up to 5 days
7 days

Helicopter

€169/ mo

Setup fee €499

250,000
Monthly
Up to 5 days
14 days

Glasses

€229/ mo

Setup fee €499

1,000,000
Weekly
Up to 5 days
30 days

Microscope popular

€349/ mo

Setup fee €499

2,000,000
Daily
Same day
60 days

DNA

€549/ mo

Setup fee €799

3,000,000
3 times daily
Same day
90 days

Delivery: CSV, JSON or XLSX files, our API or a JSON feed. MCP server on request.

Full plan details

What Greenhouse Job Data Is Used For

A Greenhouse board is the employer's own copy of its openings, so it answers questions that aggregated job sites blur.

  • Hiring signals for sales and investorsnew postings by department show where a company is building: a cluster of roles under one engineering group or a first opening in a new country appears on the board with the department path attached.
  • Pay benchmarkingpay range blocks give a minimum, maximum and currency per role and region, ready to compare across the employers that publish them.
  • Location strategylocation lines show which countries a remote role is open to, which offices are hiring and how the mix of locations shifts.
  • Job platforms and agenciesniche job boards, aggregators and recruitment firms feed fresh roles into their own search with the link back to the employer.
  • Competitive intelligencerepeated runs show which teams grow, which postings stay open for months and which close within days.

About ScrapeIt

ScrapeIt is a managed web scraping service. We build and run crawlers for job boards, marketplaces and directories and deliver the result as files, a JSON feed or rows in your database. For hiring data we work from the employer list outward: which companies, which boards, how often. Personal data is handled under GDPR, and we do not build profiles of recruiters or candidates.

FAQ

Still unsure? Write to info@scrapeit.io

Do you offer a Greenhouse API for job postings?

Yes. The ScrapeIt Greenhouse API returns the job id, title, department path, location line, pay range blocks and publication date as JSON from an endpoint we host, refreshed on the schedule you set. The same data also comes as CSV or XLSX files, a JSON feed or straight into your database.

Is it legal to scrape Greenhouse?

Yes. Board pages, job pages and the pay ranges an employer chooses to print are open to any visitor without an account. We collect only publicly available data - everything a visitor can see on a Greenhouse board - and we collect it legally, leaving recruiter names out by default.

Can you scrape Greenhouse jobs from boards embedded in company career sites?

Yes. When an employer shows its Greenhouse list inside its own career site, each job link carries a gh_jid value that matches the job id on the hosted board. We collect from whichever address the employer uses and keep that id, so embedded and hosted boards end up with identical rows.

How often do Greenhouse job listings change?

On a large board, most days. New roles appear with the New tag, existing ones get edited titles or pay ranges, and closed roles drop off the board without notice. For hiring signals we usually run daily; for pay benchmarking, weekly is enough.

Does your Greenhouse job scraper capture pay ranges and application questions?

Yes, wherever the employer publishes them. Each pay block keeps its own heading, minimum, maximum and currency, and the application form is delivered as a list of question labels with a required flag. Answers that candidates submit are never part of the data.

How it works

  1. 1

    Make a request

    You share your needs, expectations, and desired timeframe. We'll suggest the best solution based on your request and budget.

  2. 2

    We configure the crawlers

    Our specialists configure the crawlers and extract a sample dataset for your review before proceeding with the full-scale extraction.

  3. 3

    Collect and deliver

    Once you approve the sample, we launch the project and start full data collection. We gather, filter, and structure the data for easy use, delivering it on time in your preferred format.

  4. 4

    Maintain and support

    Our team manages ongoing processes, monitors website changes, and supports all data extraction cycles. We can also help integrate data into your systems or create dashboards to simplify analysis.

Request a quote

Tell us which sites, which fields and how often. A couple of lines is enough to start.

  • We reply within 1 business day
  • A sample dataset before the full run
  • We sign an NDA on request
  • Delivery by API, JSON feed or files
Which sites, which fields, how often. A couple of lines is enough.

This form is protected by Google reCAPTCHA, which loads when you start filling it in. If you prefer not to use it, email us at info@scrapeit.io. Privacy & Cookie Policy

We reply within 1 business day. No obligation.

Greenhouse data from €169/month. Free project assessment, reply within 1 business day.