France 24 Scraper for Articles, Video and Shows in Four Languages

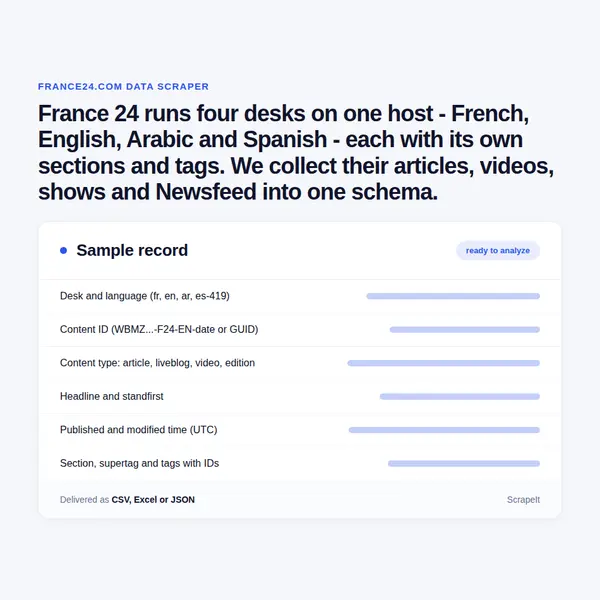
France 24 runs four desks on one host - French, English, Arabic and Spanish - each with its own sections and tags. We collect their articles, videos, shows and Newsfeed into one schema.

Plans from €169/month · Free project assessment · Reply within 1 business day

France 24 Scraper
Solutions

France 24 Data Scraping, Delivered as Files or a France 24 API

ScrapeIt runs France 24 data scraping as a managed service: we build the collector, host it and repair it when templates change. New items are found through the news sitemaps and monthly sitemaps, and fields are read from the pages themselves. The service includes anti-bot handling, proxy rotation and CAPTCHA solving, since france24.com screens automated clients at the edge. Nothing on the site needs a login. Rows carry desk, language and collection time, and arrive as CSV, JSON or XLSX in S3, SFTP or your warehouse, or through a France 24 scraper API endpoint we host.

France 24 Dataset Fields: Content IDs, Dates, Tags, Credits

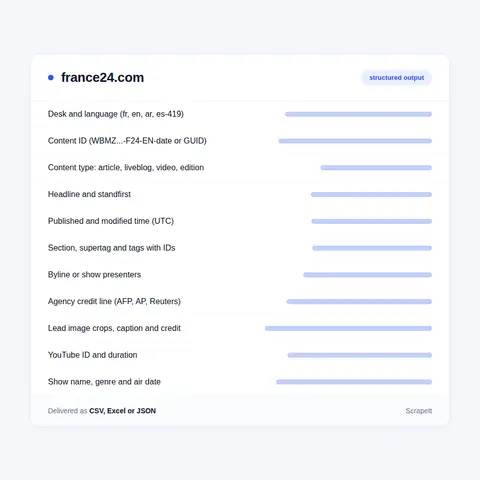
Article, video and show pages carry NewsArticle or VideoObject markup, and editorial pages add an analytics data layer; together they give a record without parsing the layout. To extract France 24 data cleanly we keep these fields:

  • Identity. The content ID from the data layer, in two shapes: IDs such as WBMZ588087-F24-EN-20260927 that carry brand, language and date, and GUIDs on many video items. On video pages the player address on embed.france24.com reuses it. Canonical URL, content type (article, edition for show episodes, video) and media type (texte, video, liveblog) come with it.
  • Headline, standfirst and body. Headline, the standfirst printed under it, full text and wordCount. The slug keeps the first headline, so a live page retitled during the day still shows its opening title in the address.
  • Dates. datePublished and dateModified in UTC; the page prints Paris time, labelled Issued on and Modified in English.
  • Section and tags. articleSection, a supertag for the section and tags with name, slug and ID. Tag IDs repeat across a desk's pages, so tags join on ID, not on label.
  • Credits. The byline as printed, the FRANCE 24 organisation or named journalists, and the agency line that closes many stories, such as (FRANCE 24 with AP, AFP and Reuters). Listings mark wire copy with an AFP label, beside format labels such as Analysis, On the ground or As it happened.
  • Images. The lead image in five crops, from 16x9 to 9x16, with caption and credit; file names often keep the agency's own picture ID.
  • Context. Related links from og:see_also, reading time and the Most read box each desk shows beside its articles.

Sponsored content is kept apart: it sits under /en/sponsored-content/, its articleSection reads Sponsored content and the sponsor is credited as author.

France 24 Dataset Fields: Content IDs, Dates, Tags, Credits
France 24 Schedule, Shows, Video and the Live Stream

France 24 Schedule, Shows, Video and the Live Stream

France 24 is a television channel first, so many records are video.

  • France 24 video. Video pages carry VideoObject markup with title, summary, upload date, duration and a YouTube address, since FMM plays its videos through an unbranded YouTube player. Clips cut from the channels get thumbnails named after channel, air date and in and out times, such as AR-20260927-173426-173931-CS.
  • Shows. Episodes of The Debate, Focus, Reporters or Truth or Fake carry a show object (name, slug, ID, genre), presenters and an air date stored as midnight Paris time. Episode records add running time and an MP4 file link.
  • Live stream and grid. The France 24 news live stream plays on /en/live, with the France 24 TV guide at /en/tv-guide and matching pages in French, Arabic and Spanish. The France 24 schedule today and yesterday are the only days online, with slot start in Paris time, programme, presenters and show link, so a history is built by capturing each grid daily.
  • Transcripts. Pages publish a summary, not a transcript, and the transcript option of the shared player is switched off. A captioned newscast for deaf and hard-of-hearing viewers runs in English and French.

We keep media as metadata and links; the footage stays with FMM.

France 24 Articles From Four Desks on One Host

A France 24 scraper has to treat one domain as four newsrooms. France 24, the international news channel of France Medias Monde, went on air on 6 December 2006 in French and English, added Arabic in April 2007 and a Spanish service in 2017. All four live on www.france24.com as path prefixes: /fr/, /en/, /ar/ and /es/. France 24 is free to read and watch, with no paywall, no meter and no registration wall, so every article renders in full.

What the desks share is the frame. The four fronts point to each other with hreflang, show brands such as Focus, Reporters and The Observers run in several languages, and one CMS builds every page with the same markup. What they write separately is the journalism. Articles carry no hreflang to a counterpart, each desk tags with its own taxonomy (the tag Israel has one ID in English and another in Spanish), and the section trees differ: the Spanish desk splits America Latina from the US and Canada, France 24 Arabic runs a Maghreb section, the English desk a single Americas section.

Addresses follow the language. French and Spanish slugs keep their accents, Arabic slugs are written in Arabic script and arrive percent-encoded, and inLanguage reads fr, en, ar or es-419, since the Spanish service writes for Latin America. The section in an article URL is not always the slug of the section page, so sections are read from the markup, not from the path.

Get a Quote
dev_w
25

Developers

customers
500+

Customers worldwide

pages
1 500 000 000+

Pages extracted

stime
15000+

Hours saved for our clients

Plans

France 24 Scraping Plans and Pricing

Airplane

€199 / one-time

setup fee - included

Data limits100,000
Frequencyone-time
Run timeup to 5 days
Data storing7 days

Helicopter

€169 / mo

setup fee €499

Data limits250,000
Frequencymonthly
Run timeup to 5 days
Data storing14 days

Glasses

€229 / mo

setup fee €499

Data limits1,000,000
Frequencyweekly
Run timeup to 5 days
Data storing30 days

DNA

€549 / mo

setup fee €799

Data limits3,000,000
Frequency3 times daily
Run timesame day
Data storing90 days

France 24 Headlines Compared Across Four Desks

France 24 was built to carry a French perspective on world affairs, and each of its four desks chooses what its own audience hears. One company, one CMS and one data layer sit behind all four, so differences between desks are editorial, not technical.

  • Agenda comparison. Compare what France 24 Arabic leads with for the Maghreb and the Middle East, what the Spanish desk tells Latin America and what the French desk gives French-speaking Africa. Sections and tags are counted per desk without translating a word.
  • Headline boards. A board of France 24 headlines today polls the four fronts, the Newsfeed and each France 24 news sitemap every few minutes and reads each new page once.
  • Wire versus own reporting. The France 24 Newsfeed carries AFP dispatches, labelled AFP in listings and listed without keywords or images in the news sitemap, while desk stories close with a credit line and some Newsfeed addresses end up holding a full desk story. Splitting the two shows what the channel reports itself.
  • Verification research. Truth or Fake, the France 24 Observers and the Fight the Fake hub publish dated, tagged debunks of viral images and claims, a ready corpus for disinformation studies.
  • Attention and sponsorship. The Most read box, captured hourly, ranks what readers pick in each language, and sponsored pieces can be counted by sponsor.

Our Blog

Reads Our Latest News & Blog

Learn how to use web scraping to solve data problems for your organization

How Artificial Intelligence Is Used In Web Scraping

How Artificial Intelligence Is Used In Web Scraping

Leveraging advances in technology, the AI-powered web scraper has skyrocketed in demand and is helping to expand capabilities by automating tedious daily tasks and speeding up data collection from thousands of websites several times over.

What is Web Scraping and What is it Used For?

What is Web Scraping and What is it Used For?

Web scraping is a method of obtaining web data by extracting it from pages of web resources with the help of a program, that is, in automatic mode. It is used to syntactically convert web pages into more usable forms.

Web Scraping for Machine Learning

Web Scraping for Machine Learning

If you specialize in machine learning, you need to feed large amounts of data to the algorithms. Web scraping is the easiest and the most efficient method of collecting the data from all over the Internet.

scrapeit logo

Starting a France 24 Project With ScrapeIt

ScrapeIt is a managed web scraping agency. You name the desks, sections, shows and date range; we design the crawl, run it and deliver records that load without cleaning. A sample comes first, usually a week of two desks with IDs, tags and credits, so you can test the schema before a schedule is agreed. The price of a France 24 dataset depends on languages, content types, refresh rate and archive depth, from a five-minute headline monitor to a one-off pull back to 2006.

FAQ

Do you offer a France 24 API?

Yes. The ScrapeIt France 24 API returns the content ID, headline, standfirst, dates, tags and credits for all four desks as JSON from an endpoint we host, refreshed on the schedule you set. The same data also comes as CSV or XLSX files or straight into your database.

How quickly can new France 24 headlines be collected?

Within minutes. A five-minute headline monitor polls the fronts of France 24 English, French, Arabic and Spanish, the Newsfeed and the news sitemaps, and reads each new page once. Each record comes with headline, standfirst, section, tags, credits, datePublished and dateModified, and the full text.

How far back do the France 24 archives go?

To the launch. Month pages under /en/archives/, /fr/archives/ and their Spanish and Arabic twins list articles, shows and videos by day, filter by section and page through the month, so France 24 archives 2025 means twelve monthly listings per desk. Monthly sitemaps start in late 2006 for English and French, May 2007 for Arabic and April 2017 for Spanish. Addresses changed over time: 2007 stories sit at /en/YYYYMMDD-slug with no section, today's at /en/section/YYYYMMDD-slug, and some video and fact-check pages use a bare slug with no date.

Can you match one story across the French, English, Arabic and Spanish desks?

Yes, as a derived link rather than a declared one. France 24 articles carry no hreflang to their counterparts, tag IDs differ between desks and slugs are written in each language, so versions are matched on publication time, named entities and shared agency pictures. Each match comes with a confidence score, and you can keep only the certain ones or review the rest. Unmatched stories stay in the data, which is how you see what one desk covered and the others skipped.

Is it legal to scrape France 24?

Yes. We collect only publicly available data - everything a visitor sees on France 24, the France Medias Monde news channel - and we collect it legally. Across all four desks that means articles with headline, standfirst, full text, dates, section, tags and credits, plus videos, shows and the Newsfeed, all without a login or any special access. Observers' contributors are private people and stay out.

How does it Work?

Step 1 - Make a Request

You share your needs, expectations, and desired timeframe. We’ll suggest the best solution based on your request and budget.

Step 2 - Configuring Custom Web Crawlers

Our specialists configure the crawlers and extract a sample dataset for your review before proceeding with the full-scale extraction.

Step 3 - Collect and Deliver

Once you approve the sample, we launch the project and start full data collection. We gather, filter, and structure the data for easy use, delivering it on time in your preferred format.

Step 4 - Maintain and Support

Our team manages ongoing processes, monitors website changes, and supports all data extraction cycles. We can also help integrate data into your systems or create dashboards to simplify analysis.

Request a Quote

Tell us more about you and your project information.
Which sites, which fields, how often. A couple of lines is enough.

We reply within 1 business day. No obligation.

scrapiet

Scrapeit Sp. z o.o.
10/208 Legionowa str., 15-099, Bialystok, Poland
NIP: 5423457175
REGON: 523384582