Handelsblatt fields in every export
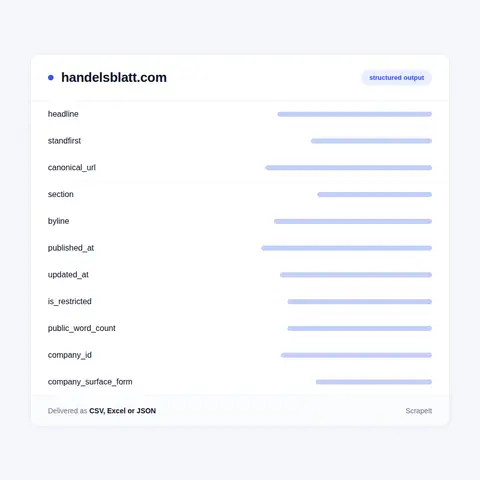
The article record covers canonical URL, headline, standfirst, section and subsection, byline, publication timestamp, last updated timestamp, item type and the article identifier.
Company mentions are extracted and normalised to identifiers rather than left as strings. German corporate names carry legal forms, and the same company appears with and without them, with and without the group suffix, and in abbreviated forms. Matching without normalisation loses a large share of mentions and loses them unevenly between companies.
The access flag records whether the article was subscriber restricted at collection time and how much text rendered publicly, so an opening is never counted as a full article.
German text handling runs throughout: text is stored with umlauts intact, and matching handles both the umlaut and the transliterated form because URLs and slugs strip them while body text does not. Compound words are handled explicitly, since a brand name inside a German compound will not match a naive search.
Then the usual context: topic and industry tags where published, word count of the publicly rendered portion, front position from repeated observation, and the collection timestamp on every row.