Sky News Scraper for Stories, Live Blogs and Video

Sky News runs live blogs that last for years, a front pages blog and about a thousand clips a month, all on one numeric ID sequence. We turn them into one feed of headlines, posts, desks and timestamps.

Plans from €169/month · Free project assessment · Reply within 1 business day

Sky News Scraper
Solutions

How We Scrape Sky News Headlines, Live Blogs and Video

ScrapeIt runs Sky News scraping as a managed service: we build the collector, host it and repair it when templates change. news.sky.com screens automated clients hard, so anti-bot handling, proxy rotation and CAPTCHA solving are part of the job. We extract Sky News data from public pages and sitemaps, never from behind a login, and every row carries the content ID, page type, desk and the time it was read. A sample comes first; after sign-off, runs follow your cadence, from a one-minute headline monitor to a backfill over topic pages and video sitemaps, delivered as CSV, JSON or XLSX to S3, SFTP or your warehouse, or through a Sky News scraper API endpoint.

Sky News Articles: Headlines, Bylines, Desks and Clocks

Story pages carry NewsArticle markup, and with the page around it that gives a clean record of Sky News articles without parsing the layout.

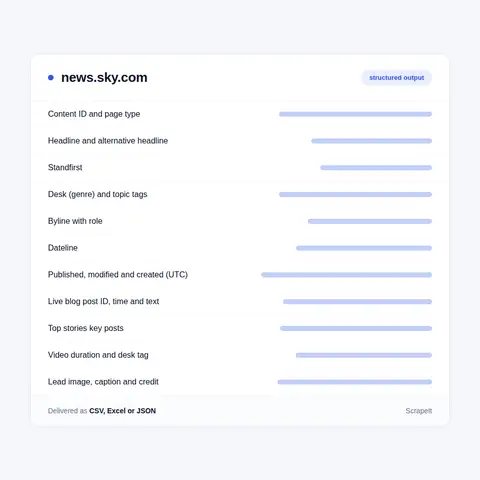
  • ID and type. The numeric content ID, the canonical URL and the page type. Slugs follow the headline, so one story can sit at two addresses; the ID joins them.
  • Two headlines. headline plus alternativeHeadline, the form cards show, which can be shorter. The news sitemap can disagree as well: the same story reads "Manchester City boss" in the sitemap and "Man City boss" elsewhere. We keep each version with the time it was seen.
  • Standfirst and body. description, the full articleBody with its paragraphs and embed markers, wordCount, a dateline such as London, UK, and inLanguage en-GB.
  • Desk and topics. genre names the desk in plain words (uk news, politics, money), the page title repeats it as UK News or Money News, and Related Topics link to topic pages with IDs of their own.
  • Byline. A Person entry whose name string also holds the role, for example news reporter; unsigned pieces credit the publisher instead.
  • Clocks. datePublished, dateModified and dateCreated in UTC; the page prints the last update in UK time; the video sitemap gives UK local time with no offset; the news sitemap gives the day only. We normalise all of them to UTC.
  • Labels. Card flags for Breaking, Live, Exclusive, Analysis and Explainer, so Sky News breaking news, exclusives and Sky News analysis can be filtered apart.
  • Image. The lead picture at 2048x1152 on the e3.365dm.com image server, with caption and agency credit such as Pic: Reuters or Pic: PA.

Sky News Articles: Headlines, Bylines, Desks and Clocks
Sky News Live Blog Posts, Front Pages and Clips

Sky News Live Blog Posts, Front Pages and Clips

Sky News live updates are a signature format of the site, and the big blogs last for years under one ID. Politics latest, the Sky News politics live blog behind /politicshub, has used ID 12593360 since April 2022; the Sky News Money blog at /money-live dates from January 2024. Each is a LiveBlogPosting: the markup can carry coverage start and end times and the ten newest posts with headline, full text and their own timestamps, and the page opens with a Top stories list linking to key posts by post ID. Older posts load twenty at a time, newest or oldest first, and bylines sit inside the post text. datePublished gets reset while dateCreated keeps the first day, and with an old ID these blogs drop out of the news sitemap, so we find them through the fronts, the Live topic and the short addresses.

The Sky News front pages blog works the same way: since October 2021 one ID has carried the national newspaper front pages, one late-evening post per paper, while The Wrap posts a video review of the papers.

Video is the other half of the output. Video sitemaps run monthly from January 2017 and held roughly 900 to 1,100 clips a month through 2025 and 2026; since August 2024 each entry adds duration and publish time, and most carry a desk tag such as News UK Climate Video. Sky News programmes add full episodes of close to an hour. Each of the Sky News videos becomes a record with title, standfirst, duration, desk tag, thumbnail, player ID and publish time, and Sky News podcasts appear as story pages of their own type.

Sky News Data: One ID for Stories, Live Blogs and Video

A Sky News scraper has to start from how news.sky.com numbers things. Sky News, the UK's first 24-hour news channel, on air since 5 February 1989 and an editorially independent part of Sky UK, puts Sky News stories, live blogs, videos and podcast episodes on one numeric ID sequence, placed at the end of every address. The words in front of the ID are decoration: a rewritten headline brings a new slug, the old one keeps working, and the ID stays the only reliable key. Each record therefore carries the ID and the page type - article, live blog, video or podcast.

The fronts follow the desks: UK, Politics, World, US, Money, Science, Climate & Tech and Ents & Arts, plus Analysis, Data x Forensics, Offbeat, Programmes, Videos and Weather. Older names survive underneath. /business now lands on Money, /technology and /climate both land on Science, Climate & Tech, and climate clips keep a desk tag of their own. The Sky News Data and Forensics unit adds interactive pieces, such as a postcode lookup for council tax rises, next to its analysis.

Below the fronts sit topic pages at /topic/{name}-{id}, paged /2, /3 and on. The number picks the topic, not the name, a page past the end loads empty rather than failing, and the lists run back years: the Live topic reaches May 2018. For any backfill, topic pages are the spine.

Get a Quote
dev_w
25

Developers

customers
500+

Customers worldwide

pages
1 500 000 000+

Pages extracted

stime
15000+

Hours saved for our clients

Plans

Sky News Scraping Plans and Pricing

Airplane

€199 / one-time

setup fee - included

Data limits100,000
Frequencyone-time
Run timeup to 5 days
Data storing7 days

Helicopter

€169 / mo

setup fee €499

Data limits250,000
Frequencymonthly
Run timeup to 5 days
Data storing14 days

Glasses

€229 / mo

setup fee €499

Data limits1,000,000
Frequencyweekly
Run timeup to 5 days
Data storing30 days

DNA

€549 / mo

setup fee €799

Data limits3,000,000
Frequency3 times daily
Run timesame day
Data storing90 days

Sky News Sitemaps: What They Carry and Miss

Outside the pages themselves, the machine-readable layer is thin. The news sitemap adds a desk code per story (uk_news, politics, money, science_climate_tech, news_uk_audio for podcasts) but keeps only about two days and dates each story to the day.

That is why buyers read the pages. Communications teams track a company across stories, live blog posts and clip titles rather than a handful of headlines. Public affairs teams follow the politics blog post by post on Budget and conference days. Deal watchers log Money desk exclusives, the stories marked Exclusive or ending "Sky News understands", and consumer desks chart how Sky News covers diesel prices, rents and council tax. For a live board of Sky News headlines today, a monitor polls the fronts every minute and reads each new page once for the byline, desk, body and clocks.

Our Blog

Reads Our Latest News & Blog

Learn how to use web scraping to solve data problems for your organization

How Artificial Intelligence Is Used In Web Scraping

How Artificial Intelligence Is Used In Web Scraping

Leveraging advances in technology, the AI-powered web scraper has skyrocketed in demand and is helping to expand capabilities by automating tedious daily tasks and speeding up data collection from thousands of websites several times over.

What is Web Scraping and What is it Used For?

What is Web Scraping and What is it Used For?

Web scraping is a method of obtaining web data by extracting it from pages of web resources with the help of a program, that is, in automatic mode. It is used to syntactically convert web pages into more usable forms.

Web Scraping for Machine Learning

Web Scraping for Machine Learning

If you specialize in machine learning, you need to feed large amounts of data to the algorithms. Web scraping is the easiest and the most efficient method of collecting the data from all over the Internet.

scrapeit logo

Ordering a Sky News Dataset or a Sky News API Feed

ScrapeIt is a managed web scraping agency. You name the desks, topics, live blogs and date range; we design the crawl, run it and deliver a Sky News dataset that loads into your tools without cleaning: one row per story, per live blog post and per clip, joined on the numeric ID, as files or from an endpoint we host. Most projects start with a headline monitor and one live blog, then add video and a topic backfill once the fields are agreed. Pricing follows volume and refresh rate, and you check a sample before committing.

FAQ

Do you offer a Sky News API?

Yes. The ScrapeIt Sky News API returns the content ID, page type, headline, byline, desk and publish time for stories, live blog posts and Sky News clips as JSON from an endpoint we host, refreshed on the schedule you set. The same data also comes as CSV or XLSX files or straight into your database.

How quickly do new Sky News headlines reach the dataset?

As quickly as the cadence you set, down to a one-minute headline monitor. Each new page is read once for the content ID, headline, standfirst, byline, desk and clocks, and every version of a headline is kept with the time it was seen. Live blog posts, videos and topic pages run on the same schedule.

How far back does the Sky News archive go?

Further than any single list shows. Story and video pages stay online by ID, and topic pages page back for years: the Live topic reaches May 2018. Video sitemaps are monthly from January 2017, with November and December 2024 missing, and where the 2017 files list slugs that no longer open, the ID with a clean slug still does. There is no dated archive and no story sitemap, so a backfill combines topic pages, video sitemaps and ID ranges. Sky News footage on the site is collected from the video pages, each clip a record with title, duration, desk tag and publish time.

Is there a Sky News paywall, or is Sky News free?

There is no paywall: stories, live blogs and videos on news.sky.com are free and carried by advertising. As for how much Sky News costs beyond that, the one paid layer is Sky News Insider, a UK-only subscription for bonus episodes of three Sky News podcasts, Electoral Dysfunction, Trump100 and Stuff Matters, run by the podcast partner Supporting Cast. On 28 September 2026 the Sky News Insider price was GBP 2.99 a month or GBP 29.99 a year. Free episodes stay public; subscriber-only episodes sit behind a login, and we do not collect them.

Is it legal to scrape Sky News?

Yes. We collect only publicly available data - everything a visitor can see on Sky News, from stories and live blog posts to video and podcast pages, topic lists and sitemaps - and we collect it legally. No logins, no paywalls: subscriber-only Sky News Insider episodes are not part of it. Bylines are kept as published, we build no profiles of people, and personal data is handled under GDPR.

How does it Work?

Step 1 - Make a Request

You share your needs, expectations, and desired timeframe. We’ll suggest the best solution based on your request and budget.

Step 2 - Configuring Custom Web Crawlers

Our specialists configure the crawlers and extract a sample dataset for your review before proceeding with the full-scale extraction.

Step 3 - Collect and Deliver

Once you approve the sample, we launch the project and start full data collection. We gather, filter, and structure the data for easy use, delivering it on time in your preferred format.

Step 4 - Maintain and Support

Our team manages ongoing processes, monitors website changes, and supports all data extraction cycles. We can also help integrate data into your systems or create dashboards to simplify analysis.

Request a Quote

Tell us more about you and your project information.
Which sites, which fields, how often. A couple of lines is enough.

We reply within 1 business day. No obligation.

scrapiet

Scrapeit Sp. z o.o.
10/208 Legionowa str., 15-099, Bialystok, Poland
NIP: 5423457175
REGON: 523384582