The Independent Scraper for UK Coverage and Live Blogs

High volume, free to read and heavy on live coverage - which means the interval between your passes decides how much of the story you actually get.

The Independent Scraper
Solutions

Managed UK news collection, run end to end by us

ScrapeIt runs the collector as a managed service. You name the sections and subjects; we build the pipeline, read fronts at a rate matched to the publishing pace, collect live pages entry by entry and hand back CSV, JSON, Excel or a push into your warehouse.

Cadence is tiered and agreed at the start, because on this source it is the main cost driver and the main determinant of whether the dataset is any good.

We collect what the site renders publicly and flag Premium articles rather than working around the tier. Journalism is copyrighted and the terms restrict reuse, so the dataset is for analysis rather than republication. Bring the use case to your own counsel before the project starts.

The Independent fields in every export

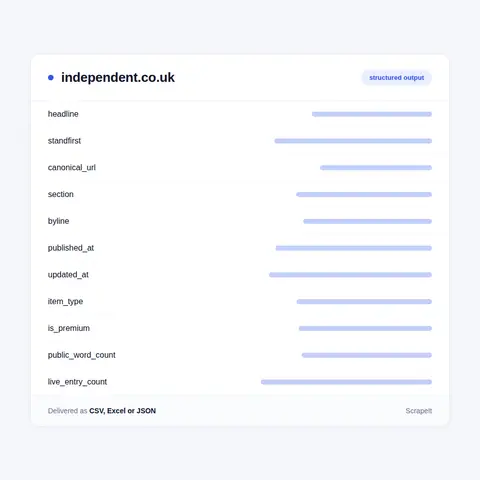
The article record covers canonical URL, headline, standfirst, section and subsection, byline, publication timestamp, last updated timestamp, item type and the article identifier.

The access flag records whether the article was Premium at collection time and how much text rendered publicly. Most output is free, which makes the flagged minority easy to handle and easy to forget - so it is a field rather than an assumption.

Live pages are collected as a parent record with their stream of timestamped entries: entry text, time, author where credited, and any embedded quote or link. The parent carries an entry count and the time of the latest entry, so a page that has gone quiet is distinguishable from one still running.

Both timestamps are kept separately, which matters here because headlines on fast moving stories are rewritten in place through the day.

Front observations record which items sat on a front, in what order and when. On a high volume title, promotion is a far better proxy for editorial weight than a count of items.

The Independent fields in every export
Live blogs, prominence and comparison with other UK titles

Live blogs, prominence and comparison with other UK titles

Live blog handling is the technical centre of this source. Entries are collected as they appear rather than once at the end, because a page collected after it closes loses the timing of everything inside it, and the timing is what makes a live blog worth having.

Prominence data comes free once fronts are read on a schedule, and on a high volume title it is the measure that separates a promoted story from one that appeared in a section listing for an hour.

Comparison with other British titles is the usual extension. A UK share of voice number needs several outlets collected on consistent rules, and the mix matters: a free high volume title and a paywalled title of record contribute very differently to a count, which is a reason to weight rather than to exclude.

Historical backfill is practical because URLs are stable and section pagination reaches back. Live page entries generally remain available afterwards, though their timing can only be captured as they happen.

A digital-only paper with a high publishing rate

The Independent is a digital only national title with an unusually high publishing rate for a UK paper. Most of the output is free to read, with a Premium tier over a smaller portion, which makes it one of the more completely collectable British sources.

Live coverage is a large part of what it does. Running stories, politics and sport are frequently covered through live pages that update continuously for hours, and on a busy day a substantial share of the day's reporting exists only inside them.

Section fronts respond directly and carry ordered selections. The conventional news sitemap path is not served, so discovery leans on fronts and feeds, which costs a few more requests and yields prominence data as a by product.

The volume and the pace together set the design. A daily collection on this source captures headlines and misses most of what actually happened, because the interesting material moved and settled between passes.

Get a Quote
dev_w
25

Developers

customers
500+

Customers worldwide

pages
1 500 000 000+

Pages extracted

stime
15000+

Hours saved for our clients

Plans

Airplane

€199 / one-time

setup fee - included

Data limits100,000
Frequencyone-time
Run timeup to 5 days
Data storing7 days

Helicopter

€169 / mo

setup fee €499

Data limits250,000
Frequencymonthly
Run timeup to 5 days
Data storing14 days

Glasses

€229 / mo

setup fee €499

Data limits1,000,000
Frequencyweekly
Run timeup to 5 days
Data storing30 days

DNA

€549 / mo

setup fee €799

Data limits3,000,000
Frequency3 times daily
Run timesame day
Data storing90 days

Why the collection interval decides what you get

On a slow title a daily pass is fine. Here it is not, and the reason is arithmetic rather than opinion: if items appear and get replaced on the front faster than you look, most of them never enter your dataset with any context at all.

What survives a daily pass is the set of items that happened to be visible at that moment, which is neither a sample nor a census. Volume charts built from it move with collection timing rather than with news.

So the cadence is set against the publishing rate rather than against a habit. Fronts are read frequently, live pages more frequently while they are active, and archive work runs slowly. That tiering is agreed before collection starts because it decides the cost.

The second reason is live coverage. On a busy day most of the actual reporting is inside live pages, and a collector that stores each as a single article with a changing headline captures a headline and loses the story. Entry level collection is the difference between having the day and having a summary of it.

The third is the free access, which is genuinely useful: because most output renders publicly, this is one of the few large British titles where a near complete text corpus is achievable without a licensing conversation.

Our Blog

Reads Our Latest News & Blog

Learn how to use web scraping to solve data problems for your organization

How Artificial Intelligence Is Used In Web Scraping

How Artificial Intelligence Is Used In Web Scraping

Leveraging advances in technology, the AI-powered web scraper has skyrocketed in demand and is helping to expand capabilities by automating tedious daily tasks and speeding up data collection from thousands of websites several times over.

What is Web Scraping and What is it Used For?

What is Web Scraping and What is it Used For?

Web scraping is a method of obtaining web data by extracting it from pages of web resources with the help of a program, that is, in automatic mode. It is used to syntactically convert web pages into more usable forms.

Web Scraping for Machine Learning

Web Scraping for Machine Learning

If you specialize in machine learning, you need to feed large amounts of data to the algorithms. Web scraping is the easiest and the most efficient method of collecting the data from all over the Internet.

scrapeit logo

Who builds and keeps your Independent feed

ScrapeIt is a managed extraction company, not a tool you have to learn. Our team builds the pipeline, watches it as fronts and live page templates change, and repairs it before a running story passes you by.

You see a sample first, in your format, over the sections you actually track, including a live page collected entry by entry so you can see what a daily pass would have missed.

FAQ

Why is a daily collection not enough here?

Arithmetic. Items appear and get replaced on the front faster than a daily pass looks, so most never enter the dataset with any context. What survives is whatever happened to be visible at that moment, which is neither a sample nor a census, and volume charts built from it move with your collection timing rather than with the news.

How do you collect live blogs?

As a parent record plus timestamped entries, collected as they appear rather than once at the end. A page collected after it closes loses the timing of everything inside it, and on a busy day most of the actual reporting lives in those entries.

How much is behind the Premium tier?

A minority. Most output is free to read, which makes this one of the few large British titles where a near complete text corpus is achievable without a licensing conversation. The restricted articles are flagged as a field rather than assumed away, precisely because they are easy to forget.

How does this compare with other UK titles in a report?

It needs weighting rather than excluding. A free high volume title and a paywalled title of record contribute very differently to a raw count, so a UK share of voice number built without accounting for that will overstate whichever publishes most. We collect several outlets on consistent rules and make the difference visible.

How often can the feed refresh, and in what formats?

From a daily digest up to frequent passes on the fronts and active live pages you nominate, tiered and agreed at the start since it is the main cost driver. Delivery is CSV, Excel, JSON, JSONLines or XML over FTP, SFTP, Amazon S3, Google Cloud Storage, Dropbox, Google Drive or email, or written straight into your database.

How does it Work?

Step 1 - Make a Request

You share your needs, expectations, and desired timeframe. We’ll suggest the best solution based on your request and budget.

Step 2 - Configuring Custom Web Crawlers

Our specialists configure the crawlers and extract a sample dataset for your review before proceeding with the full-scale extraction.

Step 3 - Collect and Deliver

Once you approve the sample, we launch the project and start full data collection. We gather, filter, and structure the data for easy use, delivering it on time in your preferred format.

Step 4 - Maintain and Support

Our team manages ongoing processes, monitors website changes, and supports all data extraction cycles. We can also help integrate data into your systems or create dashboards to simplify analysis.

Request a Quote

Tell us more about you and your project information.
Which sites, which fields, how often. A couple of lines is enough.

We reply within 1 business day. No obligation.

scrapiet

Scrapeit Sp. z o.o.
10/208 Legionowa str., 15-099, Bialystok, Poland
NIP: 5423457175
REGON: 523384582