LaLiga Scraper for Fixtures, Tables and Player Stats

The official source settles arguments that aggregators start, and on a league with two divisions it is also the only one that keeps a relegated club's history continuous.

LaLiga Scraper
Solutions

Managed LaLiga data collection, run end to end by us

ScrapeIt runs the collection as a managed service. You choose the divisions, seasons and languages; we build the pipeline against the structured layer where it is available, run the backfill once and the in season updates around matchdays, and hand back CSV, JSON, Excel or a push into your warehouse, with both name forms kept and division movement recorded.

Cadence in season is matchday driven, which keeps it cheap: fixtures are known in advance, tables move after matches and statistics settle shortly after.

We read structured responses rather than driving a browser across rendered pages, and we pace what we send. Competition data is a compilation with rights attached and the site carries terms on automated collection and reuse, so the dataset is for analysis and internal product use rather than republication. If your use case touches betting or public redistribution, take it to your own counsel first.

LaLiga fields in every export

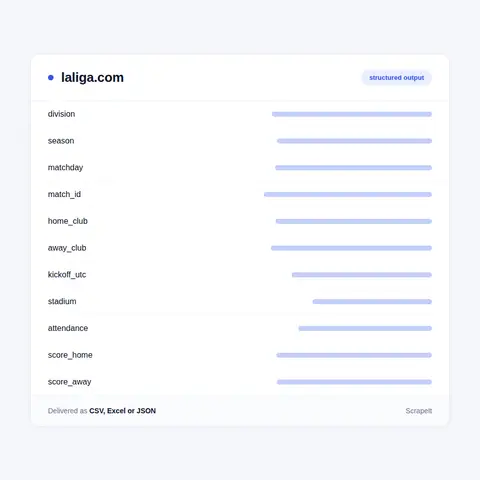
Fixture and result records cover division, season, matchday, match identifier, home and away club, kickoff in local time and UTC, stadium, attendance where published, half time and full time score, and status.

Table records carry division, season, matchday, position, club, played, won, drawn, lost, goals for and against, goal difference and points, stored per matchday rather than only as a final standing. A final table says who won; a table per matchday shows when the season turned.

Match detail covers goals with scorer, assist and minute, cards, substitutions and the team statistics the league publishes.

Club and player records carry identifiers, names in both languages, nationality, position, shirt number, date of birth and season aggregates for appearances, minutes, goals, assists and cards.

Division movement is captured explicitly: which clubs were promoted or relegated and in which season. Without it a multi season club history is a set of disconnected fragments, and reconstructing it afterwards from table positions is unreliable.

LaLiga fields in every export
Promotion, matchday tables and cross-league joins

Promotion, matchday tables and cross-league joins

Promotion and relegation are recorded as their own fact rather than inferred from final positions. Inference breaks wherever a playoff, a licensing decision or a points deduction is involved, and those are precisely the seasons somebody will ask about.

Matchday tables are stored as they stand each week. Reconstructing them later from results is error prone and sometimes impossible, and storing them as you go costs nothing.

Cross league joins are the usual extension. Clients comparing Spanish clubs with English or German ones need club and player identity normalised across sources and languages, which is the same entity work described on our other sports pages and the reason those pages exist as a set.

Valuation and transfer data joins here naturally too: official squad lists on one side, market values on the other, matched on normalised player identity, answer whether a promoted club actually invested or carried the squad that came up.

Two divisions, two languages, one authority

The official LaLiga site is the authority for its own competitions: fixtures, results, tables, squads and player statistics. When an aggregator and the league disagree, the league is right, and that is the whole reason to collect here rather than only from a results service.

It covers both the top division and the second, which matters more than it sounds. Promotion and relegation move clubs between them every season, and a dataset that holds only the top flight loses a club's history the moment it goes down. The gap looks like missing data rather than a structural choice, and it appears for exactly the clubs whose stories are most interesting.

The site publishes in Spanish and English. Club and player names render differently between editions, and Spanish names carry accents that appear stripped in URLs and slugs but present in body text. Collecting one language and joining it to a source using the other is where a great many matching errors start.

Technically the site renders from structured data rather than serving static documents, so the collection design is the same as on other modern league sites: read the structured layer where it is available, render pages only where necessary, keep the request count low.

Get a Quote
dev_w
25

Developers

customers
500+

Customers worldwide

pages
1 500 000 000+

Pages extracted

stime
15000+

Hours saved for our clients

Plans

Airplane

€199 / one-time

setup fee - included

Data limits100,000
Frequencyone-time
Run timeup to 5 days
Data storing7 days

Helicopter

€169 / mo

setup fee €499

Data limits250,000
Frequencymonthly
Run timeup to 5 days
Data storing14 days

Glasses

€229 / mo

setup fee €499

Data limits1,000,000
Frequencyweekly
Run timeup to 5 days
Data storing30 days

DNA

€549 / mo

setup fee €799

Data limits3,000,000
Frequency3 times daily
Run timesame day
Data storing90 days

Why the official source is the reconciliation baseline

Any product built on several sports sources eventually finds two of them reporting a different assist, a different attendance or a different disciplinary total. Somebody has to be authoritative, and for a competition's own data that is the competition.

So this source is usually configured as the baseline and the others are checked against it, with disagreements surfaced rather than silently resolved by whichever source loaded last. Those disagreements are few and highly informative when they appear, because they show which source drifts and where.

The second reason is the second division. Collecting both, and recording promotion and relegation as its own fact, is what makes a club's trajectory read as one continuous line instead of breaking in the season it went down.

The third is language. Spanish football coverage is substantially Spanish language, and a dataset built only from English renderings will mismatch clubs and players against Spanish sources. Keeping both name forms costs almost nothing once the pipeline exists and prevents a class of join failure that is very hard to debug later.

The fourth is that the structured layer makes all of this cheap: collecting a full season of detail is a modest number of requests rather than a crawl, which is better for the budget and better for the league's servers.

Our Blog

Reads Our Latest News & Blog

Learn how to use web scraping to solve data problems for your organization

How Artificial Intelligence Is Used In Web Scraping

How Artificial Intelligence Is Used In Web Scraping

Leveraging advances in technology, the AI-powered web scraper has skyrocketed in demand and is helping to expand capabilities by automating tedious daily tasks and speeding up data collection from thousands of websites several times over.

What is Web Scraping and What is it Used For?

What is Web Scraping and What is it Used For?

Web scraping is a method of obtaining web data by extracting it from pages of web resources with the help of a program, that is, in automatic mode. It is used to syntactically convert web pages into more usable forms.

Web Scraping for Machine Learning

Web Scraping for Machine Learning

If you specialize in machine learning, you need to feed large amounts of data to the algorithms. Web scraping is the easiest and the most efficient method of collecting the data from all over the Internet.

scrapeit logo

Who builds and keeps your LaLiga feed

ScrapeIt is a managed extraction company, not a tool you have to learn. Our team builds the pipeline, watches it through the season and across the promotion cycle, and repairs it before matchday.

You see a sample first, in your format, across the divisions and seasons you need, including a club that has moved between divisions so you can see the history stays continuous.

FAQ

Why collect the official site if an aggregator already has the fixtures?

Because it settles disagreements. Any product on several sources eventually finds two of them reporting a different assist or attendance, and somebody has to be authoritative. For a competition's own data that is the competition. Clients configure this as the baseline and check the others against it.

Do you collect the second division?

Yes, and you should. Without it your dataset breaks silently for every relegated club: it stops appearing, then returns two years later with different numbers, and any analysis across the relegation is impossible. Both divisions sit on the same site, so collecting them together costs little.

Spanish or English edition?

Both, when it matters, and it usually does. Club and player names render differently between editions and Spanish accents appear stripped in URLs but present in body text. Keeping both name forms is what allows the data to join against Spanish language sources without mismatching clubs.

Are tables stored for every matchday?

Yes, for both divisions. A final table says who won; a table per matchday shows when the season turned and how long a club spent in trouble. Reconstructing that later from results is unreliable, particularly where deductions apply.

How far back can you go?

Several seasons, and because past seasons never change the backfill is collected once and never revisited. Most clients start with a multi season panel and add a light in season feed around matchdays. Delivery is CSV, Excel, JSON, JSONLines or XML over FTP, SFTP, Amazon S3, Google Cloud Storage, Dropbox, Google Drive or email, or written straight into your database.

How does it Work?

Step 1 - Make a Request

You share your needs, expectations, and desired timeframe. We’ll suggest the best solution based on your request and budget.

Step 2 - Configuring Custom Web Crawlers

Our specialists configure the crawlers and extract a sample dataset for your review before proceeding with the full-scale extraction.

Step 3 - Collect and Deliver

Once you approve the sample, we launch the project and start full data collection. We gather, filter, and structure the data for easy use, delivering it on time in your preferred format.

Step 4 - Maintain and Support

Our team manages ongoing processes, monitors website changes, and supports all data extraction cycles. We can also help integrate data into your systems or create dashboards to simplify analysis.

Request a Quote

Tell us more about you and your project information.
Which sites, which fields, how often. A couple of lines is enough.

We reply within 1 business day. No obligation.

scrapiet

Scrapeit Sp. z o.o.
10/208 Legionowa str., 15-099, Bialystok, Poland
NIP: 5423457175
REGON: 523384582